Showing posts with label wiki. Show all posts

Thursday, September 08, 2022

Local global identifiers for decentralised wikis

I've been thinking a bit about how one could use a Markdown wiki-like tool such as Obsidian to work with taxonomic data (see earlier posts Obsidian, markdown, and taxonomic trees and Personal knowledge graphs: Obsidian, Roam, Wikidata, and Xanadu).

One "gotcha" would be how to name pages. If we treat the database as entirely local, then the page names don't matter, but what if we envisage sharing the database, or merging it with others (for example, if we divided a taxon up into chunks, and different people worked on those different chunks)?

This is the attraction of globally unique identifiers. You and I can independently work on the same thing, such as data linked to scientific paper, safe in the knowledge that if we both use the DOI for that paper we can easily combine what we've done. But global identifiers can also be a pain, especially if we need to use a service to look them up ("is there a DOI for this paper?", "what is the LSID for this taxonomic name?").

Life would be easier if we could generate identifiers "locally", but had some assurance that they would be globally unique, and that anyone else generating an identifier for the same thing would arrive at the same identifier (this eliminates things such as UUIDs which are intentionally designed to prvent people genrrating the same identifier). One approach is "content addressing" (see, e.g. Principles of Content Addressing - dead link but in the Wayabck Machine, see also btrask/stronglink). For example, we can generate a cryptographic hash of a file (such as a PDF) and use that as the identifier.

Now the problem is that we have globally unique, but ugly and unfriendly identifiers (such as "6c98136eba9084ea9a5fc0b7693fed8648014505"). What we need are nice, easy to use identifiers we can use as page names. Wikispecies serves as a possible role model, where taxon names serve as page names, as do simplified citations (e.g., authors and years). This model runs into the problem that taxon names aren't unique, nor are author + year combinations. In Wikispecies this is resolved by having a centralised database where it's first come, first served. If there is a name clash you have to create a new name for your page. This works, but what if you have multiple databases un by different people? How do we ensure the identifiers are the same?

Then I remembered Roger Hyam's flight of fantasy over a decade ago: SpeciesIndex.org – an impractical, practical solution. He proposed the following rules to generate a unique URI for a taxonomic name:

  • The URI must start with "http://speciesindex.org" followed by one or more of the following separated by slashes.
  • First word of name. Must only contain letters. Must not be the same as one of the names of the nomenclatural codes (icbn or iczn). Optional but highly recommended.
  • Second word of name. Must only contain letters and not be a nomenclatural code name. Optional.
  • Third word of name. Must only contain letters and not be a nomenclatural code name. Optional.
  • Year of publication. Must be an integer greater than 1650 and equal to or less than the current year. If this is an ICZN name then this should be the year the species (epithet) was published as is commonly cited after the name. If this is an ICBN name at species or below then it is the date of the combination. Optional. Recommended for zoological names if known. Not recommended for botanical names unless there is a known problem with homonyms in use by non-taxonomists.
  • Nomenclatural code governing the name of the taxon. Currently this must be either 'icbn' or 'iczn'. This may be omitted if the code is unknown or not relevant. Other codes may be added to this list.
  • Qualifier This must be a Version 4 RFC-4122 UUID. Optional. Used to generate a new independent identifier for a taxon for which the conventional name is unknown or does not exist or to indicate a particular taxon concept that bears the embedded name.
  • The whole speciesindex.org URI string should be considered case sensitive. Everything should be lower case apart from the first letter of words that are specified as having upper case in their relevant codes e.g. names at and above the rank of genus.

Roger is basically arging that while names aren't unique (i.e., we have homonyms such as Abronia) they are pretty close to being so, and with a few tweaks we can come up with a unique representation. Another way to think about this if we had a database of all taxonomics, we could construct a trie and for each name find the shortest set of name parts (genus, species, etc), year, and code that gave us a unique string for that name. In many cases the species name may be all we need, in other cases we may need to add year and/or nomenclatural code to arrive at a unique string.

What about bibliographic references? Well many of us will have databases (e.g., Endnote, Mendeley, Zotero, etc.) which generate "cite keys". These are typically short, memorable identifiers for a reference that are unique within that database. There is an interesting discussion on the JabRef forum regarding a "Universal Citekey Generator", and source code is available cparnot/universal-citekey-js. I've yet to explore this in detail, but it looks a promising way to generate unique identifiers from basic metadata (echos of more elaborate schemes such as SICIs). For example,

Senna AR, Guedes UN, Andrade LF, Pereira-Filho GH. 2021. A new species of amphipod Pariphinotus Kunkel, 1910 (Amphipoda: Phliantidae) from Southwestern Atlantic. Zool Stud 60:57. doi:10.6620/ZS.2021.60-57.
becomes "Senna:2021ck". So if two people have the same, core, metadata for a paper they can generate the same key.

Hence it seems with a few conventions (and maybe some simple tools to support them) we could have decentralised wiki-like tools that used the same identifiers for the same things, and yet those identfiiers were short and human-friendly.

Wednesday, August 26, 2020

Personal knowledge graphs: Obsidian, Roam, Wikidata, and Xanadu


I stumbled across this tweet yesterday (no doubt when I should have been doing other things), and disappeared down a rabbit hole. Emerging, I think the trip was worth it.


Markdown wikis


Among the tools listed by @zackfan01 were Obsidian and Roam, neither of which I heard of before. Both Obsidian and Roam are pitched as "note-taking" apps, they are essentially personal wikis where you write text in Markdown and use [[some text goes here]] to create links to other pages (very like a Wiki). Both highlight backlinks, that is, clearly displaying "what links here" on each page, making it easy to navigate around the graph you are creating by linking pages. Users of Obsidian share these graphs in Discord, rather like something from Martin MacInnes' novel "Gathering Evidence". Personal wikis have been around for a long time, but these apps are elegantly designed and seem fun to use. Looking at these apps I'm reminded of my earlier post Notes on collections, knowledge graphs, and Semantic Web browsers where I moaned about the lack of personal knowledge graphs that supported inference from linked data. I'm also reminded of the Blue Planet II, the BBC, and the Semantic Web: a tale of lessons forgotten and opportunities lost where I constructed an interactive tool to navigate BBC data on species and their ecology (you can see this live at https://rdmpage.github.io/bbc-wildlife/www/), and the fun to be had from simply being able to navigate around a rich set of links. I imagine these Markdown-based wikis could be a great way further explore these ideas.


Personal and global knowledge graphs


Then I began thinking about what if the [[page links]] in these personal knowledge graphs were not just some text but, say, a Wikidata identifier (of the form "Qxxxxx")? Imagine that if you were writing notes on say, a species, you could insert the Wikidata Qid and you would get a pre-populated template that comes with some facts from Wikidata, and you could then use that as a starting point (see for example Toby Hudson Entity Explosion I discussed earlier). Knowing that more and more scholarly papers are being added to Wikidata, this means you could also add bibliographic citations as Qids, fetching all the necessary bibliographic information on the fly from Wikidata. So your personal knowledge graph intersects with the global graph.


Roam


Now, I've not used Roam, but anyone who has is likely to balk at my characterisation of it as "just" a Markdown wiki, because there's more going on here. The Roam white paper talks about making inferences from the text using reasoning or belief networks, although these features don't seem to have had much uptake. But what really struck me as I explored Roam was the notion of not just linking to pages using the [[ ]] syntax, but also linking to parts of pages (blocks) using (( )). In the demo of Roam there are various essays, such as Paul Graham's The Refragmentation, and each paragraph is an addressable block that can be cited independently of the entire essay. Likewise, you can see what pages cite that block.


 Now in a sense these are just like fragment identifiers that we can use to link to parts of a web page, but there's something more here because these fragments are not just locations in a bigger document, they are the components of the document.

Xanadu


This strikes me as rather like Ted Nelson's vision of Xanadu, where you could cite any text at any level of granularity, and that text would be incorporated into the document you were creating via transclusion (i.e., you don't include a copy of the text, you include the actual text). In the context of Roam, this means you have the entire text you want to cite included in the system, so you can then show chunks of it and build up a network of ideas around each chunk. This also means that the text being worked on becomes part of the system, rather than remaining isolated, say, as a PDF or other representation. This also got me thinking about the Plazi project, where taxonomic papers are being broken into component chunks (e.g., figures, taxonomic descriptions, etc.) and these are then being stored in various places and reassembled - rather like Frankenstein's monster - in new ways, for example in GBIF (e.g., https://www.gbif.org/species/166240579) or Species-ID (see doi:10.3897/zookeys.90.1369 ). One thing I've always found a little jarring about this approach is that you lose the context of the work that each component was taken from. Yes, you can find a link to the original work and go there, but what if you could seamlessly click on the paragraph or figure see them as part of the original article? Imagine we had all the taxonomic literature available in this way, so that we can cite any chunk, remix it (which is a key part of floras and other taxonomic monographs), but still retain the original context?

Summary


To come back full circle, in some ways tools like Obsidian and Roam are old hat, we've had wikis for a while, the idea of loading texts into wikis is old (e.g., Wikisource), backlinks are nothing new, etc. But there's something about seeing clean, elegant interpretations of these ideas, free of syntax junk, and accompanied by clear visions of how software can help us think. I'm not sure I will use either app, but they have given me a lot of food for thought.

Friday, April 04, 2014

More on annotating biodiversity data: beyond sticky notes and wikis

Following on from the previous post Rethinking annotating biodiversity data, here are some more thoughts on annotating biodiversity data.

Annotations as sticky notes


I get the sense that most people think of annotations as "sticky notes" that someone puts on data. In other words, the data is owned by somebody, and anyone who isn't the owner gets to make comments, which the owner is free to use or ignore as they see fit. With this model, the focus is on how the owner deals with the annotations, and how they manage the fact that their data may have changed since the annotations were made.

This model has limitations. For a start, it privileges the "owner", and puts annotators at their mercy. For example, I posted an issue regarding a record in the Museum of Comparative Zoology Herpetology database (see https://github.com/mcz-vertnet/mcz-subset-for-vertnet/issues/1). VertNet has adopted GitHub to manage annotations of collection data, which is nice, but it only works if there's someone at the other end ready to engage with people like me who are making annotations. I suspect this is mostly not going to be the case, so why would I bother annotating the data? Yes, I know that VertNet has only just set this up, but that's missing the point. Supporting this model requires customer support, and who has the resources for that? If I don't get the sense that someone is going to deal with my annotation, why bother?

So, the issues here are that the owner gets all the rights, the annotators have none, and in practice the owners might not be in a position to make use of the annotations anyway.

Wikis


OK, if the owner/annotator model doesn't seem attractive, what about wikis? Let's put the data on a wiki and let folks edit it, that'll work, right? There's a lot to be said in favour of wikis, but there's a disadvantage to the basic wiki model. On a wiki, there is one page for an item, and everyone gets to edit that same page. The hope is that a consensus will emerge, but if it doesn't then you get edit wars (e.g., When taxonomists wage war in Wikipedia). If you've made an edit, or put your data on a wiki, anyone can overwrite it. Sure, you can roll back to an earlier version, but so can anyone else.

Wikis bring tools for community editing, but overturn ownership completely, so the data owner, or indeed any individual annotator has no control over what happens to their contributions. Why would an expert contribute if someone else can undo all their hard work?

Social data


So, if sticky notes and wikis aren't the solution, what is? I've been looking at Fluidinfo lately. There's an interview here, and a book here. The company has gone quiet lately (apparently focussing on enterprise customers), but what matters here is the underlying idea, namely "social data".

Fluidinfo's model is that it is a database of objects (representing things or concepts), and anyone can add data to those objects (they are "openly writable"). The key is that every tag is linked to the user, and by default you can only add, edit, or delete your own tags. This means that if a data provider adds, say a bibliographic reference to the database, I can edit it by adding tags, but I can't edit the data provider's tags. To make this a bit more concrete, suppose we have a record for the article with the DOI 10.1163/187631293X00262. We can represent the metadata from CrossRef like this:

{
"_id": "10.1163/187631293X00262",
"crossref/doi" : "10.1163/187631293X00262",
"crossref/title" : "A taxonomic review of the pondskater...",
"crossref/journal" : "Insect Systematics & Evolution",
"crossref/issn" : [ "1399-560X", "1876-312X"]
}

Note the use of the namespace "crossref" in the tags. This is data that, notionally, CrossRef "owns" and can edit, and nobody else. Now, as I've discussed earlier (Orwellian metadata: making journals disappear) some publishers have an annoying habit of retrospectively renaming journals. This article was published in Entomologica Scandinavica, which has since been renamed Insect Systematics & Evolution, and CrossRef gives the latter as the journal name for this article. But most citations to the article will use the old journal name. Under the social data model, I can add this information (in bold):

{
"_id": "10.1163/187631293X00262",
"crossref/doi" : "10.1163/187631293X00262",
"crossref/title" : "A taxonomic review of the pondskater...",
"crossref/journal" : "Insect Systematics & Evolution",
"crossref/issn" : ["1399-560X", "1876-312X"],
"rdmpage/journal" : "Entomologica Scandinavica","rdmpage/issn" : ["0013-8711" ]
}

My tags have the namespace "rdmpage", so they are "mine". I haven't overwritten the "crossref" tags. Somebody else could add their own tags, and of course, CrossRef could update their tags if they wish. We can all edit this object, we don't need permission to do so, and we can rest assured that our own edits won't be overwritten by somebody else.

This model can be quite liberating. If you are a data provider/owner, you don't have to worry about people trampling over your data, because you (and any users of your data) can simply ignore tags not in your namespace ("ignore those rdmpage' tags, that Rod Page chap is clearly a nutter"). Annotators are freed from their reliance on data providers doing anything with the annotations they created. I don't care whether CrossRef decides to revert the journal name Insect Systematics & Evolution to Entomologica Scandinavica for earlier article (or not), I can just use the "rdmpage/journal" (if it exists) to get what I think is the appropriate journal name. My annotations are immediately usable. Because everyone gets to edit in their own namespace, we don't need to form a consensus, so we don't need the version control feature of wikis to enable roll backs, there are no more edit wars (almost).

Implementation


A key feature of the Fluidinfo social data model is that the data is stored in a single, globally accessible place. Hence we need a global annotation store. Fluidinfo itself doesn't seem to have a publicly accessible database, I guess in part because managing one is a major undertaking (think Freebase). Despite Nicholas Tollervey's post (FluidDB is not CouchDB (and FluidDB's secret sauce)), I think CouchDB is exactly the way I'd want to implement this (it's here, it works, and it scales). The "secret sauce" is essentially application logic (every key has a namespace corresponding to a given user).

The more I think about this model the more I like it. It could greatly simplify the task of annotating biodiversity data, and avoid what I fear are going to be the twin dead ends of sticky note annotation and wikis.

Saturday, June 02, 2012

Linking NCBI taxonomy to GBIF


In response to Rutger Vos's question I've started to add GBIF taxon ids to the iPhylo Linkout website. If you've not come across iPhylo Linkout, it's a Semantic Mediawiki-based site were I maintain links between the NCBI taxonomy and other resources, such as Wikipedia and the BBC Nature Wildlife finder. For more background see

Page, R. D. M. (2011). Linking NCBI to Wikipedia: a wiki-based approach. PLoS Currents, 3, RRN1228. doi:10.1371/currents.RRN1228

I'm now starting to add GBIF ids to this site. This is potentially fraught with difficulties. There's no guarantee that the GBIF taxonomy ids are stable, unlike NCBI tax_ids which are fairly persistent (NCBI publish deletion/merge lists when they make changes). Then there are the obvious problems with the GBIF taxonomy itself. But, if you want a way to generate a distribution map for a taxon in the NCBI taxonomy, the quickest way is going to be via GBIF.

The mapping is being made automatically, with some crude checks to try and avoid too many erroneous links (e.g., due to homonyms). It will probably take a few days to complete (the mapping is quick, uploading to the wiki is a bit slower). Using a wiki to manage the mapping makes it easy to correct any spurious matches.

As an example, the page http://iphylo.org/linkout/Ncbi:109175 is for the frog Hyla japonica (NCBI tax_id 109175) and shows links to Wikipedia (http://en.wikipedia.org/wiki/Japanese_Tree_Frog, and to GBIF (http://data.gbif.org/species/2427601/). There's even a link to TreeBASE. I display a GBIF map so you can see what data GBIF currently has for that taxon.

Hyla

So, we have a wiki page, how do we answer Rutger's original question: how to get GBIF occurrence records via web service?

To do this we can use the RDF output by the Semantic Mediawiki software that underpins the Wiki. You can gte this by clicking on the RDF icon near the bottom of the page, or go to http://iphylo.org/linkout/Special:ExportRDF/Ncbi:109175. The RDF this produces is really, really ugly (and people wonder why the Semantic Web has been slow to take off...). In this RDF you will see the statement:

<rdfs:seeAlso rdf:resource="http://data.gbif.org/species/2427601/"/>

So, arm yourself with XPath, a regular expression, or if you are a serious RDF geek break out the SPARQL, and you can extract the GBIF taxon id for a NCBI taxon. Given that id you can query the GBIF web services. One service that I like is the occurrence density service, which you can use to recreate the 1°×1° density maps shown by GBIF. For example, http://data.gbif.org/ws/rest/density/list?taxonconceptkey=2427601 will get you the squares shown in the screen shot above.

Of course, I have glossed over several issues, such as the errors and redundancy in the GBIF classification, the mismatch between NCBI and GBIF classifications (NCBI has many more ranks than GBIF), and whether the taxon concepts used by the two databases are equivalent (this is likely to be more of an issue for higher taxa). But it's a start.

Wednesday, May 30, 2012

The GBIF classification is broken — how do we fix it?

This post arose from an ongoing email conversation with Tony Rees about extracting and annotating taxonomic names. In BioStor I use the GBIF classification to display the taxonomic names found in the OCR text in the form of a tree. The idea is to give the reader a sense of "what the paper is about". I also use the classification to help link to GBIF occurrence records.

The GBIF backbone classification ("nub") is probably the single largest classification of life that has been assembled, and provides GBIF users with a way to navigate through GBIF's collection of specimen and observation records. Given the scale of the undertaking it is inevitable that there will be issues with the classification, and this post provides one example.

On the page for the article "Further additions to the known marine Molluscan fauna of St. Helena" (http://biostor.org/reference/88554, see also http://dx.doi.org/10.1080/00222939208677383) part of the classification looks like this:

└Animalia
└Annelida
└Polychaeta
└Sabellida
└Serpulidae
└Hipponyx
Tony points out that "Hipponyx" is a mollusc, yet in the GBIF classification appears in the annelid worms.

Like a fool I started to investigate further. First off, what is "Hipponyx"? Browsing the GBIF classification there are species of Hipponyx and Hipponix under the genus Hipponix, so it looks like we have two alternative spellings of this genus name. Nomenclator Zoologicus has both spellings, Hipponix credited to DeFrance 1819 Journ. de Physique, 88, 217, and Hipponyx credited to Defrance 1819 Bull. Sci. Soc. philom. Paris, 8. Gotta love those cryptic citations. After some digging around in BHL I found Journ. de Physique, 88, 217 (Mémoire sur un nouveau genre de mollusque) and Bull. Sci. Soc. philom. Paris, 8. (Sur un nouveau genre de coquilles (Hipponix)). Both papers are by Jacques Louis Marin DeFrance, and both use the spelling Hipponix (no 'y'). I'm guessing the second paper is actually the original description of the genus, but my French is abysmal (Google Translate to the rescue).

OK, so we have two spellings of what is probably the same thing (and I've no idea why we have two spellings). Both spellings seem in use (see Google NGrams chart below).

Ngram

So, bit of a mess, but this still doesn't deal with Hipponyx being a worm in GBIF. After a bit of Googling on "Serpulidae" and "Hipponyx" I came across a specimen record from Te Papa labelled "Worm, Temporaria inexpectata (Mestayer, 1929); holotype; holotype of Hipponyx inexpectata Mestayer, 1929". I then came across this paper:

Fleming, C. A. (1971). A preliminary list of New Zealand fossil polychaetes. New Zealand Journal of Geology and Geophysics, 14(4), 742–756. doi:10.1080/00288306.1971.10426332

with the following abstract:
An annotated list of fossil “worm tubes” from New Zealand includes both published and new records from Mesozoic and Cenozoic deposits.

The binomen Zoophycos plicatus (Hutton) is proposed for the trace fossil long known as the Amuri fucoid, of unknown zoological affinity.

The following living species are recorded as New Zealand fossils for the first time: Protula bispiralis (Savigny), Salmacina dysteri (Huxley), Hydroides norvegicus Gunnerus, Pomatoceras cariniferus (Gray), P. aff. terranovae (Benham), Galeolaria hystrix (Moerch), Boccardia ? polybranchia (Haswell); new records of fossil species are Ditrupa cf. plana (Sowerby), Dorsoserpula lumbricalis (Schlotheim), and Neomicrorbis crenatostriatus (Münster). The name Hipponyx inexpectata Mestayer 1929, applied to a serpulid operculum, is used in the combination Temporaria inexpectata for a tubeworm common in deep water off New Zealand that has also been identified, with associated operculum, from the bathyal Waitotaran (Pliocene) sediments of Palliser Bay. Serpula wharjensis Wilkens and S. ougenensis Chapman are placed in Sclerostyla Moerch. Two species of Vermiliopsis and two of Spirorbis are figured but not named specifically.

The author of the paper (Charles Fleming) argues that Hipponyx inexpectata, regarded as a mollusc by its describer (Marjorie K. Mestayer, see Notes on New Zealand Mollusca. No. 4.) is actually a worm, and he moves it to the genus Temporaria.

So it seems that the reason Hipponyx has ended up being a worm in the GBIF classification is due to this synonymy.

Now, this little investigation was "fun", but took a couple of hours. Much of that was spent tracking down the literature and adding it to BioStor, which is a one-time cost. Not every issue with the GBIF classification will take this long to resolve, some cases may take longer. So there's a problem of scalability. Then there's the issue of how this information gets into the GBIF classification so we fix it (and so that people don't think Hipponyx is a worm). As has been said several times before, most eloquently by David Shorthouse, isn't it time we started using software development tools such as version control to help build, annotate, and correct classifications such as the one that underpins GBIF? That way when somebody spots an error it can be flagged, and someone with the time (and curiosity) can fix it.

Thursday, March 01, 2012

Yet more reasons to have specimen identifiers: annotating GenBank sequences

One reason I'm pursuing the theme of specimen identifiers (and identifiers in general) is the central role they play in annotating databases. To give a concrete example, I (among others) have argued for a wiki-style annotation layer on top of GenBank to capture things such as sequencing errors, updated species names, etc. Annotation is a lot easier if we have consistent identifiers for the things being annotated. For example, every GenBank sequence has a unique accession number, so if you and I are discussing sequence DQ055738, you and I can be sure we are talking about the same thing.

Sequence DQ055738 is interesting because Hua et al. A Revised Phylogeny of Holarctic Treefrogs (Genus Hyla) Based on Nuclear and Mitochondrial DNA Sequences (http://dx.doi.org/10.1655/08-058R1.1 - note the nice identifier we have for this article) have suggested this sequence (published in http://dx.doi.org/10.1554/05-284.1, another nice identifier) is misidentified. Given these identifiers we could construct various statements, such as:


DQ055738 -> published in -> doi:10.1554/05-284.1
DQ055738 -> annotated by -> doi:10.1655/08-058R1.1

(I've omitted the http:// stuff to keep things legible). Hua et al: state the following:

However, the tissue number of this specimen (LSUMZ H-19067) is similar to that of a specimen of H. versicolor (LSUMZ H-19077), which appears to have been processed at the same time (C. Austin, personal communication). Therefore, we hypothesize that the sequence data for H. gratiosa used by Smith et al. (2005) were actually from H. versicolor.

It would be nice if we had unique, resolvable identifiers for LSUMZ H-19067 and LSUMZ H-19077 so that we could construct statements linking the sequence, the publications, and the specimens. But we don't. Nor is it obvious how to find out anything more about LSUMZ H-19067 and LSUMZ H-19077. By contrast, for the DOI or the sequence accession I know how to get more information, in either human- or machine-readable form.

The acronym LSUMZ in this case is the Lousiana State University Museum of Natural Science Herpetology collection (http://biocol.org/urn:lsid:biocol.org:col:34806). Just to confuse matters, LSUMZ specimens in GBIF use LSU as the acronym for Lousiana State University Museum of Natural Science. Given that GBIF's data comes from LSU itself, it's odd (but not surprising) that there's a muddle about which acronym to use (it would be nice to clear this up, but then anybody building identifiers based on those acronyms is in for some heartbreak).

If I look at GBIF LSUMZ records there aren't specimens with the catalogue numbers H-19067 or H-19077. However, after a bit of poking around, and a helpful file from GBIF's Tim Robertson, I discovered that the LSUMZ herpetology tissue numbers (which is what the H-* codes actually are) are stored in GBIF, so I've found the corresponding specimens are http://data.gbif.org/occurrences/45716232 (LSU Herp 84850, LSUMZ HerpNet Tissue 19067) and http://data.gbif.org/occurrences/45710033 (LSU Herp 84862, LSUMZ HerpNet Tissue 19077). (Note that Hua et al. tell the reader that LSU 84850 = LSUMZ H-19067, but don't give the specimen code for LSUMZ H-19077).

Now I have some resolvable identifiers, so I could construct statements like:


DQ055738 -> voucher -> occurrences/45716232
DQ055738 -> voucher -> occurrences/45710033
|
+-> according to -> doi:10.1655/08-058R1.1

Let's skip over whether this is actually the best way to record the annotation, the point is we can now start to construct statements that can be linked to the wider world. If someone else has made statements about these specimens, and they used the GBIF URL, then we could aggregate those and learn more about these specimen and their associated sequences. Without globally unique, stable, resolvable identifiers we are left to flounder around in the bowels of various databases searching for something that may or may not be the object being discussed. Isn't it time we did something about this?

Thursday, March 24, 2011

TreeBASE meets NCBI, again

Déjà vu is a scary thing. Four years ago I released a mapping between names in TreeBASE and other databases called TBMap (described here: doi:10.1186/1471-2105-8-158). Today I find myself releasing yet another mapping, as part of my NCBI to Wikipedia project. By embedding the mapping in a wiki, it can be edited, so the kinds of problems I encountered with TbMap, recounted here, here, and here. The mapping in and of itself isn't terribly exciting, but it's the starting point for some things I want to do regarding how to visualise the data in TreeBASE.

Because TreeBASE 2 has issued new identifiers for its taxa (see TreeBASE II makes me pull my hair out), and now contains its own mapping to the NCBI taxonomy, as a first pass I've taken their mapping and added it to http://iphylo.org/linkout. I've also added some obvious mappings that TreeBASE has missed. There are a lot more taxa which could be added, but this is a start.

The TreeBASE taxa that have a mapping each get their own page with a URL of the form http://iphylo.org/linkout/<TreeBase taxon identifier>, e.g. http://iphylo.org/linkout/TB2:Tl257333. This page simply gives the name of the taxon in TreeBASE and the corresponding NCBI taxon id. It uses a Semantic Mediawiki template to generate a statement that the TreeBASE and and NCBI taxa are a "close match". If you go to the corresponding page in the wiki for the NCBI taxon (e.g., http://iphylo.org/linkout/Ncbi:448631) you will see any corresponding TreeBASE taxa listed there. If a mapping is erroneous, we simply need to edit the TreeBASE taxon page in the wiki to fix it. Nice and simple.

At the time of writing the initial mapping is still being loaded (this can take a while). I'll update this post when the uploading has finished.

Tuesday, May 11, 2010

Why we need wikis

I've just spent a frustrating few minutes trying to find a reference in BioStor. The reference in question is
Heller, Edmund 1901. Papers from the Hopkins Stanford Galapagos Expedition, 1898-1899. WIV. Reptiles. Proc. Biol. Soc. Washington 14: 39-98

and comes from the Reptile Database page for the gecko Phyllodactylus gilberti HELLER, 1903. This is primary database for reptile taxonomy, and supplies the Catalogue of Life, which repeats this reference verbatim.
Thing is, this reference doesn't exist! Page 39 of Proc. Biol. Soc. Washington volume 14 is the start of Gerrit S Miller (1901) A new dormouse from Italy. Proc Biol Soc Washington 14: 39-40.
After much fussing with trying diferent volumes and dates for Proc. Biol. Soc. Washington, I searched BHL for Phyllodactylus gilberti, and discovered that this name was published in Proceedings of the Washington Academy of Sciences:
Edmund Heller (1903) Papers from the Hopkins Stanford Galapagos Expedition, 1898-1899. XIV. Reptiles. Proceedings of the Washington Academy of Sciences 5: 39-98

(see http://biostor.org/reference/20322). Three errors (wrong journal, wrong date, minor typo in title), but enough to break the link between a name and the primary source for that name.

Anybody who demands authoritative, expert-vetted resources, and thinks the Catalgoue of Life is a shining example of this needs to think again. Our databases are riddled with errors, which are repackaged over and over again, yet these would be so easy to fix if they were opened up and made easy to edit. It's time to get serious about wikis.

Thursday, March 25, 2010

Wiki frustration

Yesterday I fired off a stream of tweets, starting with:
OK, I'm back to hatin' on the wikis. It's just way to hard to do useful queries (e.g., anything that requires a path linking some entities) [10991434609]

Various people commented on this, either on twitter or in emails, e.g.:
@rdmpage hatin' wikis is irrational - all methods have pros and cons, so wikis are an essential resource among others [@stho002]

So, to clarify, I'm not abandoning wikis. I'm just frustrated with the limitations of Semantic Mediawiki (SMW). Now, SMW is a great piece of software with some cool features. For example,

  1. Storing data in Mediawiki templates (i.e., key-value pairs) makes it rather like a JSON database with version control (shades of CouchDB et al.).

  2. Having Mediawiki underlying SMW makes lots of nice editing and user management features available for free.

  3. The template language makes it relatively easy to format pages.

  4. It is easy to create forms for data entry, so users aren't confronted with editing Mediawiki templates unless they want to.

  5. Supports basic queries.


It's the last item on the list that is causing me grief. The queries are, well, basic. What SMW excels at are queries connecting one page to another. For example, if I create wiki pages for publications, and list the author of each publication, the page for an author can contain a simple query (of the form {{ #ask: [[maker::Author 1]] | }}) that lists all the publications of that author:

q1.png


That's great, and many of the things are want to do can be expressed in this simple way (i.e., find all pages of a certain kind that link to the current page). It's when I want to go more than one page away that things start to go pear shaped. For example, for a given taxon I want to display a map of where it is found, based things like geoferenced GenBank sequences, or sequences from georeferenced museum specimens.

q2.png
This can involve a path between several entities ("pages" in SMW), and this just doesn't seem to be possible. I've managed to get some queries working via baroque Mediawiki templates, but it's getting to the point where hours seem to be wasted trying to figure this stuff out.

So, what tends to happen is I develop something, hit this brick wall, then go and do something else. I suspect that one way forward is to use SMW as the tool to edit data and display basic links, then use another tool to do the deeper queries. This is a bit like what I'm exploring with BioStor, where I've written my own interface and queries over a simple MySQL database, but I'm looking into SMW + Wikisource to handle annotation.

This leaves the question of how to move forward with http://iphylo.org/treebase/? One approach would be to harvest the SMW pages regularly (e.g., by consuming the RSS feed, and either pulling off SMW RDF or parsing the template source code for the pages), use this to populate a database (say, a key-value store or a triple store) where more sophisticated queries can be developed. I guess one could either make this a separate interface, or develop it as a SMW extension, so results could be viewed within the wiki pages. Both approaches have merits. Having a complete separate tool that harvests the phylogeny wiki seems attractive, and in many ways is an obvious direction for iSpecies to take. Imagine iSpecies rebuilt as an RDF aggregator, where all manner of data about a taxon (or sequences, or specimen, or publication, or person) could be displayed in one place, but the task of data cleaning took place elsewhere.

Food for thought. And, given that it seems some people are wondering why on earth I bother with this stuff, and can't I just finish TreeView X, I could always go back to fussing with C++…

Tuesday, March 16, 2010

Progress on a phylogeny wiki

I've made some progress on a wiki of phylogenies. Still much to do, but here are some samples of what I'm trying to do.

First up, here's an example of a publication http://iphylo.org/treebase/Doi:10.1016/j.ympev.2008.02.021:
wiki1.png

In addition to basic bibiographic details we have links to GenBank sequences and a phylogeny. The sequences are georeferenced, which enables us to generate a map. At a glance we see that the study area is central America.

This study published the following tree:
wiki2.png

The tree is displayed using my tvwidget. A key task in constructing the wiki is mapping labels used in TreeBASE to other taxonomic names, for example, those in the NCBI taxonomy database. This is something I first started working on in the TbMap project (doi:10.1186/1471-2105-8-158). In the context of this wiki I'm explicitly mapping TreeBASE taxa to NCBI taxa. Taxa are modelled as "namestrings" (simple text strings), OTUs (TreeBASE taxa), and taxonomic concepts (sets of observations or taxa). For example, the tree shown above has numerous samples of the frog Pristimantis ridens, each with a unique label (namestring) that includes, in this case, voucher specimen information (e.g., "Pristimantis ridens La Selva AJC0522 CR"). Each of these labels is mapped to the NCBI taxon Pristimantis ridens.

One thing I'm interested in doing is annotating the tree. Eventually I hope to generate (or make it easy to generate) things such as Google Earth phylogenies (via georeferenced sequences and specimens). For now I'm playing with generating nicer labels for the terminal taxa. As it stands if you download the original tree from TreeBASE you have the original study-specific labels (e.g., "Pristimantis ridens La Selva AJC0522 CR"), whereas it would be nice to also have taxonomic names (for example, if you wanted to combine the tree or data with another study). Below the tree you'll see a NEXUS NOTES block with the "ALTTAXNAMES" command. The program Mesquite can use this command to enable users to toggle between different labels, so that you can have either a tree like this:
wiki3.png

or a tree like this:
wiki4.png

Wednesday, March 03, 2010

Setting up a local Wikisource

A little while ago I came across Wikisource, and it dawned on me that this is a model for BHL. To quote from the Wikisource web site:
Wikisource is an online library of free content publications, collected and maintained by our community. We now have 140,596 texts in the English language library. See our inclusion policy and help pages for information on getting started, and the community portal for ways you can contribute. Feel free to ask questions on the community discussion page, and to experiment in the sandbox.

Much of their content comes from the Internet Archive (as does BHL's), and Wikisource have developed extensions for Mediaiwki to do some cool things, such as extract text and images from DjVu files. If you haven't come across DjVu before, it's a format designed to store scanned documents, and comes with some powerful open source tools for extracting images and OCR text. Wikisource can take a DjVu file, extract images, thumbnails and text, creating side-by-side displays where users can edit and correct OCR text:

wikisource.png


So, like a fool, I decided to try and install some of these tools locally and see if I could do the same for some BHL content. That's when the "fun" started. Normally Mediawiki is pretty easy to set up. There are a few wrinkles because my servers live behind an institutional HTTP proxy, so I often need to tweak some code (such as the OpenID extension, which also needs a fix for PHP 5.3), but installing the extensions that underlie Wikisource wasn't quite so straightforward.

DjVu
djvu.png
The first step is supporting DjVu files in Mediawiki. This seems straightforward (see How to use DjVu with MediaWiki). First off you need the DjVu tools. I use Mac OS X, so I get these automatically if I install DjView. The tools reside in Applications/DjView.app/Contents/bin (you can see this folder if you Control+click on the DjView icon and choose "Show Package Contents"), so adding this path to the name of each tool DjVu tool Mediaiwiki needs takes care of that.

But I also need NetPbm, and now the pain starts. NetPbm won't build on Mac OS X, at least not out of the box on Snow Leopard. It makes assumptions about Unix that Mac OS X doesn't satisfy. After some compiler error messages concerning missing variables that I eventually traced to signal.h I gave up and installed MacPorts, which has a working version of NetPbm. MacPorts installed fine, but it's a pain having multiple copies of the same tools, one in /usr/local, and one in /opt/local.

OK, now we can display DjVu files in Mediawiki. It's small victories like this which leads to over confidence...

Proofread Page
Next comes the Proofread Page extension, which provides the editing functionality. This seemed fairly straightforward, although the documentation referred to a SQL file (ProofreadPage.sql) that doesn't seem to exist. More worringly, the documentation also says:
If you want to install it on your own wiki, you will need to install a 404 handler for generating thumbnails, such as WebStore.

This seems fine, except the page for WebStore states:
The WebStore extension is needed by the ProofreadPage extension. Unfortunately, documentation seems to be missing completely. Please add anything you know about this extension here.

Then there are the numerous statements "doesn't work" scattered through the page. So, I installed the extension and hoped for the best. It didn't work. As in, really, really didn't work. It took an hour or so of potentially fatal levels of blood pressure-inducing frustration to get to the bottom of this.

WebStore
Now, Webstore is a clever idea. Basically, the Proofread Page extension will need thumbnails of images in potentially varying sizes, and creates a link to the image it wants. Since that image doesn't exist on the web site the web server returns 404 Not Found, which normally results in a page like this. Instead, we tell the web server (Apache) that WebStore will handle 404's. If the request is for an image, Webstore creates the image file, streams it to the web browser, then deletes the file from disk. Essentially WebStore creates a web server for images (Webdot uses much the same trick, but without the 404 handler). Debugging a web server called by another web server is tricky (at least for a clumsy programmer like me), but by hacking the Webstore code (and switching on Mediawiki debug logging) I managed to figure out that Webstore seemed to be fetching and streaming the images fine, but they simply didn't appear in the wiki page (I got the little broken image icon instead). I tried alternative ways of dumping the image file to output, adding HTTP headers, all manner of things. Eventually (by accident, no idea how it happened) I managed to get an image URL to display in the Chrome web browser, but it wasn't an image(!) -- instead I got a PHP warning about two methods in the class DjVuHandler (mustRender and isMultiPage) not being consistent with the class they inherit from. WTF?! Eventually I found the relevant file (DjVu.php in includes/media in the Mediawiki folder), added the parameter $file to both methods, and suddenly everything works. At this point I didn't know whether to laugh or cry.

OCR text
There are some issues with OCR text from Internet Archive DjVu files. There are some extraneous characters (new lines, etc.) that I need to filter, and I'll probably have to deal with hyphenation. It looks fairly straightforward to edit the proofing extension code to handle these situations.

Semantic Mediawiki
Having got the proofing extension working, I then wanted to install the Semantic Mediawiki extensions so that I could support basic inference on the wiki. I approached this with some trepidation as there are issues with Mediawiki namespaces, but everything played nice and so far things seem to be working. Now I can explore whether I can combine the proofing tools from Wikisource with the code I've developed for iTaxon.

BioStor
So, having got something working, the plan is to integrate this with BioStor. One model I like is the video site Metacafe. For each video Metacafe has a custom web page(e.g., http://www.metacafe.com/watch/4137093) with an Edit Video Details link that takes you to a Semantic Mediawiki page where you can edit metadata for the video. I envisage doing something similar for BioStor, where my existing code provides a simple view of an article (perhaps with some nice visualisations), with a link to the corresponding wiki page where you can edit the metadata, and correct the OCR text.

Lessons
In the end I got there, although it was a struggle. Mediawiki is a huge, complicated bit of software, and is also part of a larger ecosystem of extensions, so it has enormous power. But there are lots of times when I think it would be easier if I wrote something to replicate the bit of functionality that I want. For example, side-by-side display of text and images would be straightforward to do. But once you start to think about supporting mark-up, user authentication, recording edit history, etc., the idea of using tools others have developed becomes more attractive. And the code is open source, which means if it doesn't work there's a fighting chance I can figure out why, and maybe fix it. It often feels harder than it should be, but I'll find out in the next few days whether yesterday's exertions were worth it.

Monday, November 09, 2009

iTaxon screencast

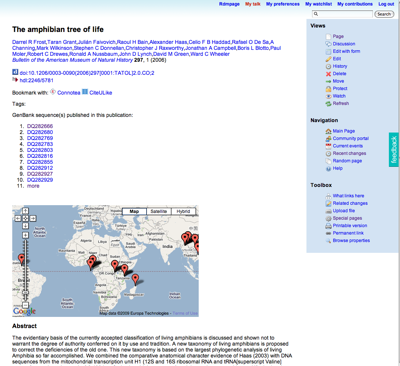
Sadly I won't be at TDWG 2009, at least not in person. However, there is a session on wikis, which may contain this brief screencast of my iTaxon experiments. The screencast was made in haste, but tries to convey some of the ideas behind these experiments, especially the idea that by linking data together we can generate more interesting and rich views of objects such as scientific publications. The screencast starts with the The amphibian tree of life page.


Thursday, September 17, 2009

Towards a wiki of phylogenies

At the start of this week I took part in a biodiversity informatics workshop at the Naturhistoriska riksmuseets, organised by Kevin Holston. It was a fun experience, and Kevin was a great host, going out of his way to make sure myself and other contributors were looked after. I gave my usual pitch along the lines of "if you're not online you don't exist", and talked about iSpecies, identifiers, and wikis.

I also ran a short, not terribly successful exercise using iTaxon to demo what semantic wikis can do. As is often the case with something that hasn't been polished yet, the students found the mechanics of doing things less than intuitive. I need to do a lot of work making data input easier (to date I've focussed on automated adding of data, and forms to edit existing data). Adding data is easy if you know how, but the user needs to know more than they really should have to.

The exercise was to take some frog taxa from the Frost et al. amphibian tree (doi:10.1206/0003-0090(2006)297[0001:TATOL]2.0.CO;2) and link them to GenBank sequences and museum specimens. The hope was that by making these links new information would emerge. You could think of it as an editable version of this. With a bit of post-exercise tidying, we got someway there. The wiki page for the Frost et al.
paper
now shows a list of sequences from that paper (not all, I hasten to add), and a map for those sequences that the students added to the wiki:

frost.png


Although much remains to be done, I can't help thinking that this approach would work well for a database like TreeBASE, where one really needs to add a lot of annotation to make it useful (for example, mapping OTUs to taxon names, linking data to sequences and specimens). So, one of the things I'm going to look at is dumping a copy of TreeBASE (complete with trees) into the wiki and seeing what can be done with it. Oh, and I need to make it much, much easier for people to add data.

Tuesday, August 18, 2009

To wiki or not to wiki?

What follows are some random thoughts as I try and sort out what things I want to focus on in the coming days/weeks. If you don't want to see some wallowing and general procrastination, look away now.

I see four main strands in what I've been up to in the last year or so:
  1. services
  2. mashups
  3. wikis
  4. phyloinformatics
Let's take these in turns.

Services
Not glamourous, but necessary. This is basically bioGUID (see also hdl:10101/npre.2009.3079.1). bioGUID provides OpenURL services for resolving articles (it has nearly 84,000 articles in it's cache), looking up journal names, resolving LSIDs, and RSS feeds.

Mashups
iSpecies is my now aging tool for mashing up data from diverse sources, such as Wikipedia, NCBI, GBIF, Yahoo, and Google Scholar. I tweak it every so often (mainly to deal with Google Scholar forever mucking around with their HTML). The big limitation of iSpecies is that it doesn't make it's results reusable (i.e., you can't write a script to call iSpecies and return data). However, it's still the place I go to to quickly find out about a taxon.

The other mashups I've been playing with focus on taking standardised RSS feeds (provided by bioGUID, see above) and mashing them up, sometimes with a nice front end (e.g., my e-Biosphere 09 challenge entry).

Wiki
I've invested a huge amount of effort in learning how wikis (especially Mediawiki and its semantic extensions) work, documented in earlier posts. I created a wiki of taxonomic names as a sandbox to explore some of these ideas.

I've come to the conclusion that for basic taxonomic and biological information, the only sensible strategy for our community is to use (and contribute to) Wikipedia. I'm struggling to see any justification for continuing with a proliferation of taxonomic databases. After e-Biosphere 09 the game's up, people have started to notice that we've an excess of databases (see Claire Thomas in Science, "Biodiversity Databases Spread, Prompting Unification Call", doi:10.1126/science.324_1632).

Phyloinformatics
In truth I've not been doing much on this, apart from releasing tvwidget (code available from Google Code), and playing with a mapping of TreeBASE studies to bibliographic identifiers (available as a featured download from here). I've played with tvwidget in Mediawiki, and it seems to work quite well.

Where now?
So, where now? Here are some thoughts:
  1. I will continue to hack bioGUID (it's now consuming RSS feeds from journals, as well as Zotero). Everything I do pretty much depends on the services bioGUID provides

  2. iSpecies really needs a big overhaul to serve data in a form that can be built upon. But this requires decisions on what that format should be, so this isn't likely to happen soon. But I think the future of mashup work is to use RDF and triple stores (providing that some degree of editing is possible). I think a tool linking together different data sources (along the lines of my ill-fated Elsevier Challenge entry) has enormous potential.

  3. I'm exploring Wikipedia and Wikispecies. I'm tempted to do a quantitative analysis of Wikipedia's classification. I think there needs to be some serious analysis of Wikipedia if people are going to use it as a major taxonomic resource.

  4. If I focus on Wikipedia (i.e., using an existing wiki rather than try to create my own), then that leaves me wondering what all the playing with iTaxon was for. Well, actually I think the original goal of this blog (way back in December 2005) is ideally suited to a wiki. Pretty much all the elements are in place to dump a copy of TreeBASE into a wiki and open up the editing of links to literature and taxonomic names. I think this is going to handily beat my previous efforts (TbMap, doi:10.1186/1471-2105-8-158), especially as errors will be easy to fix.

So, food for thought. Now, I just need to focus a little and get down to actually doing the work.

Wednesday, April 08, 2009

e-Biosphere Challenge


The e-Biosphere meeting in London June 1-3 has announced a The e-Biosphere 09 Informatics Challenge:

Prepare and present a real-time demonstration during the days of the Conference of the capabilities in your community of practice to discover, disseminate, integrate, and explore new biodiversity-related data by:
  • Capturing data in private and public databases
  • Conducting quality assurance on the data by automated validation and/or peer review
  • Indexing, linking and/or automatically submitting the new data records to other relevant databases
  • Integrating the data with other databases and data streams
  • Making these data available to relevant audiences
  • Make the data and links to the data widely accessible and
  • Offering interfaces for users to query or explore the data.

The "real time" aspect of the challenge seems a bit forced. I think they originally wanted a "live demo", but now they seem to be happy with a demo that unfolds over the three day meeting, without necessarily literally taking three days (what the organisers term "cooking shows"). I also think cash prizes would have been a good idea (the web site simply says "there will be prizes"). It's not the cash itself that matters, it's the fact that it indicates that the organisers are serious about wanting to attract entries. Entrants are likely to invest more time than they'd recoup in cash.

In any event, given that challenges are a great way to focus the mind on a deadline, I'll be entering the wiki of taxonomic names that I've been working on.

Friday, March 06, 2009

Phylogenies in a wiki

I'm slowing trying to get phylogenies into the wiki that I'm playing with. Here's an early example, the TreeBASE tree T6002, from the study A Phylogenomic Study of Birds Reveals Their Evolutionary History. The tree is displayed using my tvwidget. Below are listed the OTUs in the tree in a crude table. The idea is that this table will contain a mapping between OTU labels and taxa. For example, one OTU is labelled "Diomedea nigripes". This links to the page for Diomedea nigripes, which provides some basic information on this name, including the statement that ITIS regards the correct name for this bird to be Phoebastria nigripes (Audubon, 1839). The table on the page showing the tree displays this information as well.


This is all terribly incomplete and crude, but it gives a sense of where this is going. The plan is to import in bulk the trees and the mappings (from, say, TBMap), as well as the names themselves, and associated literature (including the TreeBASE studies) and then the trees will be embedded in richer data about the taxa.

Friday, February 27, 2009

Something's missing from taxonomic name vocabularies

In the wiki examples I've been developing I've been trying to model names using the TDWG LSID vocabularies, particularly TaxonName. Roger Hyam has obviously put a huge amount of work into developing these, and they handle just about everything I need. However, I think that there's one thing missing, namely a way to express the logical relationship between the parts of a multinomial taxonomic name.

For example, consider the fish Chromis circumaurea Pyle, Earle, and Greene, 2008, described by Rich Pyle and colleages (TED have recently posted a great video of Rich talking about discovering new species of fish). Chromis circumaurea is a species in the genus Chromis, and in the TaxonName vocabulary I can represent this relationship using the term "genusPart", which specifies the name of the genus. In a wiki page this could be a link to a page called "Chromis".

But, which "Chromis"? There are at least three:
  • Chromis Hübner 1819
  • Chromis Lacepède 1802
  • Chromis Cuvier, 1814
Only one of these is the fish (Chromis Cuvier, 1814). Cases of the same name being used for different organisms (homonymy) is not uncommon, so linking to strings isn't adequate to express the relationship between the two parts of the name Chromis circumaurea.

I'd alluded to this issue in my first major foray into RDF and taxonomic names (Taxonomic names, metadata, and the Semantic Web), where I proposed using the Dublin Core term "isPartOf" to link the specific epithet to the genus part. In this case, the link would be between URIs for the names Chromis circumaurea Pyle, Earle, and Greene, 2008 and Chromis Cuvier, 1814.

It's a small point, but without some means to link components of a name we're going to struggle to sensibly answer questions such as listing all the species in a given genus (or, perhaps more correctly, all the species names that have been published in a given genus).

Wednesday, February 04, 2009

Wiki demo


Reading a recent TAXACOM thread (Species Pages - purpose) my sense is that some people are arguing that "species pages" would be time consuming to create, aren't much good for taxonomists (to quote Mike Dallwitz "In brief, to make simplified and attractive information about taxa easily available to casual users?"), and nobody gets credit for making them. In short, "they're not for me, I don't get credit for making them, so why bother?"

Others (e.g., Doug Yanega) see species pages -- properly constructed -- to be a research tool. If we extend this to its logical conclusion, we could envisage these pages being the primary source of information on taxa. Indeed, new taxa could be described in this way. In short, "this is the future of taxonomic publication".

One obvious way to realise species pages sensu Doug Yanega is using a wiki, but then there are those that horrified by the prospect of just "anyone" being able to edit that content. In short, "wikis are not for serious people, the ignorant might mess up my stuff". Others have had a more positive experience.

I realise this doesn't do justice to these positions, but this make things a little concrete, I've put together a demo based on a wiki I'm constructing. The aim of this wiki is to link together taxonomic names, specimens, images, classifications, publications, phylogeny, people in one place. It's a bit like a wiki version of my Elsevier Challenge entry.

This is some way off being ready for prime time, but I thought it might be useful to show the sort of thing that can be done.

As a starting point, http://itaxon.org/wikidev/Chromis_circumaurea is a page about Chromis circumaurea, one of the fish Rich Pyle et al recently described in Zootaxa. This page contains a map and some specimen images, and an abbreviated description copied from the Zootaxa article. The images and the map are generated automaticaly by the wiki, based on the links it has to the specimens, e.g.:

http://itaxon.org/wikidev/BMNH_2007.10.31.3
http://itaxon.org/wikidev/USNM_391138_%28Fishes%29

The USNM specimen is linked to a GenBank sequence http://itaxon.org/wikidev/EU358583 . Specimens themselves are linked to Museum collections (using data from Biodiversity Collections Index ).

The name itself is linked to a publication:

http://itaxon.org/wikidev/Jacc:1175-5326:1671%403

which is also linked to the authors. The wiki supports GUIDs, so that you can link to the page about Chromis circumaurea using it's ZooBank LSID, for example: http://itaxon.org/wikidev/Urn:lsid:zoobank.org:act:8ADC4817-8F1C-4C88-8B8A-5372A84CAEC9

What I hope this crude example demonstrates is a framework where we can support all the kinds of objects we care about, and easily create links between them that can generate useful information. For example, the page for Chromis circumaurea doesn't explicitly list the images shown, they are there because of the links between Chromis circumaurea, the specimens, and the images of those specimens. The same applies to the map. What this means is that very little information needs be entered, it's mostly a matter of joining the dots.

Note that these wiki pages already have more information than either iSpecies or EOL.

This example has been assembled by hand, but much of the data required can be entered automatically (e.g., for sequences, specimens, publications, etc.), and tools such as text mining or XML markup (e.g., TaxonX) could be easily exploited. I also realise that as it stands the demo has very limited information about the organism itself, but I don't this this as intractable.

If we could build things like this (and I believe we can, with a lot less effort than might be thought), the question becomes this the kind of "species page" that would be useful?

Monday, February 02, 2009

Wiki modelling - Part 4

Another issue I'm trying to get my head around is how to deal with labels in phylogenies. These can be any number of things, such as GenBank sequences, specimen codes, taxon names, abbreviations of taxon names, laboratory codes, etc. Here's my quick attempt to model these:

This sketches various levels of indirection to go from a label in a tree to a taxon name. The may be short form of a taxon name (one redirect to name), it may contain a specimen code (redirect to specimen code, then link to name), or it may be GenBank sequence (redirect to accession number, then via source to taxon name with corresponding NCBI taxon id). There are other cases to consider, such as synonyms, but I'll try to deal with these later. At this stage I'm looking at how to make it simple to query for all phylogenies that contain a given taxon.

Wiki modelling - Part 3

I rather skirted around the notion of "taxonomic concepts" in the previous post, partly because it's easy to end up with trying to have a concept for each utterance every made by a taxonomist, and that doesn't seem, er, scalable. So, I have a more limited view of a taxonomic concept, namely a name attached to some data. For example, I think the NCBI Taxonomy provides useful taxonomic concepts, in that names are explicitly linked to data, such as sequences:

Having data means we can make inferences that have some basis, other than trying to figure out what a taxonomist "meant".

However, things start to get a little messy once I try and extract more information out of NCBI GenBank. Some time ago I pointed out the potential utility of host association records in GenBank. In some (many?) cases the host taxa won't be in GenBank, so the link will be between DNA sequence and taxon name. This is, of course, a simplification. It would be nice to model things more accurately. For example, a parasite will typically be obtained from a host organism, so it might be nice if, say, we had voucher specimen codes for both parasite and host, and could model the link as one between organisms (or samples of/from organisms). However, this is unlikely to be feasible in most cases, hence we have sequences linked to names: