Showing posts with label duplicates. Show all posts

Tuesday, February 08, 2022

Duplicate DOIs (again)

This blog post provides some background to a recent tweet where I expressed my frustration about the duplication of DOIs for the same article. I'm going to document the details here.

The DOI that alerted me to this problem is https://doi.org/10.2307/2436688 which is for the article

Snyder, W. C., & Hansen, H. N. (1940). THE SPECIES CONCEPT IN FUSARIUM. American Journal of Botany, 27(2), 64–67.

This article is hosted by JSTOR at https://www.jstor.org/stable/2436688 which displays the DOI https://doi.org/10.2307/2436688 .

This same article is also hosted by Wiley at https://bsapubs.onlinelibrary.wiley.com/doi/abs/10.1002/j.1537-2197.1940.tb14217.x with the DOI https://doi.org/10.1002/j.1537-2197.1940.tb14217.x.

Expected behaviour

What should happen is if Wiley is going to be the publisher of this content (taking over from JSTOR), the DOI 10.2307/2436688 should be redirected to the Wiley page, and the Wiley page displays this DOI (i.e., 10.2307/2436688). If I want to get metadata for this DOI, I should be able to use CrossRef's API to retrieve that metadata, e.g. https://api.crossref.org/v1/works/10.2307/2436688 should return metadata for the article.

What actually happens

Wiley display the same article on their web site with the DOI 10.1002/j.1537-2197.1940.tb14217.x. They have minted a new DOI for the same article! The original JSTOR DOI now resolves to the Wiley page (you can see this using the Handle Resolver), which is what is supposed to happen. However, Wiley should have reused the original DOI rather than mint their own.

Furthermore, while the original DOI still resolves in a web browser, I can't retrieve metadata about that DOI from CrossRef, so any attempt to build upon that DOI fails. However, I can retrieve metadata for the Wiley DOI, i.e. https://api.crossref.org/v1/works/10.1002/j.1537-2197.1940.tb14217.x works, but https://api.crossref.org/v1/works/10.2307/2436688 doesn't.

Why does this matter?

For anyone using DOIs as stable links to the literature the persistence of DOIs is something you should be able to rely upon, both for people clicking on links in web browsers and developers getting metadata from those DOIs. The whole rationale of the DOI system is a single, globally unique identifier for each article, and that these DOIs persist even when the publisher of the content changes. If this property doesn't hold, then why would a developer such as myself invest effort in linking using DOIs?

Just for the record, I think CrossRef is great and is a hugely important part of the scholarly landscape. There are lots of things that I do that would be nearly impossible without CrossRef and its tools. But cases like this where we get massive duplication of DOIs when a publishers takes over an existing journal fundamentally breaks the underlying model of stable, persistent identifiers.

Monday, May 27, 2013

Multiple DOIs for the same article issued by different publishers

DoiI've stumbled on a case where two different publishers have issued different DOIs for the same articles. In this case, Springer and J-State both publish the Japanese Journal of Ichthyology (ISSN 0021-5090). The following article:
Randall, J. E., & McCarthy, L. J. (1989). Solea stanalandi, a new sole from the Persian Gulf. Japanese Journal of Ichthyology, 36(2), 196–199. doi:10.1007/BF02914322

is published by Springer with the DOI http://dx.doi.org/10.1007/BF02914322, and this DOI is registered with CrossRef. J-Stage publish the same article, with the DOI (http://dx.doi.org/10.11369/jji1950.36.196). This DOI is not registered with CrossRef. I haven't been able to find an easy way to discover the DOI registration agency for a DOI (surely there should be a simple service that tells me this?).

This illustrates a problem with the success of DOIs and the existence of multiple registration agencies. When there was essentially a single agency for publications (CrossRef) it was relatively easy to ensure that DOIs for publications were unique. Now that there are multiple DOI registration agencies it is possible for conflicts to arise. We might expect this to be rare, after all, surely there's only one publisher for an article? However, the publishing landscape is more complicated that that, with articles being served by multiple publishers, and archiving projects like JSTOR and BHL having content that overlaps with that of existing publishers. Messy (sigh).

Wednesday, September 05, 2012

BHL is duplicating DOIs because it doesn't know about articles

Quick note that as much as I like that the Biodiversity Heritage Library is using DOIs, they are generating them for publications that already have them (or are acquiring them from other sources). For example, here are the two DOIs for the same article (formatted using the DOI Citation Formatter), one from BHL and one from the Smithsonian:

Springer, V. G. (1982). Pacific Plate biogeography, with special reference to shorefishes / Victor G. Springer. Smithsonian Institution. doi:10.5962/bhl.title.37141
Springer, V. G. (1982). Pacific Plate biogeography, with special reference to shorefishes. Smithsonian Contributions to Zoology, (367), 1–182. doi:10.5479/si.00810282.367


The BHL DOI resolves to a page in BHL, the other DOI resolves to the a page in the Smithsonian Digital Repository (this article also has the handle hdl:10088/5222).

Now this is a problem, because DOIs are meant to be unique: one article, one DOI. I've encountered duplicates elsewhere, but in these cases one should be an alias of the other. In the example above, the DOIs resolve to different locations. If you are just after the content this isn't a huge problem, but if, say, you were using the DOI to uniquely identify the publication (say, in a database) you have a problem: which DOI to choose? If you and I choose differently then we will make statements about the same article but be unaware of that sameness.

Much of this problem arises because BHL has no concept of articles. Most articles are likely to reside within scanned volumes of a journal, but some articles (e.g., monographs) may be treated a single title by BHL, and each BHL title now gets a DOI.

I know that handling articles is on BHL's radar, but it because it hasn't tackled it yet we are going to have cases where BHL DOIs duplicate existing DOIs. In these cases, BHL may have to make their DOI an alias of the other DOI.

Thursday, February 23, 2012

How many specimens does GBIF really have?

GbifDuplicate records are the bane of any project that aggregates data from multiple sources. Mendeley, for example, has numerous copies of the same article, as documented by Duncan Hull (How many unique papers are there in Mendeley?). In their defence, Mendeley is aggregating data from lots of personal reference libraries and hence they will often encounter the same article with slightly differing metadata (we all have our own quirks when we store bibliographic details of papers). It's a challenging problem to identify and merge records which are not identical, but which are clearly the same thing.

What I'm finding rather more alarming is that GBIF has duplicate records for the same specimen from the same data provider. For example, the specimen USNM 547844 is present twice:

As far as I can tell this is the same specimen, but the catalogue numbers differ (547844 versus 547844.6544573). Apart from this the only difference is when the two records were indexed. The source for 547844 was last indexed August 9, 2009, the source for 547844.6544573 was first indexed August 22, 2010. So it would appear that some time between these two dates the US National Museum of Natural History (NMNH) changed the catalogue codes (by appending another number), so GBIF has treated them as two distinct specimens. Browsing other GBIF records from the NMNH shows the same pattern. I've not quantified the extent of this problem, but it's probably a safe bet that every NMNH herp specimen occurs twice in GBIF.

Then there are the records from Harvard's Museum of Comparative Zoology that are duplicates, such as http://data.gbif.org/occurrences/33400333/ and http://data.gbif.org/occurrences/328478233/ (both for specimen MCZ A-4092, in this case the collectionCode is either "Herp" or "HERPAMPH"). These are records that have been loaded at different times, and because the metadata has changed GBIF hasn't recognised that these are the same thing.

At the root of this problem is the lack of globally unique identifiers for specimens, or even identifiers that are unique and stable within a dataset. The Darwin Core wiki lists a field for occurrenceID for which it states:

The occurrenceID is supposed to (globally) uniquely identify an occurrence record, whether it is a specimen-based occurrence, a one-time observation of a species at a location, or one of many occurrences of an individual who is being tracked, monitored, or recaptured. Making it globally unique is quite a trick, one for which we don't really have good solutions in place yet, but one which ontologists insist is essential.

Well, now we see the side effect of not tackling this problem - our flagship aggregator of biodiversity data has duplicate records. Note that this has nothing to do with "ontologists" (whatever they are), it's simple data management. Assign a unique id (a primary key in a database will do fine) that can be used to track the identity of an object even as its metadata changes. Otherwise you are reduced to matching based on metadata, and if that is changeable then you have a problem.

Now, just imagine the potential chaos if we start changing institution and collection codes to conform to the Darwin Core triplet. In the absence of unique identifiers (again, these can be local to the data set) GBIF is going to be faced with a massive data reconciliation task to try and match old and new specimen records.

The other problem, of course, is that my plan to use GBIF occurrence URLs as globally unique identifiers for specimens is looking pretty shaky because they are unique (the same specimen can have more than one) and if GBIF cleans up the duplicates a number of these URLs will disappear. Bugger.


Monday, September 12, 2011

Duplicate DOIs for the same article: alias DOIs, who knew?

As part of a project to map taxonomic citations to bibliographic identifiers I'm tackling strings like this (from the ION record urn:lsid:organismnames.com:name:1405511 for Pseudomyrmex crudelis):

<tdwg_co:PublishedIn>
Systematics, biogeography and host plant associations of the Pseudomyrmex viduus group (Hymenoptera: Formicidae), Triplaris- and Tachigali-inhabiting ants. Zoological Journal of the Linnean Society, 126(4), August 1999: 451-540. 516 [Zoological Record Volume 136]
</tdwg_co:PublishedIn>

I parse the string into its components (e.g., journal, volume, issue, pagination) and use scripts to locate identifiers such as DOIs. I regard DOIs as the gold standard for bibliographic identifiers. The are (usually) unique, and CrossRef provides some really useful services to support them (DOIs now also support linked data if you are in to that sort of thing). Occasionally there are problems, such as duplicate DOIs when material moves from a publisher's site to, say, JSTOR. And some publishers are really, really bad at releasing DOIs that don't resolve. For example, Taylor & Francis Online have at least 18,000 DOIs for the Annals and Magazine of Natural History that don't resolve (e.g., doi:10.1080/00222933809512318 for this paper).

Sometimes my automated scripts for finding DOIs fail and I have to resort to Googling. To my surprise, I found two versions of the paper "Systematics, biogeography and host plant associations of the Pseudomyrmex viduus group (Hymenoptera: Formicidae), Triplaris- and Tachigali-inhabiting ants", each with a different DOI:


Now, this isn't supposed to happen. Interestingly, if you resolve doi:10.1006/zjls.1998.0158, either on the web or using CrossRef's OpenURL resolver, you get the page/metadata for doi:10.1111/j.1096-3642.1999.tb00157.x.

To see what was going on I fired up my local installation of Tony Hammnd's OpenHandle tool (see http://bioguid.info/openhandle/) and entered the Elsevier DOI (10.1006/zjls.1998.0158) and got this:


{
"comment" : "OpenHandle (JSON) - see http://code.google.com/p/openhandle/" ,
"handle" : "hdl:10.1006/zjls.1998.0158" ,
"handleStatus" : {
"code" : "1" ,
"message" : "SUCCESS"
} ,
"handleValues" : [
{
"index" : "100" ,
"type" : "HS_ADMIN" ,
"data" : {
"adminRef" : "hdl:10.1006/zjls.1998.0158?index=100" ,
"adminPermission" : "111111110111"
} ,
"permission" : "1110" ,
"ttl" : "+86400" ,
"timestamp" : "Thu Apr 13 19:09:03 BST 2000" ,
"reference" : []
} ,
{
"index" : "1" ,
"type" : "URL" ,
"data" : "http://linkinghub.elsevier.com/retrieve/pii/S0024408298901583" ,
"permission" : "1110" ,
"ttl" : "+86400" ,
"timestamp" : "Tue Aug 12 16:43:12 BST 2003" ,
"reference" : []
} ,
{
"index" : "700050" ,
"type" : "700050" ,
"data" : "20030811104844000" ,
"permission" : "1110" ,
"ttl" : "+86400" ,
"timestamp" : "Tue Aug 12 16:43:16 BST 2003" ,
"reference" : []
} ,
{
"index" : "1970" ,
"type" : "HS_ALIAS" ,
"data" : "10.1111/j.1096-3642.1999.tb00157.x" ,
"permission" : "1110" ,
"ttl" : "+86400" ,
"timestamp" : "Mon Aug 25 21:06:50 BST 2008" ,
"reference" : []
}
]
}

The interesting bit is the "HS_ALIAS" at the bottom. I'd not come across this before, although it's in the spec (RFC 3651) for all to see (yeah, but who reads those?). The handle system that underlies DOIs has mechanism to support aliases, so that a DOI that originally pointed to a web page (say, for an article) can be redirected to point to another DOI. In this case, the Elsevier DOI redirects to the Wiley DOI ("10.1111/j.1096-3642.1999.tb00157.x" in the HS_ALIAS section), so the user ends up at Wiley's page for this article, not Elsevier's. This provides a way to accommodate changes in article ownership, without requiring an existing publisher to reuse the previous publisher's DOI.

In one sense this seems to defeat the point of DOIs, namely that they are effectively opaque identifiers that any publisher should be able to host. Perhaps in this case the issue is that the DOI prefix ("10.1006" and "10.1111" for Elsevier and Wiley, respectively) corresponds to a publisher, and when something goes wrong with a DOI it's easier to identify who is responsible based on this prefix, rather than the individual DOI.

In any event, next time I come across a duplicate DOI I'll need to check whether it is an alias of another DOI before launching into another rant about the (occasional) failings of DOIs.

Wednesday, November 10, 2010

Mendeley mangles my references: phantom documents and the problem of duplicate references

One issue I'm running into with Mendeley is that it can create spurious documents, mangling my references in the process. This appears to be due to some over-zealous attempts to de-duplicate documents. Duplicate documents is the number one problem faced by Mendeley, and has been discussed in some detail by Duncan Hull in his post How many unique papers are there in Mendeley?. Duncan focussed on the case where the same article may appear multiple times in Mendeley's database, which will inflate estimates of how many distinct references the database contains. It also has implications for metrics derived from the Mendeley, such as those displayed by ReaderMeter.

In this post I discuss the reverse problem, combining two or more distinct references into one. I've been uploading large collections of references based on harvesting metadata for journal articles. Although the metadata isn't perfect, it's usually pretty good, and in many cases linked to Open Access content in BioStor. References that I upload appear in public groups listed on my profile, such as the group Proceedings of the Entomological Society of Washington.

Reverse engineering Mendeley
In the absence of a good description by Mendeley of how their tools work, we have to try and figure it out ourselves. If you click on a refernece that has been recently added to Mendeley you get a URL that looks like this: http://www.mendeley.com/c/3708087012/g/584201/magalhaes-2008-a-new-species-of-kingsleya-from-the-yanomami-indians-area-in-the-upper-rio-orinoco-venezuela-crustacea-decapoda-brachyura-pseudothelphusidae/ where 584201 is the group id, 3708087012 is the "remoteId" of the document (this is what it's called in the SQLite database that underlies the desktop client), and the rest of the URL is the article title, minus stop words.

After a while (perhaps a day or so) Mendeley gets around to trying to merge the references I've added with those it already knows about, and the URLs lose the group and remoteId and look like this: http://www.mendeley.com/research/review-genus-saemundssonia-timmerman-phthiraptera-philopteridae-alcidae-aves-charadriiformes-including-new-species-new-host/ . Let's call this document the "canonical document" (this document also has a UUID, which is what the Mendeley API uses to retrieve the document). Once the document gets one of these URLs Mendeley will also display how many people are "reading" that document, and whether anyone has tagged it.

But that's not my paper!
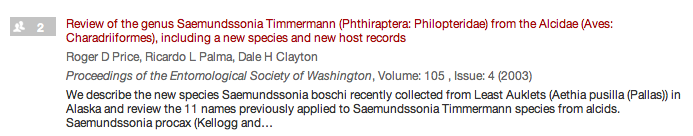
The problem is that sometimes (and more often than I'd like) the canonical document bears little relation to the document I uploaded. For example, here is a paper that I uploaded to the group Proceedings of the Entomological Society of Washington:

16212462.gifReview of the genus Saemundssonia Timmermann (Phthiraptera: Philopteridae) from the Alcidae (Aves: Charadriiformes), including a new species and new host records by Roger D Price, Ricardo L Palma, Dale H Clayton, Proceedings of the Entomological Society of Washington, 105(4):915-924 (2003).


You can see the actual paper in BioStor: http://biostor.org/reference/57185. To see the paper in the Mendeley group, browse it using the tag Phthiraptera:

group.png


Note the 2, indicating that two people (including myself) have this paper in their library. The URL for this paper is http://www.mendeley.com/research/review-genus-saemundssonia-timmerman-phthiraptera-philopteridae-alcidae-aves-charadriiformes-including-new-species-new-host/, but this is not the paper I added!.

What Mendeley displays for this URL is this:
dala.png


Not only is this not the paper I added, there is no such paper! There is a paper entitled "A new genus and a new species of Daladerini (Hemiptera: Heteroptera: Coreidae) from Madagascar", but that is by Harry Brailovsky, not Clayton and Price (you can see this paper in BioStor as http://biostor.org/reference/55669). The BioStor link for the phantom paper displayed by Mendeley, http://biostor.org/reference/55761, is for a third paper "A review of ground beetle species (Coleoptera: Carabidae) of Minnesota, United States : New records and range extensions". The table below shows the original details for the paper, the details for the "canonical paper" created by Mendeley, and the details for two papers that have some of the bibliographic details in common with this non-existent paper (highlighted in bold).

FieldOriginal paperMendeley
TitleReview of the genus Saemundssonia Timmermann (Phthiraptera: Philopteridae) from the Alcidae (Aves: Charadriiformes), including a new species and new host recordsA new genus and a new species of Daladerini (Hemiptera: Heteroptera: Coreidae) from MadagascarA new genus and a new species of Daladerini (Hemiptera: Heteroptera: Coreidae) from MadagascarA review of ground beetle species (Coleoptera: Carabidae) of Minnesota, United States : New records and range extensions
Author(s)Roger D Price, Ricardo L Palma, Dale H ClaytonDH Clayton, RD PriceHarry Brailovsky
Volume105105104107
Pages915-924915-924111-118917-940
BioStor57185557615566955761

As you can see it's a bit of a mess. Now, finding and merging duplicates is a hard problem (see doi:10.1145/1141753.1141817 for some background), but I'm struggling to see why these documents were considered to be duplicates.

What I'd like to see
I'm a big fan of Mendeley, so I'd like to see this problem fixed. What I'd really like to see is the following:
  1. Mendeley publish a description of how their de-duplication algorithms work

  2. Mendeley describe the series of steps a document goes through as they process it (if nothing else, so that users can make sense of the multiple URLs a document may get over it's lifetime in Mendeley).

  3. For each canonical reference Mendeley shows the the set of documents that have been merged to create that canonical reference, and display some measure of their confidence that the match is genuine.

  4. Mendeley enables users to provide feedback on a canonical document (e.g., a button by each document in the set that enables the user to say "yes this is a match" or "no, this isn't a match").


Perhaps what would be useful is if Mendeley (or the community) assemble a test collection of documents which contains duplicates, together with a set of the canonical documents this collection actually contains, and use this to evaluate alternative algorithms for finding duplicates. Let's make this a "challenge" with prizes! In many ways I'd be much more impressed by a duplication challenge than the DataTEL challenge, especially as it seems clear that Mendeley readership data is too sparse to generate useful recommendations (see Mendeley Data vs. Netflix Data).


Tuesday, May 08, 2007

Duplicate DOIs

I think this isn't supposed to happen, but here's a paper with two DOIs.

The first DOI is doi:10.1651/0278-0372(1997)17[253:MPAOTC]2.0.CO;2, which links to a record served by BIOONE. The second is doi:10.2307/1549275, which links to a JSTOR record (sici:0278-0372(199705)17:2<253:MPAOTC>2.0.CO;2-O).

The paper is:
Morphology-Based Phylogenetic Analysis of the Clawed Lobsters (Family Nephropidae and the New Family Chilenophoberidae)
Dale Tshudy, Loren E. Babcock
Journal of Crustacean Biology, Vol. 17, No. 2 (May, 1997), pp. 253-263


Now, the digital versions served by BIOONE and JSTOR is different, in that BIOONE serves full text HTML and a PDF, whereas JSTOR serves scanned images, but this is the same article.

As an added "feature", the BIOONE DOI doesn't work, which in my experience is often the case with BIOONE DOIs.