Showing posts sorted by relevance for query Mendeley API. Sort by date Show all posts

Monday, August 16, 2010

More on the Mendeley API

After playing with the public API for Mendeley over the weekend (see Social citations: using Mendeley API to measure citation readership) I've had a quick play with the user specific part of the API. This API enables apps to connect with a user's account, so you could imagine using it to personalise citations lists (as I mentioned in the previous post), or building apps to handle a user's reading list (to complement Mendeley's existing desktop and iPhone clients).

Once again, it's frustrating just how rough the API is. The documentation is incomplete and contains errors, and some of the API calls simply don't work (see this post). I know I'm sounding like a broken record, but this API really needs a test suite. The quickest way to annoy potential users of the API is to get them to find really obvious bugs for you.

With a test suite in mind, I've created a simple app that enables you to connect to your Mendeley account and perform a bunch of simple tasks. The hardest part of getting this working was getting my head around OAuth. Luckily, @abraham has written a PHP library to support OAuth access to Twitter's API, so I grabbed that and replaced Twitter-specific code with the equivalent code for Mendeley.

Demo
You can try the app here: http://iphylo.org/~rpage/mendeley/moauth/.

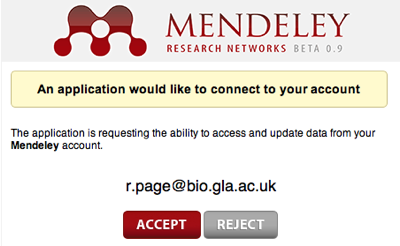
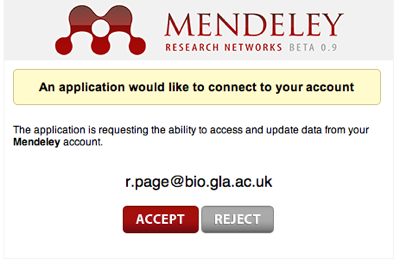
The first time you go to the app is shows a button to connect to Mendeley. If you click on it you'll see something like this:
connect.png
(if you're not already logged in to Mendeley it may ask you to log in — note that all of this happens on Mendeley's site, my app never knows your username or password details). If you're willing to try the app, allow it to connect to your account. You'll then see a bunch of API requests and results. All but one of the requests is simply displaying information. One request does try to add a test document (the one listed on the Mendeley developer's site), but at the moment this part of the API doesn't seem to work (nor does the call to get the list of papers that you've authored).

If and when Mendeley get the API working fully (and documented) there's a lot of scope here. But what I'd really like to see is Mendeley develop a test suite that runs through every API call and checks that the methods work as advertised.

Wednesday, June 08, 2011

I wrote that: asserting authorship using the Mendeley API

Inspired by the forthcoming Hack4Knowledge I've put together a service that enables you to assert that you are the author of a paper using the Mendeley API.

If you are impatient, give it a try at:

http://iphylo.org/~rpage/hack4knowledge/iwrotethat/

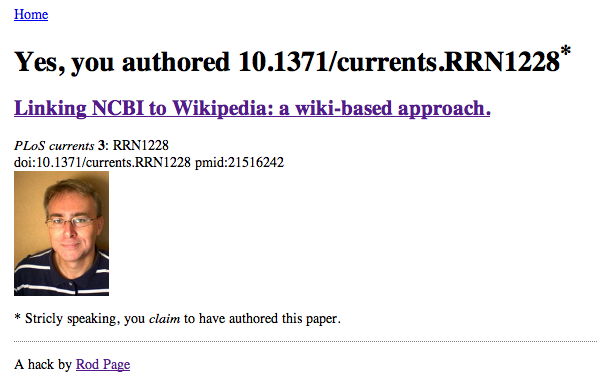
To use it you need a Mendeley account. When you go to I wrote that you will be asked to connect to your Mendeley account. Once you've done that, enter the DOI or PubMed ID of a paper and, if the paper is in your Mendeley library and flagged as a paper you've authored, you should see something like this:

Wrote

The site can be a little sluggish as it needs to go through all of your publications one by one until it finds a match.

Why?
Imagine you have a web database that includes publications, and you want people to join your site as users. If they have publications in your database, you'd like your users to be able to say "I'm the author of those papers" or, more generally, the author you have as "Roderic D. M. Page" is me.

One way to do this would be to enable the users to sign in to your site using Mendeley (see my blog post Mendeley connect). Once they've done that, the user could select a publication and say "that's mine". How do we test this assertion? Well, if the user is indeed the author it is likely that they will have added it to their "My Publications" section in their Mendeley library. So, we can use the Mendeley API to get a list of the author's publications and see whether the publication they claim is, in fact, one of theirs.

The inspiration for this came from tools like Google Analytics, where in order to add the tool to your web site you need to convince Google that you own the site. One way to do this is to add some text supplied by Google to the HTML on for site, on the assumption that only you can do this (because it's your site). In the same way, only you can add papers to your Mendeley library. Of course, I'm assuming that Mendeley users are being trustworthy when they and papers to "My Publications" (i.e., they're not claiming authorship on papers they didn't write).

How?
This hack uses Mendeley's OAuth support (the same technology used by Twitter and Facebook to connect to other sites) to enable you to connect your Mendeley account to the "I wrote that" application (note that my app never sees your account name or password). I use the Mendeley API user authored method to get a list of your publications, and user library document details to retrieve details of each publication. I then compare the DOI or PMID you supplied with each publication, until I find one that matches. If none matches, then I've no evidence you authored that paper.

Moan
No post about the Mendeley API would be complete without a moan about the state of the API. Apart from the fact that there is no function to directly find a publication in your library by DOI or PMID (hence I have to look at them all), there is virtually no support for retrieving any details about the user. For example, I wanted to brighten the web page up a little by adding a picture of the Mendeley user once they've logged in. There is no API function for this, nor a function to retrieve an identifier or URL for the user. Hence, in order to get a picture I screen scrape (yes, screen scrape) the Mendeley web page for the reference to get the URL for the linked author of the paper, then scrape the author's profile page and extract the URL for the image. This is insane. Please, please can we have a better API?

Saturday, August 14, 2010

Social citations: using Mendeley API to measure citation readership

Quick note on an app I threw together using the Mendeley API that I discussed in the previous post. This app is crude, and given that the Mendeley API is rate-limited and in flux it might not work for you.

The basic idea is to embellish make the list of literature cited in an article with information that might help a reader decide whether a given citation is worth reading. One clue might be how many people on Mendeley are reading that article. So, my app takes an article, extracts the list of cited literature, and for each article with a PubMed identifier it asks Mendeley "how many readers does this article have?" For now the app is restricted to using articles from the BiomedCentral series as these have Open Access XML with literature cited lists that contain PubMed numbers (PLoS articles, for instance, don't have these, for now I'm avoiding the overhead of finding identifiers for the articles). I'm using PubMed identifiers as the Document Details method in the Mendeley API doesn't handle DOIs at present.

The app is at http://iphylo.org/~rpage/mendeley/, and the default article I've chosen to demonstrate the app is Robust physical methods that enrich genomic regions identical by descent for linkage studies: confirmation of a locus for osteogenesis imperfecta doi:10.1186/1471-2156-10-16, but you can enter the DOI of any BMC article to give it a try. Below is a screenshot of part of the list of literature cited by this paper, together with readership numbers:

readership.png

The default article has 4 readers in Mendeley. The readership of the articles it cites varies, but one article stands out with 208 readers.

There are huge limitations with this app (it doesn't cache the Mendeley results, so repeated use will exceed the rate limits), it is limited to citations in PubMed (could add support for DOIs and title searches), and only BMC articles can be processed.

What would be interesting is to extend this in other directions. For example, if the user had a Mendeley account, it would be nice to flag which articles the reader already had in their library (and perhaps have the ability to add those that weren't to the library). To personalise the citation readership display I'd need to add support for OAuth, which Mendeley uses to authorise access to user accounts.

If Mendeley were to provide more social features in their API then we could add flags indicating whether any of user's contacts have any of these articles in their libraries (your decision to read a paper might be influenced by whether a contact of yours has read it -- think of it as a resembling the Facebook "Like" button). Or we could display the readers themselves, so you could discover people with potentially similar interests to your own.

My twitter stream has been full of complaints about the Mendeley API — life on the bleeding edge is not always fun. But the API does have the potential to support some cool applications, once it gets the kinks ironed out.

Thursday, August 12, 2010

Mendeley API: we'll bring the awesome if you bring the documentation

mendeley.pngMenedeley's API has been publicly launched at http://dev.mendeley.com/, accompanied by various announcements such as:
Mendeley's Research API is now open to the public. Developers, go forth and bring the awesome :) http://dev.mendeley.com/ (@subcide)

Finally saw the awesome Easter Egg that @subcide hid on the new dev.mendeley.com Developer Portal! Whoaaa! (@mendeley_com)

All good fun to be sure, but it's a pity more effort has been spent on Easter eggs than on documenting and testing the API. If you visit the API development site there's precious little in the way of documentation, and few examples. As well as making a developer's life harder, adding examples would have helped catch some bugs, such as the failure of the API calls to return details such as volume, issue, and page numbers for articles, and the inability to retrieve a document using a DOI (the '/' that a DOI contains breaks the API). These are fairly obvious things. If resources are limiting, perhaps the Mendeley API team should open up the development web site to others to help create documentation and examples. A wiki would be one way to do this.

Menedeley is a great idea, but on occasion the hype gets ahead of reality. The product has a lot of potential, but also has some significant problems. Using the search API you pretty quickly encounter its number one problem: duplicates. I get the sense that Mendeley is about three things:

  1. Managing personal bibliographies and generating citations (desktop client)

  2. Networking ("the Last.fm of research") (web site)

  3. Bibliographic data

Number 3 is, I suspect, the hardest problem to tackle, and it is where the ultimate value lies (think citation networks, audience data, iTunes-like business model for selling articles, etc.). I'd like Mendeley a lot more if I was confident that they had a good handle on the complexities of bibliographic data (and didn't drop pagination from API calls). Good places to start are "Are your citations clean?" (doi:10.1145/1323688.1323690) and "Learning metadata from the evidence in an on-line citation matching scheme" (doi:10.1145/1141753.1141817), both currently duplicated in Mendeley (try searching for Are your citations clean and Learning metadata from the evidence in an on-line citation matching scheme).

Thursday, August 26, 2010

Mendeley API PHP client

mendeley.pngFollowing on from my earlier post about the Mendeley API, I've bundled up my code for OAuth access to the Mendeley API for anyone who's interested in playing with the API using PHP. You can browse the code on Google Code, or grab a tarball here. You'll need a consumer key and a consumer secret from Mendeley for the demos to work, and if you're behind a HTTP proxy you'll have to tweak the code (this is explained in the ReadMe.txt file that comes with the code).

The code is pretty rough, and doesn't use all the Mendeley API calls, but I've other things to do, and it felt like a case of either bundle this up now, or it will get lost among a host of other projects. The Mendeley API still feels woefully under-developed. I'd be more interested in developing this client further if the API was powerful enough to do the kinds of things I'd like to do.

Tuesday, August 31, 2010

ReaderMeter: what's in a name?

Screen_shot_2010-08-30_at_22.37.31.pngDario Taraborelli has released ReaderMeter, an elegant app built on top of the Mendeley API. You enter an author's name and it summarises that authorship's readership in Mendeley. The app provides some summary statistics (mine are shown below), and if you click on the horizontal bar corresponding to a paper, you can see a visualisation of who is reading your paper, including a nice map.

meter.png

As ever with author names, there are issues of people's name having more than one spelling. In Mendeley I'm known as Roderic D. M. Page, R. D. M. Page, Rod Page, Roderic Page, Roderic D. M. Page, and doubtless some others. Searching ReaderMeter using different spellings of my name gives different results. There are various approaches to tackling this problem, I've touched on one approach earlier.

However, there's a different way to tackle this problem in the context of apps like ReaderMeter, because if you're a Mendeley user you can assert that you are the author of a paper (these papers live in your "My Publications" collection). Using Mendeley's API, an app could retrieve this list of publications (providing the user gave it access), and we could compute readership statistics from the set of articles "known" to be authored (leaving aside the issue of people gaming the system by spuriously claiming authorship). In this way the app relies on the default behaviour of Mendeley users - uploading and self-identifying the articles they've written.

Implementing a feature like this posses two problems. The first is access to a user's data. Mendeley's API supports OAuth, so it could be done in such a way that only the account's user could authorise the app to access this list. The app could store the fact that the user has verified that the list of publications. Think of it as a bit like Amazon's Real Name™ feature.

The other obstacle is Mendeley's API, which returns readership statistics for public documents (i.e., those in the central aggregation). At present, using the API there is no way to link the global id for a Mendeley reference (e.g., ae7dd6a0-6d09-11df-936c-0026b95e484c) with the local id (e.g., 3582682802) that reference has in a user's collection, unless we resort to trying to match articles by searching by identifiers or article titles. If the API exposed these links, apps like ReaderMeter could become even more powerful (and personalised).

Friday, April 30, 2010

Mendeley Open API and the Biodiversity Heritage Library

Mendeley have called for proposals to use their forthcoming API. The API will publicly available soon, but in a clever move Mendeley will provide early access to developers with cool ideas.
Given that the major limitation of the Biodiversity Heritage Library (from my perspective) is the lack of article-level metadata, and Mendeley has potentially lots of such data, I wonder whether this is something that could be explored. My BioStor project takes article metadata and finds articles in BHL, so an attractive work flow would be:
  1. People upload bibliographies to Mendeley (e.g., bibliographies for particular taxa, journals, etc.)

  2. BioStor uses Mendeley's API to find articles liklely to be in BHL, then locates the actual article in Mendeley.

  3. The user could then grab a PDF of the article from BioStor that contains XMP metadata (which Mendeley, and other tools, can read)

Users would gain a tool to manage their bibliographies (assuming that they prefer Mendeley to other tools, or are happy to sync with Mendeley), they would be contributing to a database of taxonomic (and biological literature in general, BHL's content is pretty diverse), and also gain easy access to PDFs for BHL content (this last feature depends on whether Mendeley can associate a PDF with an existing bibliographic record automatically). In the same way, a tool such as BioStor (and, by implication, BHL) could gain usage statistics (i.e., who is reading these articles?).

Our communities efforts at assembling bibliographies haven't amounted to much yet. The tools we use tend to be poor. I find CiteBank to be underwhelming, and Drupal's bibliographic modules (used by CiteBank and ScratchPads) lack key features. We also seem reluctant to contribute to aggregated bibliographies. Perhaps encouraging people to use a nicer tool, and at the same time providing additional benefits (e.g., XMP PDFs) might help move things forward.

Anyway, food for thought. Perhaps other tools might make more sense, such as using the API to upload metadata and PDFs direct from BioStor to Mendeley, and making the collection public. But, if I were Mendeley, what I'd be looking for are tools that enhance the Mendeley experience. There's some obvious scope for visualising the output and social networks of authors, such as the sparklines and coauthor graphs I've been playing with in BioStor (for example, for W E Duellman):

FB144353-8061-456E-A502-9D9F01F56123.jpg

D6EB9A37-0440-479F-B937-4489359C1E33.jpg

Before this blog post starts to veer irretrievably off course, I'd be interested in thoughts of anyone interested in matters BHL. There's nothing like a deadline (Friday, May 14th) to concentrate the mind...

Friday, January 18, 2013

Thoughts on Mendeley and Elsevier


The rumour that Elsevier is buying Mendeley has been greeted with a mixture of horror, anger, peppered with a few congratulations, I told you so's, and touting for new customers:


Here's some probably worthless speculation to add to the mix. Disclosure: I use Mendeley to manage 100,000's of references, and use the API for various projects. I'm not paying customer (but I do pay for some Internet services such as DropBox, BackBlaze, and Spotify, so it's not that I won't pay, it's just that the service Mendeley charge for doesn't interest me). I've published in Elsevier journals (most recently a couple of papers that, thanks to the efforts of Paul Craze, editor of TREE, are "free" in the sense you can download the PDF for free), and I took part in the Elsevier Grand Challenge.

So, given that I'm suitably compromised, here are some thoughts.

Elsevier suck


Elsevier are big, ugly, and at the corporate level are doing things that actively make researchers angry (see The Cost of Knowledge).

Elsevier rocks


Elsevier are one of the most innovative science publishers around. They fund challenges, are investing heavily in interactive and semantic markup of papers (for example, interactive phylogenies), and have built an app ecosystem on their publishing platform.

Mendeley sucks


Mendeley is suffering some from serious failings, most of which could be addressed with sufficient resources. The API sucks, mostly because Mendeley themselves don't actually use it. The Desktop client communicates with Mendeley's database using a different protocol, hence the API lacks the functionality needed to make truly great apps on the platform. The algorithms Mendeley use to de-duplicate their catalogue are flawed, occasionally creating entirely fictional entries.

Mendeley rocks


The way Mendeley engineered the creation of a bibliographic database in the cloud is genius, as is their recognition that the object around which scientists will cluster is the article, not the author. They helped foster the altmetrics movement, and have a great presence on Twitter and at conferences (i.e., you can talk to actual people who write code).

What happens next?


Let's assume that Elsevier does, indeed, buy Mendeley, and wants to do interesting things with Mendeley, and that Mendeley doesn't become one of the many startups that have a successful "exit" for the founders but ends up dying in the bosom of a larger company. Here are some possibilities.

Mendeley becomes iTunes for papers


Forget the "Last.fm" of papers, what about the "iTunes of papers"?. Big publishers are facing a revolt over the cost of institutional subscriptions, and journals are increasingly irrelevant as aggregations. The literature that people read is widely scattered across different outlets. Journals are archaic in the same way that music albums are mostly a thing of the past, people mix and match singles.

In the recent fight between UC Davis and Nature, Nature estimated that "CDL will be paying roughly $0.56 per download". So, why not charge a buck a paper? Mendeley's web interface is practically crying out for a "BUY THIS PAPER" button. Under this model, Elsevier has an outlet for its content that doesn't force people to subscribe to large amounts of stuff they don't want. Mendeley could be used to establish a relationship directly with paying customers, rather than institutions.

Mendeley becomes the de facto measure of research impact


But combining Mendeley's readership data with citations, Elsevier could construct powerful measures of research impact, bringing altmetrics into the mainstream. Couple this with links to institutions, and Elsevier could provide universities with all the data they need to evaluate academic performance (gulp).

Mendeley becomes an authoring tool


Managing references and inserting citations into manuscripts is one of the basic tasks facing an academic author. Authoring tools are evolving in the direction of being online, and embedding more semantic markup (e.g., these are taxon names, this is a chemical compound, this is a statement of causality). In a sense reference lists are the one form of structured markup we are already familiar with. Why not build on that and create an authoring platform?

Mendeley becomes the focus of post-publication review


Publishers have failed to crack the problem of post-publication review. Several provide the ability for readers to comment on an article online, but this has failed to take off. I think this is because the sociology is wrong, if you want a conversation you need to go where the people are, not expect them to come to you. Given that people are bookmaking papers in Mendeley, the next step is to get them to comment, or aggregate their annotations (in the same way that Amazon's Kindle can show you passages that others have highlighted).

Interesting times...

Saturday, August 28, 2010

On being open: Mendeley and open data versus open source

Paulo Nuin, not the biggest fan of Mendeley wrote a blog post entitled Mendeley is going to be open source, in which he wrote:

After extensively researching some material online, analysing many blog posts and statements made by people linked to Mendeley, checking my sources, I reached the conclusion that soon Mendeley is going to be open source.

Among the essays Paulo read is Jason Hoyt's post on the Mendeley blog: Dear researcher, which side of history will you be on?. In response to a question about open sourcing the Mendeley client, Jason replied:
I get asked a lot about open sourcing Mendeley when I go to speaking events. I always state that we are open to the possibility, but then ask how many people know how to type a URL verus how many know how to program in C++? That’s why we went with the Open API first instead of open sourcing the desktop software. If you can type a URL, which is what the API is based upon, then you can build on top of Mendeley. You don’t need to know how to program.

Despite the fact that open sourcing the desktop client is the second most requested feature for Mendeley, I think Jason is right. I also think Paulo's campaign to make Mendeley open source is misguided. The client doesn't matter. OK, yes, it's probably the reason most people use Mendeley, but there are lots of competing clients (EndNote, Zotero, Papers, etc.), and there are several bibliographic data formats (RIS, EndNote XML, BibTeX) and essentially one document format (PDF) that they support, so individual users don't have to worry about locking their individual bibliographies into a proprietary format. Couple this with the existence of an API (albeit a pretty crap one), and whether an individual software client is closed or open source doesn't matter much.

Will the data be open?

However, what makes Mendeley different is the aggregation of bibliographic data (35 million references and counting).

privacy_1264073462.jpg


I'd argue it's the fate of this aggregation that matters. In a comment on the Guardian's piece Mendeley 'most likely to change the world for the better', Jane Good wrote:
"World-changing potential"? This utopian fantasy stuff is a little much, no? After all, we're talking about a for-profit corporation using closed-source software to monitor private usage habits for monetary gain. And how exactly is this company meant to sustain its millions of dollars of annual burn on a few measly storage subscriptions? At some point the data will have to go up for sale to the highest bidder, plain and simple. The API, as it exists now, does not provide access to that data, and it probably never will, right, DrGinn[sic]?

Toning down the rhetoric, the question is Mendeley, Scopus, Talis – will you be making your data Open?:

But how can a company create an income stream from Open Scientific content? That’s the a question for me for this decade. If we can solve it we can transform the world. If however the linked Open data are all going to be through paywalls, portals, query engines then we regress into the feudal information possession of the past. I hope the companies present in this session can help solve this. It won’t be easy but it has to be done. So I now ask Mendeley, Elsevier/Scopus, Talis: Are your data Openly available for re-use?

For me the question of whether the source code for the Mendeley desktop will be made open source is a red herring, and ultimately a distraction from the real question — will the data be open?

Friday, September 24, 2010

Mendeley Connect

When I first launched BioStor (an article finding tool built on the top of the (Biodiversity heritage Library) I wanted people to be able to edit metadata and add references, but also minimise the chances that junk would get added. As a quick and dirty deterrent I used reCAPTCHA, so anybody adding a reference or editing the metadata had to pass a CAPTHCA before their edits were accepted.

While reCAPTCHA does the trick, it can be tedious for somebody editing a lot of articles to have to pass a CAPTHCA every time they edit an article. Ed Baker of the International Commission on Zoological Nomenclature (ICZN) has a project to identify all the articles in the Bulletin of Zoological Nomenclature, and has been gently bugging me to add a login feature to BioStor. I played for a while with OpenID, but it occurred to me that Mendeley might be a more sensible strategy. Mendeley's API supports OAuth, a protocol where you can grant an application access to another application, but without giving away any passwords. It's used by Twitter and Facebook, among others. Indeed, a growing number of sites on the web are using Twitter and/or Facebook services to enable users to log in, rather than write their own code to support login, usernames, passwords, etc.

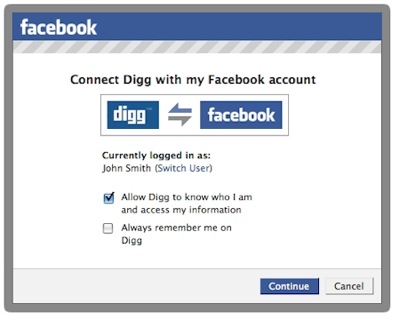
In the case of BioStor, I've added a link to sign in via Mendeley. if you click on it you get taken to a page like this:

connect.png
If you're happy for BioStor to connect to Mendeley, you click on Accept and BioStor won't bug you to fill in a CAPTCHA. Once Mendeley's API matures it would be nice to add features such as the ability to add a reference in BioStor straight to your Mendeley library (this is doable now, but the Mendeley API looses some key metadata such as page numbers).

facebook-connect.jpg
But, thinking more broadly, Mendeley has an opportunity here to provide services similar to Facebook Connect. For example, instead of simply having buttons on web pages to bookmark papers, we could have buttons indicating how many people had added a paper to their library, and whether any of those people were in your contacts. We could extend this further an create something like Facebook's Open Graph Protocol, which supports the "Like" button. Or perhaps, we could have an app that integrates with Facebook and harvests your "Likes" that are papers.

Food for thought. Meantime, I hope users like Ed will find BioStor less tedious to use now that they can log in via Mendeley.

Tuesday, August 31, 2010

Viewing scientific articles on the iPad: Mendeley

Previously I've looked at the Nature, PLoS, and Papers apps, now it's the turn of the Mendeley iPad app. As before, this isn't a review of the app as such, I'm more interested in documenting how the app interface works, with a view to discovering if there are consistent metaphors we can use for navigating bibliographic databases.

Perhaps the key difference between Mendeley and the other apps is that Mendeley is cloud-based, in that the bibliography exists on Mendeley's servers, as well as locally on your desktop, iPad, or iPhone. Hence, whereas the Nature and PLoS apps consume a web stream of documents, and Papers enables you to sync collections between desktop and iOS devices, Mendeley syncs to central web server. At present this appears to be done over HTTPS. Mendeley recently released an API, which I've discussed at length. Mendeley's app doesn't use this API, which is a pity because if it did I suspect the API would be getting the love it needs from Mendeley's developers.

Like Papers, the Mendley app uses a split view, where the left-hand panel is used for navigation.

mendeley.png

You can drill down to lists of references, and display basic details about an article.

PDF
The Mendeley app is a PDF viewer, but whereas the PLoS app has page turning, and the Papers app scrolls pages from left to right, the Mendeley app displays PDF pages vertically (which is probably the more natural way to scroll through content on the iPad):

touch6.jpg

Summary
It's clearly early days for the Mendeley app, but it's worth noting two of its most obvious limitations. Firstly, it depends entirely on the user's existing Mendeley bibliography - you can't add to this using the app, it's simply a viewer. Compare this to Papers which can access a suite of search engines from which you can download new papers (albeit with some limitations, for example the Papers iPad app doesn't seem to support extracting metadata via XMP, unlike the desktop version). Secondly, despite Mendeley having as one of its goals being a
research network that allows you to keep track of your colleagues' publications, conference participations, awards etc., and helps you discover people with research interests similar to yours

the Mendeley app lacks any social features, apart from sharing by email(!). I think designing social interactions in bibliographic apps will be a challenge. For an example of what social reading can look like, check out Flipboard.

Wednesday, November 10, 2010

Mendeley mangles my references: phantom documents and the problem of duplicate references

One issue I'm running into with Mendeley is that it can create spurious documents, mangling my references in the process. This appears to be due to some over-zealous attempts to de-duplicate documents. Duplicate documents is the number one problem faced by Mendeley, and has been discussed in some detail by Duncan Hull in his post How many unique papers are there in Mendeley?. Duncan focussed on the case where the same article may appear multiple times in Mendeley's database, which will inflate estimates of how many distinct references the database contains. It also has implications for metrics derived from the Mendeley, such as those displayed by ReaderMeter.

In this post I discuss the reverse problem, combining two or more distinct references into one. I've been uploading large collections of references based on harvesting metadata for journal articles. Although the metadata isn't perfect, it's usually pretty good, and in many cases linked to Open Access content in BioStor. References that I upload appear in public groups listed on my profile, such as the group Proceedings of the Entomological Society of Washington.

Reverse engineering Mendeley
In the absence of a good description by Mendeley of how their tools work, we have to try and figure it out ourselves. If you click on a refernece that has been recently added to Mendeley you get a URL that looks like this: http://www.mendeley.com/c/3708087012/g/584201/magalhaes-2008-a-new-species-of-kingsleya-from-the-yanomami-indians-area-in-the-upper-rio-orinoco-venezuela-crustacea-decapoda-brachyura-pseudothelphusidae/ where 584201 is the group id, 3708087012 is the "remoteId" of the document (this is what it's called in the SQLite database that underlies the desktop client), and the rest of the URL is the article title, minus stop words.

After a while (perhaps a day or so) Mendeley gets around to trying to merge the references I've added with those it already knows about, and the URLs lose the group and remoteId and look like this: http://www.mendeley.com/research/review-genus-saemundssonia-timmerman-phthiraptera-philopteridae-alcidae-aves-charadriiformes-including-new-species-new-host/ . Let's call this document the "canonical document" (this document also has a UUID, which is what the Mendeley API uses to retrieve the document). Once the document gets one of these URLs Mendeley will also display how many people are "reading" that document, and whether anyone has tagged it.

But that's not my paper!
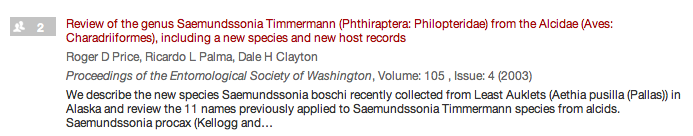
The problem is that sometimes (and more often than I'd like) the canonical document bears little relation to the document I uploaded. For example, here is a paper that I uploaded to the group Proceedings of the Entomological Society of Washington:

16212462.gifReview of the genus Saemundssonia Timmermann (Phthiraptera: Philopteridae) from the Alcidae (Aves: Charadriiformes), including a new species and new host records by Roger D Price, Ricardo L Palma, Dale H Clayton, Proceedings of the Entomological Society of Washington, 105(4):915-924 (2003).


You can see the actual paper in BioStor: http://biostor.org/reference/57185. To see the paper in the Mendeley group, browse it using the tag Phthiraptera:

group.png


Note the 2, indicating that two people (including myself) have this paper in their library. The URL for this paper is http://www.mendeley.com/research/review-genus-saemundssonia-timmerman-phthiraptera-philopteridae-alcidae-aves-charadriiformes-including-new-species-new-host/, but this is not the paper I added!.

What Mendeley displays for this URL is this:
dala.png


Not only is this not the paper I added, there is no such paper! There is a paper entitled "A new genus and a new species of Daladerini (Hemiptera: Heteroptera: Coreidae) from Madagascar", but that is by Harry Brailovsky, not Clayton and Price (you can see this paper in BioStor as http://biostor.org/reference/55669). The BioStor link for the phantom paper displayed by Mendeley, http://biostor.org/reference/55761, is for a third paper "A review of ground beetle species (Coleoptera: Carabidae) of Minnesota, United States : New records and range extensions". The table below shows the original details for the paper, the details for the "canonical paper" created by Mendeley, and the details for two papers that have some of the bibliographic details in common with this non-existent paper (highlighted in bold).

FieldOriginal paperMendeley
TitleReview of the genus Saemundssonia Timmermann (Phthiraptera: Philopteridae) from the Alcidae (Aves: Charadriiformes), including a new species and new host recordsA new genus and a new species of Daladerini (Hemiptera: Heteroptera: Coreidae) from MadagascarA new genus and a new species of Daladerini (Hemiptera: Heteroptera: Coreidae) from MadagascarA review of ground beetle species (Coleoptera: Carabidae) of Minnesota, United States : New records and range extensions
Author(s)Roger D Price, Ricardo L Palma, Dale H ClaytonDH Clayton, RD PriceHarry Brailovsky
Volume105105104107
Pages915-924915-924111-118917-940
BioStor57185557615566955761

As you can see it's a bit of a mess. Now, finding and merging duplicates is a hard problem (see doi:10.1145/1141753.1141817 for some background), but I'm struggling to see why these documents were considered to be duplicates.

What I'd like to see
I'm a big fan of Mendeley, so I'd like to see this problem fixed. What I'd really like to see is the following:
  1. Mendeley publish a description of how their de-duplication algorithms work

  2. Mendeley describe the series of steps a document goes through as they process it (if nothing else, so that users can make sense of the multiple URLs a document may get over it's lifetime in Mendeley).

  3. For each canonical reference Mendeley shows the the set of documents that have been merged to create that canonical reference, and display some measure of their confidence that the match is genuine.

  4. Mendeley enables users to provide feedback on a canonical document (e.g., a button by each document in the set that enables the user to say "yes this is a match" or "no, this isn't a match").


Perhaps what would be useful is if Mendeley (or the community) assemble a test collection of documents which contains duplicates, together with a set of the canonical documents this collection actually contains, and use this to evaluate alternative algorithms for finding duplicates. Let's make this a "challenge" with prizes! In many ways I'd be much more impressed by a duplication challenge than the DataTEL challenge, especially as it seems clear that Mendeley readership data is too sparse to generate useful recommendations (see Mendeley Data vs. Netflix Data).


Friday, September 10, 2010

CouchDB, Mendeley, and what I really want in an iPad article viewer

Playing with @couchdb, starting to think of the Mendeley API as a read/write JSON store, and having a reader app built on that...less than a minute ago via Tweetie for Mac


It's slowly dawning on me that many of the ingredients for an alternative different way to browse scientific articles may already be in place. After my first crude efforts at what an iPad reader might look like I've started afresh with a new attempt, based on the Sencha Touch framework. The goal here isn't to make a polished app, but rather to get a sense of what could be done.

The first goal is to be able to browse the literature as if it was a connected series of documents (which is what, of course, it is). This requires taking the full text of an article, extracting the citations, and making them links to further documents (also with their citations extracted, and so on). Leaving aside the obvious problem that this approach is limited to open access articles, an app that does this is going to have to store a lot of bibliographic data as the reader browses the literature (otherwise we going to have to do all the processing on the fly, and that's not going to be fast enough). So, we need some storage.

MySQL
One option is to write a MySQL database to hold articles, books, etc. Doable (I've done more of these than I care to remember), but things get messy pretty quickly, especially as you add functionality (tags, fulltext, figures, etc.).

RDF
Another option is to use RDF and a tripe store. I've played with linked data quite a bit lately (see previous "Friday follies" here and here), and I thought that a triple store would be a great way support an article browser (especially as we add additional kinds of data, such as sequences, specimens, phylogenies, etc.). But linked data is a mess. For the things I care about there are either no canonical identifiers, or too many, and rarely does the primary data provider served linked data compliant URLs (e.g., NCBI), hence we end up with a plethora of wrappers around these sources. Then there's the issue of what vocabularies to use (once again, there are either none, or too many). As a query language SPARQL isn't great, and don't even get me started on the issue of editing data. OK, so I get the whole idea of linked data, it's just that the overhead of getting anything done seems too high. You've got to get a lot of ducks to line up.

CounchDBlogo.png
So, I started playing with CounchDB, in a fairly idle way. I'd had a look before, but didn't really get my head around the very different way of querying a database that CouchDB requires. Despite this learning curve, CouchDB has some great features. It stores documents in JSON, which makes it trivial to add data as objects (instead of mucking around with breaking them up into tables for SQL, or atomising them into triples for RDF), it supports versioning right out of the box (vital because metadata is often wrong and needs to be tidied up), and you talk to it using HTTP, which means no middleware to get in the way. You just point your browser (or curl, or whatever HTTP tool you have) and send GET, POST, PUT, or DELETE commands. And now it's in the cloud.

In some ways ending up with CouchDB (or something similar) seems inevitable. The one "semantic web" tool that I've made most use of is Semantic MediaWiki, which powers the NCBI to Wikipedia mapping I created in June. Semantic Mediawiki has it's uses, but occasionally it has driven me to distraction. But, when you get down to it, Semantic Mediawiki is really just a versioned document store (where the documents are typically key-value pairs), over which have been laid a pretty limited query language and some RDF export features. Put like this, most of the huge Mediawiki engine underlying Semantic MediaWiki isn't needed, so why not cut to the chase and use a purpose-built versioned document store? Enter CouchDB.

Browsing and Mendeley
So, what I have in mind is a browser that crawls a document, extracting citations, and enabling the reader to explore those. Eventually it will also extract all the other chocolatey goodness in an article (sequences, specimens, taxonomic names, etc.), but for now I'm focussing on articles and citations. A browser would need to store article metadata (say, each time it encounters an article for the first time), as well as update existing metadata (by adding missing DOIs, PubMed ids, citations, etc.), so what easier way than as JSON in a document store such as CouchDB? This is what I'm exploring at the moment, but let's take a step back for a second.

The Mendeley API, as poorly developed as it is, could be treated as essentially a wrapper around a JSON document store (the API stores and returns JSON), and speaks HTTP. So, we could imagine a browser that crawls the Mendeley database, adding papers that aren't in Mendeley as it goes. The act of browsing and reading would actively contribute to the database. Of course, we could spin this around, and argue that a crawler + CouchDB could pretty effectively create a clone of Mendeley's database (albeit without the social networking features that come with have a large user community).

This is another reason why the current crop of iPad article viewers, Mendeley's included, are so disappointing. There's the potential to completely change the way we interact with the scientific literature (instead of passively consuming PDFs), and Mendeley is ideally positioned to support this. Yes, I realise that for the vast majority of people being able to manage their PDFs and format bibliographies in MS Word are the killer features, but, seriously, is that all we aspire too?

Friday, August 27, 2010

Navigating the Encyclopedia of Life tree on the desktop and the iPhone

This week seems to be API week. The Encyclopedia of Life API Beta Test has been out since August 12th. By comparison with the Mendeley API that I've spent rather too much time trying to get to grips with, the EOL API release seems rather understated.

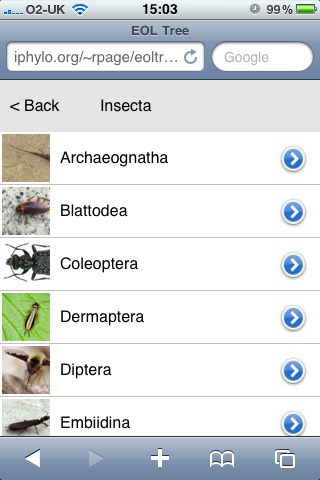
However, I've spent the last couple of days playing with it in order to build a simple tree navigating widget, which you can view at http://iphylo.org/~rpage/eoltree/.

The widget resembles Aaron Thompson's Taxonomy (formerly called KPCOFGS) iPhone app in that it uses the iPhone table view to list all the taxa at a given level in a taxonomic tree. Clicking on a row in this table takes you to the descendants of the corresponding taxon, clicking "Back" takes you back up the tree. if you've reached a leave node (typically a species) the widget displays a snippet of information about that taxon. It also resembles Javier de la Torre's taxonomic browser written in Flex.

Here's a screen shot of the widget running in a desktop web browser:

insecta.png

Here's the same widget in the iPhone web browser:

web.pngUsing the API
The EOL API is pretty straightforward. I call the http://www.eol.org/api/docs/hierarchy_entries API to get the tree rooted at a given node, then populate each child of that node using http://www.eol.org/api/docs/pages. The result is a simple JSON file that I cache locally to speed up performance and avoid hitting the EOL servers for the same information. because I'm locally caching the API calls I need a couple of PHP scripts to do this, but everything else is HTML and Javascript.

iPhone and iPad
I've not really developed this for the iPhone. I've cobbled together some crude Javascript to simulate some iPhone-like effects, but if I was serious about the phone I'd look into one of the Javascript kits available for iPhone development. However, I did want something that was similar in size to the iPhone screen. The reason is I'm looking at adding taxonomic browsing to the geographic browser I described in the post Browsing a digital library using a map, so I wanted something easy to use but which didn't take up too much space. In the same way that the Pygmybrowse tree viewer I played with in 2006 was a solution to viewing a tree on a small screen, I think developing for the iPhone forces you to strip things down to the bare essentials.

I'm also keeping the iPad in mind. In portrait mode some apps display lists in a popover like this:

popover_flatten.png

This popover takes up a similar amount of screen space to the entire iPhone screen, so if I was to have a web app (or native app) that had taxonomic navigation, I'd want it to be about the size of the iPhone.

Let me know what you think. Meantime I need to think about bolting this onto the map browser, and providing a combined taxonomic and geographic perspective on a set of documents,

Friday, January 09, 2015

GBIF, biodiversity informatics and the "platform rant"

Each year about this time, as I ponder what to devote my time on in the coming year, I get exasperated and frustrated that each year will be like the previous one, and biodiversity informatics will seem no closer to getting its act together. Sure, we are putting more and more data online, but we are no closer to linking this stuff together, or building things that people can use to do cool science with. And each year I try and figure out why we are still flaying about and not getting very far. This year, I've settled on the lack of "platforms".

In 2011 Steve Yegge (accidentally) published a widely read document known as the "Google Platforms Rant". It's become something of a classic, and I wonder if biodiversity informatics can learn from this rant (it's long but well worth a read).

One way to think about this is to look at how we build things. In the early days, people would have some data and build a web site:

Rant1

In the diagram above "dev" is the web developer who builds the site, and "DBA" is the person who manages the data (for many projects this is one and the same person). The user is presented with a web site, and that's the only way they can access the data. If the web site is well designed this typically works OK, but the user will come up against limitations. Why do I have to manually search for each record? How can I combine this data with some other data? These questions lead to some users doing things like screen scrapping, anything to get the data and do more than the web site permits (I spend a lot of my time doing exactly this). In contrast, the person (or team) building the site ("dev") can access the data and tools directly.

Eventually some sites realise that they could add value to their users if they added an API, so typically we get something like this:

Rant2

Now we have an API (yay), but notice that it is completely separate from the web site. Now the site developers have to manage two different things, and two sets of users (web site visitors, and user programming against the API). Because the site and the API are different, and the site gets more users, typically what happens is the API lacks much of the functionality of the site, which frustrates users of the API. For example, when Mendeley launched it's API its limited functionality and lack of documentation drove me nuts. Similarly, the Encyclopedia of Life (EOL) API is pretty sucky. If anyone from EOL is reading this, for the love of God add user authentication and the ability to create and edit collections to the API. Until you do, you'll never have an ecosystem of apps.

A solution to sucky APIs is "dogfooding":

Rant3

Dogfooding is the idea that your product is so good you'd use it yourself. In the case of web development, if we build the web site on top of the same API that we expose to users, then the site developers have a strong incentive to make the API well-documented and robust, because their web site runs on the same services. As a result the interests of the web developers and users who are programmers are much more aligned. If a user finds a bug in the API, or the API lacks a feature, it's much more likely to get fixed. An example of a biodiversity informatics project that "gets" dogfooding is GBIF, which has a nice API that powers much of their web site. This is a good example of how to tell if an API is any good, namely, can you recreate the web site yourself just using the API?

But the example above leaves one aspect of the whole system still intact and not accessible to users. Typically a company or organisation has data, tools, and processes that it uses to manage whatever is central to its operations. These are kept separate from users, who only get to access these indirectly through the web site or the API.

A "platform" takes things one step further. Steve Yegge summarises Jeff Bezos' memo that outlined Amazon's move to a platform:

  1. All teams will henceforth expose their data and functionality through service interfaces.
  2. Teams must communicate with each other through these interfaces.
  3. There will be no other form of interprocess communication allowed: no direct linking, no direct reads of another team's data store, no shared-memory model, no back-doors whatsoever. The only communication allowed is via service interface calls over the network.
  4. It doesn't matter what technology they use. HTTP, Corba, Pubsub, custom protocols -- doesn't matter. Bezos doesn't care.
  5. All service interfaces, without exception, must be designed from the ground up to be externalizable. That is to say, the team must plan and design to be able to expose the interface to developers in the outside world. No exceptions.
  6. Anyone who doesn't do this will be fired.
  7. Thank you; have a nice day!
All the core bits of infrastructure that powered Amazon were to become services, and different bits of Amazon could only talk to each other through these services. The point of this is that it enabled Amazon to expose its infrastructure to the outside world (AKA paying customers) and now we have Amazon cloud services for storing data, running compute jobs, and so on. By exposing its infrastructure as services, Amazon now runs a big chunk of the startup economy. By insisting that Amazon itself uses these services (dogfooding at the infrastructure level), Amazon ensures that this infrastructure works (because its own business depends on it).

Rant4

There are some things Google does that are like a platform (despite the complaints in the "Google Platforms Rant"). For example, you could imagine that most workers at Google use tools such as Google Docs to create and share documents. Likewise, Google Scholar is unlikely to be a simple act of altruism. If you have a team of world class researchers you need a tool that enables them to find existing research. Google Scholar does this. If you then expose it to the outside world you get more users, and an incentive for commercial publishers to open up their paywall journals to being indexed by Google's crawlers, and incentive that would be missing if Scholar was purely an internal service.

Now, giant companies like Amazon and Google might seem a world away from biodiversity informatics, but I think there are things we can learn from this. Looking around, I think there are other examples of platforms that may seem closer to home. For example, the NCBI runs GenBank and PubMed, and these are very like platforms. GenBank provides tools, such as BLAST, that it provides to the user community, but which it also uses internally to cluster sequences into related sets. Consider PubMed, which has gone from a simple index to the biomedical literature to a publishing platform. PubMed has driven the standardisation of XML across biomedical publishers. It is quite possible to visit the NCBI site, explore data, then read full text for the associated publications in PubMed Central, without ever leaving the NCBI site. No wonder some commercial publishers are deeply worried about PubMed Central.

A key thing about platforms is that the people running the platform have a deep interest in many of the same things as the users of that platform (note the "users" scattered all over the platform diagram above). Instead of user being a separate category that you try and serve by figuring out what they want, developers are users too.

To try and flesh this out a little more, what would a "taxonomic" platform look like? At the moment, we have lots of taxonomic web sites that pump out lists of names and little else. This is not terribly useful. If we think about what goes into making lists of names, it requires access to the scientific literature, it requires being able to read that literature and extract statements about names (e.g., this is the original description, these two names are synonyms, etc.), and it requires some way of summarising what we know about those names and the taxa that we label with those names. Typically these are all things that happen behind the scenes, then the user simply gets a list of names. A platform would expose all of the data, tools, and processes that went into making that list. It would provide the literature in both human and computer readable forms, it would provide tools for extracting information, tools to store knowledge about those names, and tools to make inferences using that knowledge. All of these would be exposed to users. And these some services and tools would be used by the people building those services and tools.

This last point means that you also need people working on the same problems as "users". For example, consider something like GBIF. At the moment GBIF consumes output of taxonomic research (such as lists of names) and tries to make sense of these before serving them back to the community. There is little alignment between the interests of taxonomists and GBIF itself. For GBIF to become a taxonomic platform, it would need to provide the data, tools and services for people to do taxonomic research, and ideally it would actually have taxonomists working at GBIF using those tools (these taxonomists could, for example, be visiting fellows working on particular taxa, rather than permanent employees). These tools would greatly help the taxonomic community, but also help GBIF make sense of the millions of names it has to interpret.

It's important to note here the the goal of the platform is NOT to "help" users - that simply reinforces the distinction between you and the "users". Instead it is to become a user. You may have more resources, and work on a different scale (few business Amazon's services support will be anything like as big as Amazon), but you are ultimately "just" another user.
Tuesday, March 01, 2011

Mendeley, OpenURL, BioStor, and BHL

Mendeley has added a feature which makes it easier to use Mendeley with repositories such as BioStor and BHL. As announced in Get Full Text: Mendeley now works with your local library via OpenURL, you can now add OpenURL resolvers to your Mendeley account:
We’ve added a button to the catalog pages that will allow you to get the article from your library right in Mendeley. This feature will link you directly to the full text copy according to your institutional access rights.
Ironically, in the UK access to electronic articles from a University is pretty seamless via the UK Access Management Federation, so I don't need to add an OpenURL resolver to get full text for an article. But this new feature does enable another way to access to articles in my BioStor repository. By adding the BioStor OpenURL to your Mendeley account, you can search for articles from your Mendeley library in BioStor.

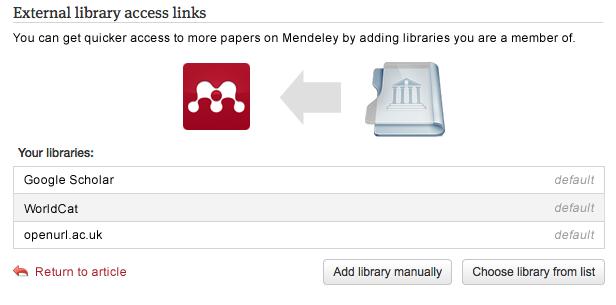
The Mendeley blog post explains how to set up an OpenURL resolver. Go to your Mendeley account and click on the My Account button in the upper right corner of then page, then select Account Details, then the Sharing/Importing tab, or just click here.

openurl_settings.jpg

Click on Add library manually, then enter the name of the resolver (e.g., "BioStor") and the URL http://biostor.org/openurl:

Snapshot 2011-03-01 07-37-20.png

If you view a reference in Mendeley, you will now see something like this:

Snapshot 2011-03-01 07-40-04.png

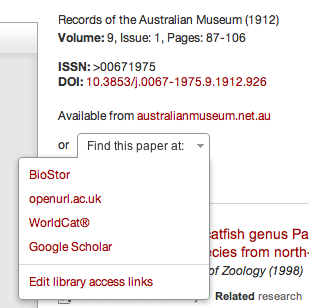
In addition to the DOI and the URL, this reference now displays a Find this paper at menu. Clicking on it shows the default services, together with any OpenURL resolvers you've added (in this case, BioStor):
Snapshot 2011-03-01 07-42-50.png

You can add multiple resolvers, so we could add the BHL OpenURL resolver http://www.biodiversitylibrary.org/openurl, although finding articles isn't BHL OpenURL resolver's strong point.

Now, what would be very handy is if Mendeley were to complete the circle by providing their own OpenURL resolver, so that people could find articles in Mendeley from metadata such as article title, journal, volume, and starting page. The Mendeley API might be a way to implement this, although its search features lack the granularity needed.

Tuesday, September 13, 2011

Phantom articles: why Mendeley needs to make duplication transparent

Browsing Mendeley I found the following record: http://www.mendeley.com/research/description-larva/. This URL is for a paper
Costa, J. M., & Santos, T. C. (2008). Description of the larva of. Zootaxa, 99(2), 129-131
which apparently has the DOI doi:10.1645/GE-2580.1. This is strange because Zootaxa doesn't have DOIs. The DOI given resolves to a paper in the Journal of Parasitology:
Harriman, V. B., Galloway, T. D., Alisauskas, R. T., & Wobeser, G. A. (2011). Description of the larva of Ceratophyllus vagabundus vagabundus (Siphonaptera: Ceratophyllidae) from nests of Rossʼs and lesser snow geese in Nunavut, Canada. The Journal of parasitology, 93(2), 197-200
Now, this paper has it's own record in Mendeley.

OK, so this is weird..., but it gets weirder. If you look at the Mendeley page for this chimeric article there is a PDF preview of yet another article:
LOPES, Maria José Nascimento; FROEHLICH, Claudio Gilberto and DOMINGUEZ, Eduardo (2003). Description of the larva of Thraulodes schlingeri (Ephemeroptera, Leptophlebiidae). Iheringia, Sér. Zool. 92(2), 197-200 2003 doi:10.1590/S0073-47212003000200011
Mendeley duplicate

But it gets even more interesting. The abstract for the phantom Zootaxa article belongs to yet another paper:
Marques, K. I. D. S., & Xerez, R. D.Description of the larva of Popanomyia kerteszi James & Woodley (Diptera: Stratiomyidae) and identification key to immature stages of Pachygastrinae. Neotropical Entomology, 38(5), 643-648.
which also exists in Mendeley.

To investigate further I used Mendeley's API to retrieve this record (I had to look at the source of the web page to find the internal identifier used by Mendeley, namely 010c48d0-edb5-11df-99a6-0024e8453de6 to do this, why does Mendeley hide these?). Here's the abbreviated JSON for this record.

{
...
"website": "http:\/\/www.ncbi.nlm.nih.gov\/pubmed\/21506868",
"identifiers": {
"pmid": "21506868",
"issn": "19372345",
"doi": "10.1645\/GE-2580.1"
},
...
"issue": "2",
"pages": "129-131",
"public_file_hash": "fe7eed3f6c43a3be1480a0937229b9ad33666df4",
"publication_outlet": "Zootaxa",
"type": "Journal Article",
"mendeley_url": "http:\/\/www.mendeley.com\/research\/description-larva\/",
"uuid": "010c48d0-edb5-11df-99a6-0024e8453de6",
"authors": [
{
"forename": "J M",
"surname": "Costa"
},
{
"forename": "T C",
"surname": "Santos"
}
],
"title": "Description of the larva of",
"volume": "99",
"year": 2008,
"categories": [
39,
203,
37,
52,
43,
40,
210
],
"oa_journal": false
}

Doesn't add much to the story, but does give us the sha1 for the PDF for the chimeric article (fe7eed3f6c43a3be1480a0937229b9ad33666df4). If I download the PDF for the article in Iheringia, Sér. Zool. it has the same sha1:


openssl sha1 a11v93n2.pdf
SHA1(a11v93n2.pdf)= fe7eed3f6c43a3be1480a0937229b9ad33666df4

This article doesn't exist
So, to summarise, this paper doesn't exist. It is credited to a journal that doesn't have DOIs, the DOI resolves to an article in a different journal, the abstract comes from another article in another journal, and the PDF is from a third article. OMG!

This is just weird
So, something about the way Mendeley merges references is broken. Merging references is a tough problem so there will always be cases where things go wrong. But it would be really, really helpful if Mendeley could display the set of articles that it has merged to create each canonical reference (say by listing the UUIDs for each article). Users could then see if badness had happened, and provide feedback, for example by highlighting references that are clearly the same, and those that are clearly different. Until this happens I'm a bit nervous about trusting Mendeley with my bibliographic data, I don't want it mangled into chimeric papers that don't exist.

Saturday, June 11, 2011

Mendeley Hack4Knowledge: towards an "ego wall"

I'm taking a virtual part in Mendeley's Hack4Knowledge event. I'm using this a chance to explore some ideas about building novel interfaces to bibliographic data in Mendeley. One idea is to display a user's entire library in one screen. I think the user interfaces employed by most bibliographic software are too conservative and there some cool things that could be done. For example, see A fluid treemap interface for personal digital libraries (doi:10.1145/1065385.1065512, PDF available from CiteSeer).

One idea I'm playing with is to display all a Mendeley user's papers as a quantum treemap, with thumbnails of the papers and "badges" indicating, for example, how many readers each paper has. The idea is that at a glance you can see all your publications, and which ones are being read the most. You can think of it as an "ego wall" — a quick way to see what others think about your work. Below is part of my library. You can see the full treemap here as an SVG file. Imagine this as an iPad interface to a user's Mendeley library.

Wall

Eventually I'll make this live. I'm doing this yet as the script to create the visualisation is slow due to the multiple requests I need to make to get the necessary information. I have to get the list of a user's papers from Mendeley, then I call the API for each paper to get basic bibliographic details. I have to screen scrape the corresponding paper's web page to get the thumbnail and the paper's UUID, which I can then use to get the readership stats via Mendeley's API via yet another API call. Sigh.

Anyway, this is enough hacking for one day. Hope to spend some more time on this project tomorrow.


Tuesday, March 08, 2011

The Mendeley API Binary Battle - win $US 10,001

Now we'll bring the awesome. Mendeley have announced The Mendeley API Binary Battle, with a first prize of $US 10,0001, and some very high-profile judges (Juan Enriquez, Tim O'Reilly, James Powell, Werner Vogels, and John Wilbanks). Deadline for submission is August 31st 2011, with the results announced in October.

The criterion for judging are:
  1. How active is your application? We’ll look at your API key usage.

  2. How viral is the app? We’ll look at the number of sign ups on Mendeley and/or your application, and we’ll also have an eye on Twitter.

  3. Does the application increase collaboration and/or transparency? We’ll look at how much your application contributes to making science more open.

  4. How cool is your app? Does it make our jaws drop? Is it the most fun that you can have with your pants on? Is it making use of Facebook, Twitter, etc.?

  5. The Binary Battle is open to apps built previous to this announcement.


Start your engines...

Wednesday, September 07, 2011

Suggested apps for BHL's Life and Literature Code Challenge


Since I won't be able to be at the Biodiversity Heritage Library's Life and Literature meeting I thought I'd share some ideas for their Life and Literature Code Challenge. The deadline is pretty close (October 17) so having ideas now isn't terribly helpful I admit. That aside, here are some thoughts inspired by the challenge. In part this post has been inspired by the Results of the PLoS and Mendeley "Call for Apps", where PLoS and Mendeley asked for people (not necessarily developers) to suggest the kind of apps they'd like to see. As an aside, one thing conspicuous by it's absence is a prize for winning the challenge. PLoS and Mendeley have a "API Binary Battle" with a prize of $US 10,001, which seems more likely to inspire people to take part.

Visual search engine
I suspect that many BHL users are looking for illustrations (exemplified by the images being gathered in BHL's Flickr group). One way to search for images would be to search within the OCR text for figure and plate captions, such as "Fig. 1". Indexing these captions by taxonomic name would provide a simple image search tool. For modern publications most figures are on the same page as the caption, but for older publications with illustrations as plates, the caption and corresponding image may be separated (e.g., on facing pages), so the search results might need to show pages around the page containing the caption. As an aside, it's a pity the Flickr images only link to the BHL item and not the BHL page. If they did the later, and the images were tagged with what they depict, you could great a visual search engine using the Flickr API (of course, this might be just the way to implement the visual search engine — harvest images, tags with PageID and taxon names, upload to Flickr).

Mobile interface
The BHL web site doesn't look great on an iPhone. It makes no concessions to the mobile device, and there are some weird things such as the way the list of pages is rendered. A number of mainstream science publishers are exploring mobile versions of their web sites, for example Taylor and Francis have a jQuery Mobile powered interface for mobile users. I've explored iPad interfaces to scientific articles in previous posts. BHL content posses some challenges, but is fundamentally the same as viewing PDFs — you have fixed pages that you may want to zoom.

OCR correction
There is a lot of scope for cleaning up the OCR text in BHL. Part of the trick would be to have a simple use interface for people to contribute to this task. In an earlier post I discussed a Firefox hOCR add-on that provides a nice way to do this. Take this as a starting point, add a way to save the cleaned up text, and you'd be well on the way to making a useful tool.

Taxon name timeline
Despite the shiny new interface, the Encyclopedia of Life still displays BHL literature in the same clunky way I described in an earlier blog post. It would great to have a timeline of the usage of a name, especially if you could compare the usage of different names (such as synonyms). In many ways this is the BHL equivalent Google Books Ngram viewer.

These are just a few hastily put together thoughts. If you have any other ideas or suggestions, feel free to add them as comments below.

- Posted using BlogPress from my iPad