Monday, October 25, 2010

Are names really the key to the big new biology?

David ("Paddy") Patterson, Jerry Cooper, Paul Kirk, Rich Pyle, and David Remsen have published an article in TREE entitled "Names are key to the big new biology" (doi:10.1016/j.tree.2010.09.004). The abstract states:

Those who seek answers to big, broad questions about biology, especially questions emphasizing the organism (taxonomy, evolution and ecology), will soon benefit from an emerging names-based infrastructure. It will draw on the almost universal association of organism names with biological information to index and interconnect information distributed across the Internet. The result will be a virtual data commons, expanding as further data are shared, allowing biology to become more of a ‘big science’. Informatics devices will exploit this ‘big new biology’, revitalizing comparative biology with a broad perspective to reveal previously inaccessible trends and discontinuities, so helping us to reveal unfamiliar biological truths. Here, we review the first components of this freely available, participatory and semantic Global Names Architecture.
Do we need names?

Reading this (full disclosure, I was a reviewer) I can't wondering whether the assumption that names are key really needs to be challenged. Roger Hyam has argued that we should be calling time on biological nomenclature, and I wonder whether for a generation of biologists brought up on DNA barcodes and GPS, taxonomy and names will seem horribly quaint. For a start, sequences and GPS coordinates are computable, we can stick them in computers and do useful things with them. DNA barcodes can be used to infer identity, evolutionary relationships, and dates of divergence. Taken in aggregate we can infer ecological relationships (such as diet, e.g., doi:10.1371/journal.pone.0000831), biogeographic history, gene flow, etc. While barcodes can tells us something about an organism, names don't. Even if we have the taxonomic description we can't do much with it — extracting information from taxonomic descriptions is hard.

Furthermore, formal taxonomic names don't seem terribly necessary in order to do a lot of science. Patterson et al. note that taxa may have "surrogate" names":

Surrogates include provisional names and specimen, culture or strain numbers which refer to a taxon. 'SAR-11' ('SAR' refers to the Sargasso Sea) was a surrogate name given in 1990 to an important member of the marine plankton. Only a decade later did it become known as Pelagibacter ubique.


The name Pelagibacter ubique was published in 2002 (doi:10.1038/nature00917), although as a Candidatus name (doi:10.1099/00207713-45-1-186), not a name conforming to the International Code of Nomenclature of Bacteria. I doubt the lack of a name that follows this code is hindering the study of this organism, and researchers seem happy to continue to use 'SAR11'.

So, I think that as we go forward we are going to find nomenclature struggling to establish its relevance in the age of digital biology.

If we do need them, how do we manage them?
If we grant Patterson et al. their premise that names matter (and for a lot of the legacy literature they will), then how do we manage them? In many ways the "Names are key to the big new biology" paper is really a pitch for the Global Names Architecture or GNA (and it's components GNI, GNITE, and GNUB). So, we're off into alphabet soup again (sigh). The more I think about this the more I want something very simple.

Names
All I want here is a database of name strings and tools to find them in documents. In other words, uBio.

Documents
Broadly defined to include articles, books, DNA sequences, specimens, etc. I want an database of [name,document] pairs (BHL has a huge one), and a database of documents.

namedocs.jpg

Realistically, given the number and type of documents there will be several "document" databases, such as GenBank and GBIF. For citations Mendeley looks very promising. If we had every taxonomic publication in Mendeley, tagged with scientific names, then we'd have the bibliography of life. Taxonomic nomenclators would be essentially out of business, given that their function is to store the first publication of a name. Given a complete bibliography we just create a timeline of usage for a name and note the earliest [name,document] pair:

timeline.jpgTaxonomy
There are a few wrinkles to deal with. Firstly, names may have synonyms, lexical variants, etc. (the Patterson et al. paper has a nice example of this). Leaving aside lexical variants, what we want is a "view" of the [name,document] pairs that says this subset refer to the same thing (the "taxon concept").

concept.jpg

We can obsess with details in individual cases, but at web-scale there are only two ones that spring to mind. The first is the Catalogue of Life, the second is NCBI. The Catalogue of Life lists sets of names and reference that it regards as being the same thing, although it does unspeakable things to many of the references. In the case of NCBI the "concepts" would be the sets of DNA sequences and associated publications linked to the same taxonomy id. Whatever you think of the NCBI taxonomy, it is at least computable, in the sense that you could take a taxon and generate a list of publications 'about" that taxon.

So, we have names, [name,document] pairs, and sets of [name,document] pairs. Simples.

Thursday, October 21, 2010

Mendeley, BHL, and the "Bibliography of Life"

One of my hobby horses is the disservice taxonomic databases do their users by not linking to original scientific literature. Typically, taxonomic databases either don't cite primary literature, or regurgitate citations as cryptic text strings, leaving the user to try and find item being referred to. With the growing number of publishers that are digitising legacy literature and issuing DOIs, together with the Biodiversity Heritage Library's (BHL) enormous archive, there's really no excuse for this.

Taxonomic databases often cite references in abbreviated forms, or refer to individual pages, rather than citable units such as articles (see my Nomenclators + digitised literature = fail post for details). One way to translate these into links to articles would be to have a tool that could find a page within an article, or could match an abbreviated citation to a full one. This task would be relatively straightforward if we had the "bibliography of life," a freely accessible bibliography of every taxonomic paper ever published. Sadly, we don't...yet.

Bibliography of life

Mendeley is rapidly building a very large bibliography (although exactly how large is a matter of some dispute, see Duncan Hull's How many unique papers are there in Mendeley?), and I'm starting to explore using it as a way to store bibliographic details on a large scale. For example, an increasing number of smaller museum or society journals are putting lists of all their published articles on the web. Typically these are HTML pages rather than bibliographic data, but with a bit of scraping we can convert them to something useful, such as RIS format and import them in to Mendeley. I've started to do this, creating Mendeley groups for individual journals, e.g.:

These lists aren't necessarily complete nor error-free, but they contain the metadata for several thousand articles. If individual societies and museums made their list of publications freely available we would make significant progress towards building a bibliography of life. And with the social networking features of Mendeley, we could have groups of collaborators clean up any errors in the metadata.

Of course, this isn't the only way to do this. I suspect I'm rather atypical in building Mendeley groups containing articles from only one journal, as opposed to groups based on specific topics, and of course we could also tackle the problem by creating groups with a taxonomic focus (such as all taxonomic papers on amphibians). Furthermore, if and when more taxonomists join Mendeley and share their personal bibliographies, we will get a lot more relevant articles "for free." This is Mendeley's real strength in my opinion: it provides rich tools for users to do what they most want to do (manage their PDFs and cite them when they write papers), but off the back of that Mendeley can support larger tasks (in the same way that Flickr's ability to store geotagged photos has lead to some very interesting visualisations of aggregated data).

BioStor
cover.png
For some of the journals I've added to Mendeley I just have bibliographic data, the actual content isn't freely available on line, and in some cases isn't event digitised. But for some journals the content exists in BHL, it's "just" a matter of finding it. This is where my BioStor project comes in. For example, BHL has scanned most of the journal Spixiana. While BHL recognises individual volumes (see http://www.biodiversitylibrary.org/bibliography/40214) it has no notion of articles. To find these I scraped the tables of contents on the Spixiana web site and ran them through BioStor's OpenURL resolver. If you visit the BioStor page for the journal (http://biostor.org/issn/0341-8391) you will see that most of the articles have been identified in BHL, although there are a few holes that will need to be filled.
spixiana.png

These articles are listed in a Mendeley group for Spixiana, with the articles linked to BioStor wherever possible.

CiteBank and on not reinventing the wheel
If we were to use Mendeley as the primary platform for aggregating taxonomic publications, then I see this as the best way to implement "CiteBank". BHL have created CiteBank as an "an open access repository for biodiversity publications" using Drupal. Whatever one thinks of Drupal, bibliographic management is not an area where it shines. I think the taxonomic community should take a good look at Mendeley and ask themselves whether this is the platform around which they could build the bibliography of life.

Friday, October 08, 2010

Towards an interactive DjVu file viewer for the BHL

The bulk of the Biodiversity Heritage Library's content is available as DjVu files, which package together scanned page images and OCR text. Websites such as BHL or my own BioStor display page images, but there's no way to interact with the page content itself. Because it's just a bitmap image there's no obvious way to do simple things such as select and copy some text, click on some text and correct the OCR, or highlight some text as a taxonomic name or bibliographic citation. This is frustrating, and greatly limits what we can do with BHL's content.

In March I wrote a short post DjVu XML to HTML showing how to pull out and display the text boxes for a DjVu file. I've put this example, together with links to the XSLT file I use to do the transformation online at Display text boxes in a DjVu page. Here's an example, where each box (a DIV element) corresponds to a fragment of text extracted by OCR software.

boxes.png

The next step is to make this interactive. Inspired by Google's Javascript-based PDF viewer (see How does the Google Docs PDF viewer work?), I've revisited this problem. One thing the Google PDF viewer does nicely is enable you to select a block of text from a PDF page, in the same way that you can in a native PDF viewer such as Adobe Acrobat or Mac OS X Preview. It's quite a trick, because Google is displaying a bitmap image of the PDF page. So, can we do something similar for DjVu?

The thing I'd like to do is something what is shown below — drag a "rubber band" on the page and select all the text that falls within that rectangle:

textselection.png

This boils down to knowing for each text box whether it is inside or outside the selection rectangle:

selection.png


Implementation

We could try and solve this by brute force, that is, query each text box on the page to see whether it overlaps with the selection or not, but we can make use of a data structure called an R-tree to speed things up. I stumbled across Jon-Carlos Rivera's R-Tree Library for Javascript, and so was inspired to try and implement DjVu text selection in a web browser using this technique.

The basic approach is as follows:

  1. Extract text boxes from DjVu XML file and lay these over the scanned page image.

  2. Add each text box to a R-tree index, together with the "id" attribute of the corresponding DIV on the web page, and the OCR text string from that text box.

  3. Track mouse events on the page, when the user clicks with the mouse we create a selection rectangle ("rubber band"), and as the mouse moves we query the R-tree to discover which text boxes have any portion of their extent within the selection rectangle.

  4. Text boxes in the selection have their background colour set to an semi-transparent shade of blue, so that the user can see the extent of the selected text. Boxes outside the selection are hidden.

  5. When the user releases the mouse we get the list of text boxes from the R-tree, and concatenate the text corresponding to each box, and finally display the resulting selection to the user.


Copying text

So far so good, but what can we do with the selected text? One obvious thing would be to copy and paste it (for example, we could select a species distribution and paste it into a text editor). Since all we've done is highlight some DIVs on a web page, how can we get the browser to realise that it has some text it can copy to the clipboard? After browsing Stack Overflow I came across this question, which gives us some clues. It's a bit of a hack, but behind the page image I've hidden a TEXTAREA element, and when the user has selected some text I populate the TEXTAREA with the corresponding text, then set the browser's selection range to that text. As a consequence, the browser's Copy command (⌘C on a Mac) will copy the text to the clipboard.

Demo

You can view the demo here. It only works in Safari and Chrome, I've not had a chance to address cross-browser compatibility. It also works in the iPad, which seems a natural device to support interactive editing and annotation of BHL text, but you need to click on the button On iPad click here to select text before selecting text. This is an ugly hack, so I need to give a bit more thought to how to support the iPad touch screen, while still enabling users to pan and zoom the page image.

Next steps

This is all very crude, but I think it shows what can be done. There are some obvious next steps:

  • Enable selected text to be edited so that we can correct the underlying OCR text.

  • Add tools that operate on the selected text, such as check whether it is a taxonomic name, or if it is a bibliographic citation we could attempt to parse it and locate it online (such as David Shorthouse's reference parser).

  • Select parts of the page image itself, so that we could extract a figure or map.

  • Add "post it note" style annotations.

  • Add services that store the edits and annotations, and display annotations made by others.


Lots to do. I foresee a lot of Javascript hacking over the coming weeks.

Tuesday, October 05, 2010

Scripting Life

Not really a blog post, more a note to self. If I ever did get around to writing a book again, I think Scripting Life would be a great title.

PLoS Biodiversity Hub launches

hubs.png

The PLoS Biodiversity Hub has launched today. There's a PLoS blog post explaining the background to the project, as well as a summary on the Hub itself:

The vision behind the creation of PLoS Hubs is to show how open-access literature can be reused and reorganized, filtered, and assessed to enable the exchange of research, opinion, and data between community members.

PLoS Hubs: Biodiversity provides two main functions to connect researchers with relevant content. First, open-access articles on the broad theme of biodiversity are selected and imported into the Hub. In time, the content will also be enhanced so that the articles are connected with data, and we will provide features to make the articles easier for people to use. These two functions - aggregation and adding value - build on the concept of open access, which removes all the barriers to access and reuse of journal article content.


Readers of iPhylo may recall my account of one of the meetings involved in setting up this hub, in which I began to despair about the lack of readiness of biodiversity informatics to provide much of the information needed for projects such as hubs. Despite this (or perhaps, because of it), I've become a member of the steering committee for the Biodiversity Hub. There's clearly a lot of interest in repurposing the content found in scientific articles, and I think we're going to see an increasing number of similar projects from the major players in science publishing, Open Access or otherwise. One of the challenges is going to be moving beyond the obvious things (such as making taxon names clickable) to enable new kinds of ways of reading, navigating, and querying the literature, and exploring ways to track the use that is made of the information in these articles. Biodiversity studies are ideally placed to explore this as the subject is data rich and much of that data, such as specimens and DNA sequences, persist over time and hence get reused (data citation gets very boring if the data is used just once). We also have obvious ways to enrich navigation, such as spatially and taxonomically.

For now the PLoS Biodiversity Hub is very pretty, but it's more a statement of intent than a real demonstration of what can be done. Let's hope our field gets its act together and seizes the opportunity that initiatives like the Hub represents. Publishers are desperate to differentiate themselves from their competitors by providing added value as part of the publication process, and they provide a real use case for all the data that the biodiversity projects have been accumulating over the last couple of decades.

Friday, October 01, 2010

Replicating and forking data in 2010: Catalogue of Life and CouchDB

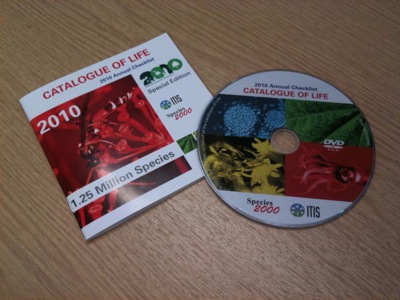
Time (just) for a Friday folly. A couple of days ago the latest edition of the Catalogue of Life (CoL) arrived in my mailbox in the form of a DVD and booklet:

photo.JPG
While in some ways it's wonderful that the Catalogue of Life provides a complete data dump of its contents, this strikes me as a rather old-fashioned way to distribute it. So I began to wonder how this could be done differently, and started to think of CouchDB. In particular, I began to think of being able to upload the data to a service (such as Cloudant) where the data could be stored and replicated at scale. then I began to think about forking the data. The Catalogue of Life has some good things going for it (some 1.25 million species, and around 2 million names), and is widely used as the backbone of sites such as EOL, GBIF, and iNaturalist.org, but parts of it are broken. Literature citations are often incomplete or mangled, and in places it is horribly out of date.

Rather than wait for the Catalogue of Life to fix this, what if we could share the data, annotate it, correct mistakes, and add links? In particular, what if we link the literature to records in the Biodiversity Heritage Library so at we can finally start to connect names to the primary literature (imagine clicking on a name and being able to see the original species description). We could have something akin to github, but instead of downloading and forking code, we download and fork data. CouchDB makes replicating data pretty straightforward.

So, I've started to upload some Catalogue of Life records to a CouchDB instance at Cloudant, and write a simple web site to display these records. For example, you can see the record for at http://iphylo.org/~rpage/col/?id=e9fda47629c1102b9a4a00304854f820:

croc.png
The e9fda47629c1102b9a4a00304854f820 in this URL is the UUID of the record in CouchDB, which is also the UUID embedded in the (non-functional) CoL LSIDs. This ensures the records have a unique identifier, but also one that is related to the original record. You can search for names, or browse the immediate hierarchy around a name. I hope to add more records over time as I explore this further — at the moment I've added a few lizards, wasps, and conifers while I explore how to convert the CoL records into a sensible JSON object to upload to CouchDB.

The next step is to think about this as a way to distribute data (want a copy of CoL, just point your CouchDB at the Cloudant URL and replicate it), and to think about how to build upon the basic records, editing and improving them, then thinking about how to get that information into a future version of the Catalogue.

Friday, September 24, 2010

Mendeley Connect

When I first launched BioStor (an article finding tool built on the top of the (Biodiversity heritage Library) I wanted people to be able to edit metadata and add references, but also minimise the chances that junk would get added. As a quick and dirty deterrent I used reCAPTCHA, so anybody adding a reference or editing the metadata had to pass a CAPTHCA before their edits were accepted.

While reCAPTCHA does the trick, it can be tedious for somebody editing a lot of articles to have to pass a CAPTHCA every time they edit an article. Ed Baker of the International Commission on Zoological Nomenclature (ICZN) has a project to identify all the articles in the Bulletin of Zoological Nomenclature, and has been gently bugging me to add a login feature to BioStor. I played for a while with OpenID, but it occurred to me that Mendeley might be a more sensible strategy. Mendeley's API supports OAuth, a protocol where you can grant an application access to another application, but without giving away any passwords. It's used by Twitter and Facebook, among others. Indeed, a growing number of sites on the web are using Twitter and/or Facebook services to enable users to log in, rather than write their own code to support login, usernames, passwords, etc.

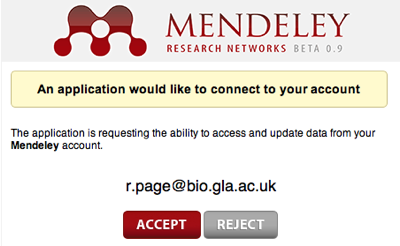
In the case of BioStor, I've added a link to sign in via Mendeley. if you click on it you get taken to a page like this:

connect.png
If you're happy for BioStor to connect to Mendeley, you click on Accept and BioStor won't bug you to fill in a CAPTCHA. Once Mendeley's API matures it would be nice to add features such as the ability to add a reference in BioStor straight to your Mendeley library (this is doable now, but the Mendeley API looses some key metadata such as page numbers).

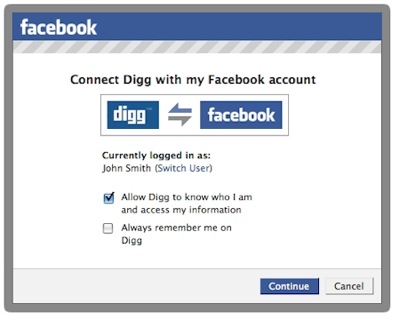
facebook-connect.jpg
But, thinking more broadly, Mendeley has an opportunity here to provide services similar to Facebook Connect. For example, instead of simply having buttons on web pages to bookmark papers, we could have buttons indicating how many people had added a paper to their library, and whether any of those people were in your contacts. We could extend this further an create something like Facebook's Open Graph Protocol, which supports the "Like" button. Or perhaps, we could have an app that integrates with Facebook and harvests your "Likes" that are papers.

Food for thought. Meantime, I hope users like Ed will find BioStor less tedious to use now that they can log in via Mendeley.

Wednesday, September 22, 2010

GeoCouch

@mikeal a little tedious. you can take OSM and then convert it to SHP and then http://github.com/maxogden/shp2geocouchless than a minute ago via web


The tweet above inspired me to take a quick look at GeoCouch, a version of CouchDB that supports spatial queries. This is something I need if I'm going to start playing seriously with CouchDB. So, it was off to Installing and working with GeoCouch, grabbing a copy of HomeBrew (yet another package manager for Mac OS X), in the hope of installing GeoCouch. Things went fairly smoothly, although it took what seemed like an age to build everything. But I now have GeoCouch running. Previously I'd been running CouchDB using http://janl.github.com/couchdbx/, which launches vanilla CouchDB. However, if you launch CouchDBX after starting GeoCouch from the command line, CouchDBX is talking to GeoCouch.

I then grabbed shp2geocouch to try some shape files (I grabbed some shape files from the IUCN to play with). If you're on a Mac grab GISLook to get Quick Look previews of these files. Since I'm new to ruby there were a couple of gotchas, such as lacking some prerequisites (httparty and couchrest, both installed by typing gem install <name of package>), and there was the small matter of needing to add ~/.gem/ruby/1.8/bin to my path so I could find shp2geocouch (spot the ruby neophyte). The shape file didn't get processed completely, but at least I managed to get some data into GeoCouch.

gis.png
So far I've been playing with the examples at http://github.com/vmx/couchdb, and things seem to work. At least, the basic bounding box queries work. I'm tempted to play with this some more (and get my head arounbd GeoJSON), perhaps trying to recreate the functionality of my Elsevier Challenge entry, for which I wrote a custom key-value database that was awfully clunky.

Finding scientific articles in a large digital archive: BioStor and the Biodiversity Heritage Library

npre20104928-1.thumb.pngYesterday I uploaded a manuscript to Nature Precedings that describes the inner workings of BioStor. The title is "Finding scientific articles in a large digital archive: BioStor and the Biodiversity Heritage Library", and you can grab it here: hdl:10101/npre.2010.4928.1.

Manuscripts describing databases are usually pretty turgid affairs, and this isn't an exception, despite my attempts to spice it up with the tale of Leviathan, oops, Livyatan (see doi:10.1038/nature09381 and Wikipedia). Plus, I can't escape the thought that BioStor would have been a lot more fun to write if I'd used a key-value database like CouchDB. I fear this is often the way of things. By the time it comes to writing something up, you realise that if you could start over you'd do it rather differently.

Monday, September 13, 2010

BHL and the iPad

@elyw I'd leave bookmarking to 3rd party, e.g. Mendeley. #bhlib specific issues incl. displaying DjVu files, and highlighting taxon namesless than a minute ago via Tweetie for Mac


Quick mock-up of a possible BHL iPad app (made using OmniGraffle), showing a paper from BioStor(http://biostor.org/reference/50335). Idea is to display a scanned page at a time, with taxonomic names on page being clickable (for example, user might get a list of other BHL content for this name). To enable quick navigation all the pages in the document being viewed are displayed in a scrollable gallery below main page.

bhlipad.jpg

Key to making this happen is being able to display DjVu files in a sensible way, maybe building on DjVu XML to HTML. Because BHL content is scanned, it makes sense to treat content as pages. We could extract OCR text and display that as a continuous block of text, but the OCR is sometimes pretty poor, and we'd also have to parse the text and interpret its structure (e.g., this is the title, these are section headings, etc.), and that's going to be hard work.

Friday, September 10, 2010

Touching citations on the iPad

Quick demo of the mockup I alluded to in the previous post. Here's a screen shot of the article "PhyloExplorer: a web server to validate, explore and query phylogenetic trees" (doi:10.1186/1471-2148-9-108) as displayed as a web-app on the iPad. You can view this at http://iphylo.org/~rpage/ipad/touch/ (you don't need an iPad, although it does work rather better on one).

touch.png
I've taken the XML for the article, and redisplayed it as HTML, with (most) of the citations highlighted in blue. If you touch one (or click on it if you're using a desktop browser) then you'll see a popover with some basic bibliographic details. For some papers which are Open Access I've extracted thumbnails of the figures, such as for "PhyloFinder: an intelligent search engine for phylogenetic tree databases" (doi:10.1186/1471-2148-8-90), shown above (and in more detail below):

popover.png
The idea is to give the reader a sense of what the paper is about, beyond can be gleaned from just the title and authors. The idea was inspired by the Biotext search engine from Marti Hearst's group, as well as Elsevier's "graphical abstract" noted by Alex Wild (@Myrmecos).

Here's a quick screencast showing it "live":


The next step is to enable the reader to then go and read this paper within the iPad web-app (doh!), which is fairly trivial to do, but it's Friday and I'm already late...

CouchDB, Mendeley, and what I really want in an iPad article viewer

Playing with @couchdb, starting to think of the Mendeley API as a read/write JSON store, and having a reader app built on that...less than a minute ago via Tweetie for Mac


It's slowly dawning on me that many of the ingredients for an alternative different way to browse scientific articles may already be in place. After my first crude efforts at what an iPad reader might look like I've started afresh with a new attempt, based on the Sencha Touch framework. The goal here isn't to make a polished app, but rather to get a sense of what could be done.

The first goal is to be able to browse the literature as if it was a connected series of documents (which is what, of course, it is). This requires taking the full text of an article, extracting the citations, and making them links to further documents (also with their citations extracted, and so on). Leaving aside the obvious problem that this approach is limited to open access articles, an app that does this is going to have to store a lot of bibliographic data as the reader browses the literature (otherwise we going to have to do all the processing on the fly, and that's not going to be fast enough). So, we need some storage.

MySQL
One option is to write a MySQL database to hold articles, books, etc. Doable (I've done more of these than I care to remember), but things get messy pretty quickly, especially as you add functionality (tags, fulltext, figures, etc.).

RDF
Another option is to use RDF and a tripe store. I've played with linked data quite a bit lately (see previous "Friday follies" here and here), and I thought that a triple store would be a great way support an article browser (especially as we add additional kinds of data, such as sequences, specimens, phylogenies, etc.). But linked data is a mess. For the things I care about there are either no canonical identifiers, or too many, and rarely does the primary data provider served linked data compliant URLs (e.g., NCBI), hence we end up with a plethora of wrappers around these sources. Then there's the issue of what vocabularies to use (once again, there are either none, or too many). As a query language SPARQL isn't great, and don't even get me started on the issue of editing data. OK, so I get the whole idea of linked data, it's just that the overhead of getting anything done seems too high. You've got to get a lot of ducks to line up.

CounchDBlogo.png
So, I started playing with CounchDB, in a fairly idle way. I'd had a look before, but didn't really get my head around the very different way of querying a database that CouchDB requires. Despite this learning curve, CouchDB has some great features. It stores documents in JSON, which makes it trivial to add data as objects (instead of mucking around with breaking them up into tables for SQL, or atomising them into triples for RDF), it supports versioning right out of the box (vital because metadata is often wrong and needs to be tidied up), and you talk to it using HTTP, which means no middleware to get in the way. You just point your browser (or curl, or whatever HTTP tool you have) and send GET, POST, PUT, or DELETE commands. And now it's in the cloud.

In some ways ending up with CouchDB (or something similar) seems inevitable. The one "semantic web" tool that I've made most use of is Semantic MediaWiki, which powers the NCBI to Wikipedia mapping I created in June. Semantic Mediawiki has it's uses, but occasionally it has driven me to distraction. But, when you get down to it, Semantic Mediawiki is really just a versioned document store (where the documents are typically key-value pairs), over which have been laid a pretty limited query language and some RDF export features. Put like this, most of the huge Mediawiki engine underlying Semantic MediaWiki isn't needed, so why not cut to the chase and use a purpose-built versioned document store? Enter CouchDB.

Browsing and Mendeley
So, what I have in mind is a browser that crawls a document, extracting citations, and enabling the reader to explore those. Eventually it will also extract all the other chocolatey goodness in an article (sequences, specimens, taxonomic names, etc.), but for now I'm focussing on articles and citations. A browser would need to store article metadata (say, each time it encounters an article for the first time), as well as update existing metadata (by adding missing DOIs, PubMed ids, citations, etc.), so what easier way than as JSON in a document store such as CouchDB? This is what I'm exploring at the moment, but let's take a step back for a second.

The Mendeley API, as poorly developed as it is, could be treated as essentially a wrapper around a JSON document store (the API stores and returns JSON), and speaks HTTP. So, we could imagine a browser that crawls the Mendeley database, adding papers that aren't in Mendeley as it goes. The act of browsing and reading would actively contribute to the database. Of course, we could spin this around, and argue that a crawler + CouchDB could pretty effectively create a clone of Mendeley's database (albeit without the social networking features that come with have a large user community).

This is another reason why the current crop of iPad article viewers, Mendeley's included, are so disappointing. There's the potential to completely change the way we interact with the scientific literature (instead of passively consuming PDFs), and Mendeley is ideally positioned to support this. Yes, I realise that for the vast majority of people being able to manage their PDFs and format bibliographies in MS Word are the killer features, but, seriously, is that all we aspire too?

Friday, September 03, 2010

Viewing scientific articles on the iPad: browsing articles

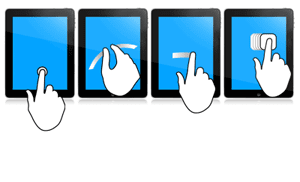
touchevents.pngIn previous articles I've looked at how various apps display scientific articles. The apps I looked at were:

So, where next? As Ian Mulvany noted in a comment on an earlier post, I haven't attempted to summarise the best user interface metaphors for navigation. Rather than try and do that in the abstract, I'd like to create some prototypes to play with various ideas. The Sencha Touch framework looks a good place to start. It's web-based, so things can be prototyped rapidly (I'm not going to learn Objective C anytime soon). There's a moderately steep learning curve, unless you've written a lot of Javascript (I've done some, but not a lot), but it seems to offer a lot of functionality. Another advantage of developing a web app is that it keeps the focus on making the content accessible across devices, and using the web as the means to display and interact with content.

Then there is also the issue (in addition to displaying an individual article) of how to browse and find articles to view. Here are some possibilities.

Publisher's stream
Apps such as the Nature app and the PLos Reader provide you with a stream of articles from a single publisher. This is obviously a bit limiting for the reader, but might have some advantages if the publisher has specifically enhanced their content for devices such as the iPad.

Personal library
Apps such as Mendeley and Papers provide articles from your personal library. These are papers you care about, and one you may make active use of.

Social
Social readers such as Flipboard show the power of bringing together in one place content derived from social streams, such as Twitter and Facebook, as well as curated sources and publisher streams. Mendeley and other social bookmarking services (e.g., CiteULike, Connotea) could be used to provide social similar streams of papers for an article viewer. Here the goal is probably to find out what papers people you know find interesting.

Spatialipadmap.png
In an earlier post I used a map to explore papers in my BioStor archive. This would be an obvious thing to add to an iPad app, especially as the iPad knows where you are. Hence, you could imagine browsing papers about areas that are near you, or perhaps by authors near you. This would be useful if, say, you wanted to know about ecological or health studies of the area you live in. If the geographic search was for people rather than papers, you could easily discovering what kind of research is published by universities or other research bodies that are near your current location.

Of course, Earth is not the only thing we can explore spatially. Google maps can display other bodies in the solar system, (e.g., Mars), as well as the night sky. Imagine being interested in astronomy and being able to browse papers about specific planetary or stellar objects. Likewise, genomes can be browsed using Google maps-inspired browsers (e.g., jBrowse), so we could have an app where you could easily retrieve articles about a particular gene or other region of a genome.

Categories
Another way to browse content is by topic. Classifying knowledge into categories is somewhat fraught, but there are some obvious wasy this could be useful. A biologist might want to navigate content by taxonomic group, particularly if they want to browse through the 1000's of articles published in a journal such as Zootaxa (hence my experiments on browsing EOL). Of course, a tree is not the only way to navigate hierarchical content. Treemaps are another example, and I've played with various versions in the past (see here and here).

qt.png

I have a love-hate relationship with treemaps, but some of the most interesting work I've seen on treemaps has been motivated by displaying information on small screens, e.g. "Using treemaps to visualize threaded discussion forums on PDAs" (doi:10.1145/1056808.1056915).

Summary
These notes list some of the more obvious ways to browse a collection of articles. It would be fun to explore these (and other approaches) in parallel with thinking about how to display the actual articles. These two issues are related, in the sense that the more metadata we can extract from the articles (such as keywords, taxonomic names and other named entities, geographic localities, etc.) the richer the possibilities for finding our way through those articles.

Tuesday, August 31, 2010

ReaderMeter: what's in a name?

Screen_shot_2010-08-30_at_22.37.31.pngDario Taraborelli has released ReaderMeter, an elegant app built on top of the Mendeley API. You enter an author's name and it summarises that authorship's readership in Mendeley. The app provides some summary statistics (mine are shown below), and if you click on the horizontal bar corresponding to a paper, you can see a visualisation of who is reading your paper, including a nice map.

meter.png

As ever with author names, there are issues of people's name having more than one spelling. In Mendeley I'm known as Roderic D. M. Page, R. D. M. Page, Rod Page, Roderic Page, Roderic D. M. Page, and doubtless some others. Searching ReaderMeter using different spellings of my name gives different results. There are various approaches to tackling this problem, I've touched on one approach earlier.

However, there's a different way to tackle this problem in the context of apps like ReaderMeter, because if you're a Mendeley user you can assert that you are the author of a paper (these papers live in your "My Publications" collection). Using Mendeley's API, an app could retrieve this list of publications (providing the user gave it access), and we could compute readership statistics from the set of articles "known" to be authored (leaving aside the issue of people gaming the system by spuriously claiming authorship). In this way the app relies on the default behaviour of Mendeley users - uploading and self-identifying the articles they've written.

Implementing a feature like this posses two problems. The first is access to a user's data. Mendeley's API supports OAuth, so it could be done in such a way that only the account's user could authorise the app to access this list. The app could store the fact that the user has verified that the list of publications. Think of it as a bit like Amazon's Real Name™ feature.

The other obstacle is Mendeley's API, which returns readership statistics for public documents (i.e., those in the central aggregation). At present, using the API there is no way to link the global id for a Mendeley reference (e.g., ae7dd6a0-6d09-11df-936c-0026b95e484c) with the local id (e.g., 3582682802) that reference has in a user's collection, unless we resort to trying to match articles by searching by identifiers or article titles. If the API exposed these links, apps like ReaderMeter could become even more powerful (and personalised).

Viewing scientific articles on the iPad: iBooks

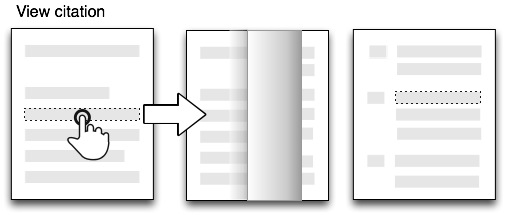
Apple's iBooks app is an ePub and PDF reader, and one could write a lengthy article about its interface. However, in the context of these posts on visualising the scientific article there's one feature that has particularly struck me. When reading a book that cited other literature the citations are hyper-links: click on one and iBooks forwards you (via the page turning effect) to the reference in the book's bibliography. This can be a little jarring (one minute you're reading the page, next you're in the bibliography), but to help maintain context the reference is preceded by the snippet of text in which it is cited:

touch7.jpg

To make this concrete, here's an example from Clarky Shirky's "Cognitive Surplus."

ibooks.jpg

In the body of the text (left) the text "notes in his book The Success of Open Source" (which I've highlighted in blue) is a hyper-link. Click on it, and we see the source of the citation (right), together with the text that formed the hyper-link. This context helps remind you why you wanted to follow up the citation, and also provides the way back to the text: click on the context snippet and you're taken back to the original page.

Providing context for a citation is a nice feature, and there are various ways to do this. For example, the Elsevier Life Sciences Challenge entry by Wan et al. ("Supporting browsing-specific information needs: Introducing the Citation-Sensitive In-Browser Summariser", doi:10.1016/j.websem.2010.03.002, see also an earlier version on CiteSeer) takes a different approach. Rather than provide local context for a citation in an article (a la iBooks), Wan et al. provide context-sensitive summaries of the reference cited to help the the reader judge whether it's worth her time to fetch the reference and read it.

Both of these approaches suggest that we could be a lot more creative about how we display and interact with citations when viewing an article.

Viewing scientific articles on the iPad: Mendeley

Previously I've looked at the Nature, PLoS, and Papers apps, now it's the turn of the Mendeley iPad app. As before, this isn't a review of the app as such, I'm more interested in documenting how the app interface works, with a view to discovering if there are consistent metaphors we can use for navigating bibliographic databases.

Perhaps the key difference between Mendeley and the other apps is that Mendeley is cloud-based, in that the bibliography exists on Mendeley's servers, as well as locally on your desktop, iPad, or iPhone. Hence, whereas the Nature and PLoS apps consume a web stream of documents, and Papers enables you to sync collections between desktop and iOS devices, Mendeley syncs to central web server. At present this appears to be done over HTTPS. Mendeley recently released an API, which I've discussed at length. Mendeley's app doesn't use this API, which is a pity because if it did I suspect the API would be getting the love it needs from Mendeley's developers.

Like Papers, the Mendley app uses a split view, where the left-hand panel is used for navigation.

mendeley.png

You can drill down to lists of references, and display basic details about an article.

PDF
The Mendeley app is a PDF viewer, but whereas the PLoS app has page turning, and the Papers app scrolls pages from left to right, the Mendeley app displays PDF pages vertically (which is probably the more natural way to scroll through content on the iPad):

touch6.jpg

Summary
It's clearly early days for the Mendeley app, but it's worth noting two of its most obvious limitations. Firstly, it depends entirely on the user's existing Mendeley bibliography - you can't add to this using the app, it's simply a viewer. Compare this to Papers which can access a suite of search engines from which you can download new papers (albeit with some limitations, for example the Papers iPad app doesn't seem to support extracting metadata via XMP, unlike the desktop version). Secondly, despite Mendeley having as one of its goals being a
research network that allows you to keep track of your colleagues' publications, conference participations, awards etc., and helps you discover people with research interests similar to yours

the Mendeley app lacks any social features, apart from sharing by email(!). I think designing social interactions in bibliographic apps will be a challenge. For an example of what social reading can look like, check out Flipboard.

Viewing scientific articles on the iPad: Papers

ipad_iphone.gifContinuing the series of posts about reading scientific articles on the iPad, here are some quick notes on perhaps the most polished app I've seen, Papers for iPad. As with earlier posts on the Nature and PLoS apps, I'm not writing an in-depth review - rather I'm interested in the basic interface design.

Papers is available for the Mac, as well as the iPhone and iPad. Unlike social bibliographic apps such as Zotero and Mendeley, Papers lacks a web client. Instead, all your PDFs are held on your Mac, which can be wirelessly synced with Papers on the iPad or iPhone.

Navigation popover

Papers makes extensive of use of the split view, in which the screen is split into two panes, the left-hand split becoming a popover when you hold the iPad in porrtait orientation. Almost all of the functionality of the iPhone version is crammed into the left-hand split. The popover displays the main interface categories (library, help, collections that you've put PDFs into), collections of documents, metadata for individual papers (which you can edit), as well as search results from a wide range of databases:

papers.jpg

Some of these features you encounter as you drill down, say from library to list of papers, to details about a document, others you can access by clicking on the tab bar at the bottom.

PDF display
Like the PLoS app, Papers displays PDFs. It doesn't use a page-turning effect, rather you swipe through the pages from left to right, with the current page indicated below in a page control (what Sencha Touch describe as a carousel control).

touch5.jpg

Given that the document being displayed is a PDF there is no interaction with the images or citations, but you can add highlights and annotations.

Summary
Papers is the first of the iPad apps I've discussed that isn't limited to a single publisher. If and article is online, or in your copy of Papers for the Mac, then you can view it in Papers for iPad. It is the app that I use on a day to day basis, although the PDF viewer can feel a little clunky. I think anyone designing an application reader should play with Papers for a while, if only to see the level of functionality that can be embedded in the basic iPad split view.

Saturday, August 28, 2010

On being open: Mendeley and open data versus open source

Paulo Nuin, not the biggest fan of Mendeley wrote a blog post entitled Mendeley is going to be open source, in which he wrote:

After extensively researching some material online, analysing many blog posts and statements made by people linked to Mendeley, checking my sources, I reached the conclusion that soon Mendeley is going to be open source.

Among the essays Paulo read is Jason Hoyt's post on the Mendeley blog: Dear researcher, which side of history will you be on?. In response to a question about open sourcing the Mendeley client, Jason replied:
I get asked a lot about open sourcing Mendeley when I go to speaking events. I always state that we are open to the possibility, but then ask how many people know how to type a URL verus how many know how to program in C++? That’s why we went with the Open API first instead of open sourcing the desktop software. If you can type a URL, which is what the API is based upon, then you can build on top of Mendeley. You don’t need to know how to program.

Despite the fact that open sourcing the desktop client is the second most requested feature for Mendeley, I think Jason is right. I also think Paulo's campaign to make Mendeley open source is misguided. The client doesn't matter. OK, yes, it's probably the reason most people use Mendeley, but there are lots of competing clients (EndNote, Zotero, Papers, etc.), and there are several bibliographic data formats (RIS, EndNote XML, BibTeX) and essentially one document format (PDF) that they support, so individual users don't have to worry about locking their individual bibliographies into a proprietary format. Couple this with the existence of an API (albeit a pretty crap one), and whether an individual software client is closed or open source doesn't matter much.

Will the data be open?

However, what makes Mendeley different is the aggregation of bibliographic data (35 million references and counting).

privacy_1264073462.jpg


I'd argue it's the fate of this aggregation that matters. In a comment on the Guardian's piece Mendeley 'most likely to change the world for the better', Jane Good wrote:
"World-changing potential"? This utopian fantasy stuff is a little much, no? After all, we're talking about a for-profit corporation using closed-source software to monitor private usage habits for monetary gain. And how exactly is this company meant to sustain its millions of dollars of annual burn on a few measly storage subscriptions? At some point the data will have to go up for sale to the highest bidder, plain and simple. The API, as it exists now, does not provide access to that data, and it probably never will, right, DrGinn[sic]?

Toning down the rhetoric, the question is Mendeley, Scopus, Talis – will you be making your data Open?:

But how can a company create an income stream from Open Scientific content? That’s the a question for me for this decade. If we can solve it we can transform the world. If however the linked Open data are all going to be through paywalls, portals, query engines then we regress into the feudal information possession of the past. I hope the companies present in this session can help solve this. It won’t be easy but it has to be done. So I now ask Mendeley, Elsevier/Scopus, Talis: Are your data Openly available for re-use?

For me the question of whether the source code for the Mendeley desktop will be made open source is a red herring, and ultimately a distraction from the real question — will the data be open?

Friday, August 27, 2010

Navigating the Encyclopedia of Life tree on the desktop and the iPhone

This week seems to be API week. The Encyclopedia of Life API Beta Test has been out since August 12th. By comparison with the Mendeley API that I've spent rather too much time trying to get to grips with, the EOL API release seems rather understated.

However, I've spent the last couple of days playing with it in order to build a simple tree navigating widget, which you can view at http://iphylo.org/~rpage/eoltree/.

The widget resembles Aaron Thompson's Taxonomy (formerly called KPCOFGS) iPhone app in that it uses the iPhone table view to list all the taxa at a given level in a taxonomic tree. Clicking on a row in this table takes you to the descendants of the corresponding taxon, clicking "Back" takes you back up the tree. if you've reached a leave node (typically a species) the widget displays a snippet of information about that taxon. It also resembles Javier de la Torre's taxonomic browser written in Flex.

Here's a screen shot of the widget running in a desktop web browser:

insecta.png

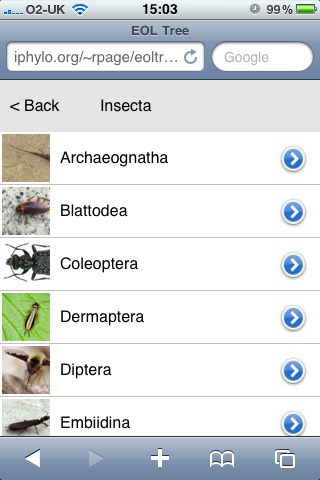
Here's the same widget in the iPhone web browser:

web.pngUsing the API
The EOL API is pretty straightforward. I call the http://www.eol.org/api/docs/hierarchy_entries API to get the tree rooted at a given node, then populate each child of that node using http://www.eol.org/api/docs/pages. The result is a simple JSON file that I cache locally to speed up performance and avoid hitting the EOL servers for the same information. because I'm locally caching the API calls I need a couple of PHP scripts to do this, but everything else is HTML and Javascript.

iPhone and iPad
I've not really developed this for the iPhone. I've cobbled together some crude Javascript to simulate some iPhone-like effects, but if I was serious about the phone I'd look into one of the Javascript kits available for iPhone development. However, I did want something that was similar in size to the iPhone screen. The reason is I'm looking at adding taxonomic browsing to the geographic browser I described in the post Browsing a digital library using a map, so I wanted something easy to use but which didn't take up too much space. In the same way that the Pygmybrowse tree viewer I played with in 2006 was a solution to viewing a tree on a small screen, I think developing for the iPhone forces you to strip things down to the bare essentials.

I'm also keeping the iPad in mind. In portrait mode some apps display lists in a popover like this:

popover_flatten.png

This popover takes up a similar amount of screen space to the entire iPhone screen, so if I was to have a web app (or native app) that had taxonomic navigation, I'd want it to be about the size of the iPhone.

Let me know what you think. Meantime I need to think about bolting this onto the map browser, and providing a combined taxonomic and geographic perspective on a set of documents,

Thursday, August 26, 2010

Mendeley API PHP client

mendeley.pngFollowing on from my earlier post about the Mendeley API, I've bundled up my code for OAuth access to the Mendeley API for anyone who's interested in playing with the API using PHP. You can browse the code on Google Code, or grab a tarball here. You'll need a consumer key and a consumer secret from Mendeley for the demos to work, and if you're behind a HTTP proxy you'll have to tweak the code (this is explained in the ReadMe.txt file that comes with the code).

The code is pretty rough, and doesn't use all the Mendeley API calls, but I've other things to do, and it felt like a case of either bundle this up now, or it will get lost among a host of other projects. The Mendeley API still feels woefully under-developed. I'd be more interested in developing this client further if the API was powerful enough to do the kinds of things I'd like to do.