Friday, January 29, 2010

Why I want an iPad

best_experience_20100127.png
OK, first of all, I want one, I want one real bad.

There's been a general sense of disappointment about the iPad, which I suspect is only natural given the enormous hype leading up to the announcement, as well as the fact that the applications shown were fairly conventional. Personally I don't think book reading is where the action is. For time-sensitive stuff like newspapers, and rich, complex documents such as scientific papers, sure, but physical books strike me as a piece of technology that we're not really going to improve on, rather like knives and forks.

But some grasp that this is magic. What I hope the iPad will do is finally move some visualisation tools into the main stream (as much as phylogenetics can be thought of as mainstream). The challenge of visualising large phylogenies has yielded some cool tools which, sadly, remained under-developed, such as TreeJuxtaposer, which seems clunky and counter-intuituve when using a mouse, but with a touch screen would just be awesome.


Tools such as Paloverde would also be more intuitive to use, as would the magnifier feature in Dendroscope. Imagine "pinch and zoom" in TreeJuxtaposer or Dendroscope, or for viewing large a sequence alignments.

Then there's the existing tabletop tools that I blogged about earlier:


And of course there's Perceptive Pixel's view of a taxonomic classification:


There would be some work involved porting these tools to the iPad (e.g., porting code from Java to Objective C in the case of TreeJuxtaposer and Dendroscope), but the person who does this is going to have an impact on this field comparable to Maddison brothers when they released MacClade in 1986.

Monday, January 25, 2010

Displaying taxonomic coverage using a treemap

A quick, and not altogether satisfactory hack, but I've added a simple interactive treemap to BioStor. It's essentially a remake of the Catalogue of Life treemap I created in 2008, but coloured by the number of references I've extracted from BHL. I wanted a quick way to visualise which groups were well represented (darker colours), and which weren't (lighter colours). For example, in the diagram below we can see that Annelida, Arthropoda, Chordata, Cnidaria, and Mollusca have most of the references.
tm.png

The treemap at BioStor is interactive. You can click on a panel in the treemap to drill down. To go back up, click on the desired level in the tree displayed to the left of the treemap.

Friday, January 15, 2010

Why BHL needs automation and/or crowd sourcing

Jim Croft drew my attention to a cool crowd-sourcing project to convert scans of Australia's newspapers to text. The site has a nice chart showing the projects' coverage of the Australian newspapers, which motivated me to show something similar for BioStor. Each journal page now shows a chart of article coverage.

For example, the journal Breviora has most of its articles identified, mainly because the MCZ put a list of articles linked to BHL on their website. I harvested this to populate BioStor.

breviora-coverage.png


Other journals are looking a bit more sparse, such as the Bulletin of the British Museum (Natural History) (Entomology):

bmnhe.png


So, there's a lot to do, and a crying need for some combination of automation (whether driven by external metadata, which is my current approach, or trying to extract article information directly from the OCR text) and crowd sourcing if we're going to be able to make a significant dent in the task of finding articles in BHL.

Wednesday, January 13, 2010

BioStor so far

My BioStor project has reached over 13,000 articles, making it a sizeable respository of open access articles on biodiversity. It's still a tiny fraction of what could be extracted from the Biodiversity Heritage Library (BHL), but perhaps it's worth taking stock of what's there.

Coverage

One pleasing discovery is that, despite the 1923 cut-off due to U.S. copyright, BHL contains a lot of post-1923 articles. Indeed, a sparkline of the number of articles over time shows that the bulk of the articles I've extracted from BHL are from the second half of the twentieth Century. These include journals such as Entomological News, and major herbaria and museum publications, such as Annals of the Missouri Botanical Garden, Breviora, Bulletin of the British Museum (Natural History). Zoology, and Proceedings of the United States National Museum.


This distribution partly reflects my own biased harvesting of BHL, but perhaps it also reflects a transition in publishing (from books and monographs to journals).

Exhibit

The interface to BioStor is still pretty rough, but one thing I've had fun adding is the SIMILE Exhibit widget to the author pages. Exhibit enables faceted browsing, so you can filter an author's list of publications by the journal they published, what year the article was published, and who was a coauthor.

author.png


One use I've found is that you can quickly filter out purely nomenclatural papers by select an author's publications in the Bulletin of Zoological Nomenclature.

Sparklines

I'm a fan of sparklines, and I'm a starting to add some to various pages. For example, you can now see a graph of how many papers an author has published over time, the example below is for the prolific Charles P Alexander:


Search

This pretty much sums up search in BioStor at the moment:


Harvesting

The rate of growth of BioStor has been pretty steady, partly because I keep managing to find (or are alerted to, or are given) sources of bibliographic metadata. I'm also adding individual papers as I come across them, either using the Reference finder form directly, or by using OpenURL from within Endnote. But there's still a crying need for large bibliographies that can be harvested.

Export

Individual references can be exported in a range of formats, and there is a RSS feed, but I need to add bulk export (including the ability to dump the whole database).

Viewer

The viewer I developed earlier is working reasonably well, but could do with sprucing up. I'm also toying with using other viewers as well as (or instead of) mine. One possibility is iPaper (although this is Flash-based, and I'd like to avoid Flash wherever possible).

Taxonomic names

One thing I've discovered to my horror is just how common it is for the BHL taxon finder to miss obvious taxonomic names. I need to investigate this a bit more, but this is potentially a major issue as taxonomic indexing is one of the primary ways people will find content in BioStor

Future

There's still so much to do. For one thing, the visualisations that originally got me seriously thinking about playing with BHL aren't in BioStor yet. And there's a long to-do list.

Monday, January 04, 2010

Thoughts on the International Year of Biodiversity 2010

IYB2010_Logo_English_sm.jpg
Given that a new decade prompts predictions, as well as New Year's resolutions, and that 2010 is the International Year of Biodiversity, which comes complete with glossy web sites and calls for action, I'm making some predictions of my own, inspired in part by Eric Hellman's Ten Predictions for the Next Ten Years. I won't be nearly as bold as Eric, I'm limiting myself to biodiversity informatics, and the coming year. Here are my predictions:


  1. The Encyclopedia of Life will continue it's slow decline into irrelevance. Nobody will care, as we have Wikipedia.

  2. Catalogue of Life (CoL) will issue another release, complete with much fanfare. The LSIDs for the 2009 release (which have never worked) will continue to fail, LSIDs for 2010 either won't be released, or will fail. Nobody will care.

  3. There will be much talk of integrating biodiversity data. Unless GBIF adopts resolvable identifiers for specimens, and a major nomenclator or taxonomic name database (re)uses resolvable identifiers for literature (e.g., DOIs and BHL URLs), nothing of significance in this area will happen. Database providers will continue to confuse "link integration" (i.e., sharing URLs, doi:10.1038/nrg1065) with genuine integration.

  4. For most young scientists GenBank will be the dominant source of information about biodiversity. If it hasn't been sequenced, they won't care about it.

  5. DNA barcoding by itself will become boring, but will be the best tool with which to engage the public about taxonomy (e.g., Barcoding, taxonomy and citizen CSI).

  6. Literature that is not online will cease to be read. Taxonomic groups where the literature is not online will effectively cease to be studied.

  7. The major databases will continue to be riddled with errors. These will be numerous enough to be annoying, but not so numerous as to prevent useful work being done. The databases will make no (serious) effort to fix these (doi:10.1126/science.319.5870.1598).

  8. No major database effort will adopt wikis.

  9. Data providers such as Thomson Reuters (Index of Organism Names) will continue to clutch to debilitating notions of "intellectual property." As the coverage of the Biodiversity Heritage Library, and the reach of Google's indexing increase, commercial indexing services will become irrelevant.

  10. The chasm between the classifications that underlie efforts such as EOL, and phylogenetic trees being generated by systematists will grow. Neither community will care.


What are your predictions?

Monday, December 21, 2009

BioStor

Today I finally got a project out the door. BioStor is my take on what an interface to theBiodiversity Heritage Library (BHL) could look like. It features the visualisations I've mentioned in earlier posts, such as Google maps based on extracted localities, and tag trees. It also has a modified version of my earlier BHL viewer.

There are a number of ideas I want to play with using BioStor, but the main goal this site is to provide article-level metadata for BHL. As I've discussed earlier (see also Chris Freeland's post But where are the articles?), BHL has very little article-level metadata, making searching for articles a frustrating experience. BioStor aims to make this easier by providing an OpenURL resolver that tries to find articles in BHL.

BioStor supports the OpenURL standard, which means it can be used from
within EndNote and Zotero. Web sites that support COinS (such as Drupal-based Scratchpads and EOL's LifeDesks) can also be uses BioStor (see http://biostor.org/referrer.php for details).

My approach to finding articles in BHL is to take existing metadata from bilbiographies and databases, and use this to search BHL using techniques ranging from reasonably elegant (Smith-Waterman alignment on words to match titles) to down-and-dirty regular expression matching. Since this metadata may contain errors, BioStor provides basic editing tools (using reCAPTCHA rather than user logins at this point).

There's much to be done, the article finding is somewhat error-prone, and the search requires a local copy of BHL, and mine is rather out of date. However, it is a start.

To get a flavour of BioStor, try browsing some references:

http://biostor.org/reference/1
http://biostor.org/reference/4
http://biostor.org/reference/12

or view information for a journal:

http://biostor.org/issn/0007-1498


or an author:

http://biostor.org/author/41
http://biostor.org/author/16

or a taxon name:

http://biostor.org/name/Atelophryniscus%20chrysophorus

Friday, December 11, 2009

BHL interface ideas

I've been buried in programming (and it's exam time at Glasgow) so I've not blogged for a month (gasp). I've been playing with ways to visualise Biodiversity Heritage Library content for a while (click here for a list of previous posts), and have occasionally surfaced to tweet a screenshot via twitpic. The more I play with the BHL content the more I think it's a gold mine, and that many of the ideas I played with for my ill-fated Elsevier Challenge entry (website here, background paper at hdl:10101/npre.2009.3173.1) are taking on a new life with this project.

I'm hoping to release my BHL article finding and visualising web site by the end of the month, but meantime I'm gathering the screenshots here.

The first shows a Google map generated from latitude and longitudes extracted from OCR text using some simple regular expressions from page 7705952 in the BHL.There's quite a bit of latitude and longitude information in BHL, and that's before trying georeferencing tools.

<46740423.png


The idea is to display this map next to the article so that user get's an immediate sense of what region in the world the article covers, such as this article about Riekia wasps:

46744940.png


I'm also interested in useful ways to display search results. Here's an experiment using TileBars to visualise how relevant a search result is. The width of the bar is a function of how many pages are in the article, the vertical stripes indicate pages that have the search term. The idea is to get a quick visual impression of whether the article mentions the term in parsing, or treats it in some detail.

48350737.png


TileBars were developed by Marti Hearst, whose web site has some great resources. Partly inspired by her BioText projec, as well as the thumbnail page display in JSTOR I'm now experimenting with showing thumbnails in search results. For example, here's a search for the deep sea octopus Graneledone pacifica, showing two articles:


48832222-196574b7b6d6a2bc5764a5e853cd478b.4b228b85-full.png


I display thumbnails for pages that (a) have the name on the page, and (b) have what look like figure captions on them. The idea is that an article that figures a taxon is likely to be a fairly important article to look at, so displaying thumbnails will highlight those articles. The second article in the search results is the paper that published the name Graneledone pacifica, and the figures illustrate the taxon.

These are all pretty rough, but they give some idea of what I've been working on the last month.


Wednesday, November 11, 2009

Tag trees: displaying the taxonomy of names in BHL

I've added a feature to my Biodiversity Heritage Library viewer that should help make sense of the names found on a page. Until now I've displayed them as a list of "tags", which ignores the relations among the names. Based on some code I'd developed for my e-Biosphere 09 challenge entry I've added a "tag tree" that displays the classification of the names found on a BHL page:

big.png

The idea is that a set of names can make much more sense if you know what kind of organism they are referring to. For example, I don't know what Onetes is, but if I look at BHL page 2298380 I can see that it's an insect:

Onetes.png

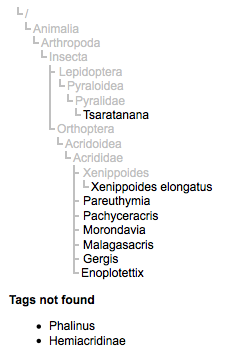
The names in gray don't occur on the page, but do occur in the tree that links those names (the latter are highlighed in black). The tag tree can be useful for separating out host and parasite, e.g. BHL page 2298491 is about a flea and it's mammalian hosts:

flea.png

The tag tree can also flag names that might be mistaken, such as those found on page 2298330:

mistake.png

This page has names of some grasshoppers from Madagascar, as well as the name of a butterfly (Tsaratanana), which seems a little odd. Looking at the text, we discover that "Tsaratanana" is Mont. Tsaratanana a mountain in Madagascar. It would be fun to develop tools to annotate such cases so that somebody looking for the butterfly won't be presented with this page.

How it works

The inspiration for this tag tree came from several sources. David Remsen has often used an example of finding a fly name in the middle of a book on birds as being of interest, and the NCBI have a subtree view of taxa in a PubMed article. My own tag tree is constructed by finding for each name the ancestor-descendant path in a local, modified copy of the Catalogue of Life database, then assembling those paths into a tree. Because not all the names on a BHL page are in the Catalogue of Life, there may be names that aren't classified. These are simply listed below the tag tree (see image above).

Monday, November 09, 2009

iTaxon screencast

Sadly I won't be at TDWG 2009, at least not in person. However, there is a session on wikis, which may contain this brief screencast of my iTaxon experiments. The screencast was made in haste, but tries to convey some of the ideas behind these experiments, especially the idea that by linking data together we can generate more interesting and rich views of objects such as scientific publications. The screencast starts with the The amphibian tree of life page.


Thursday, November 05, 2009

BHL Viewer now with go faster stripes

One of the more glaring limitations of my BHL viewer described in the previous post is that it can take a while to load all the page thumbnails (there can be hundreds). Given that one of the original motivations for this project was a faster viewer, this kinda sucks. What I'd like to do is load the thumbnails only when I need them, rather than all at once at the start -- in other words I'd like to implement lazy loading.

I'm using the Prototype Javascript library, and to my delight Bram Van Damme has written lazierLoad, inspired by Lazy Load for JQuery. lazierLoad works by attaching a listener to each image that listens for scroll events -- when the browser window scrolls each image receives a notification event and works out whether it needs to load the image. In theory, all you do is add the lazierLoad Javascript to your page, and only images that are currently visible will be fetched from the server. I say "in theory" because I needed to tweak the script a little because the thumbnails are inside a DIV element that has it's own scrollbar (thanks to the CSS style overflow:auto). Hence I needed to add the listener to this DIV, and compute coordinates for the image taking the DIV into account. Like most things, easy once you know how (translation, after numerous failed attempts, and the occasional "doh!" it seems to work).

You can see lazy loading in action if you view a BHL item, such as Item 26140. Note that this implementation of lazy loading doesn't work in Safari, much to my chagrin (it's my default browser). It works fine in Firefox

Tuesday, November 03, 2009

Biodiversity Heritage Library viewer experiments

In between the chaos that is term-time I've been playing with ways to view Biodiversity Heritage Library content. The viewer is crude, and likely to go off-line at any moment while I fuss with it, the you can view an example here. This link takes you to a display of BHL item 19513, which is volume 12 of the Bulletin of the British Museum (Natural History) Entomology, which includes some striking insects, such as the species of Lopheuthymia displayed below:

bhlviewer.png


The viewer attempts to do several things:
  1. Display a BHL document in a way that I can quickly scan pages looking for article boundaries by showing thumbnails
  2. Provide a simple way for me to edit metadata (if you find the start of an article you can click on the is the first page in an article and edit the article details)
  3. Provide a RIS dump of the articles which can then be uploaded into other bibliographic tools

Note that on the left hand side I'm displaying the articles that have already been found in the volume. The editing interface is crude, and I'll need to look at user authentication and versioning to do this seriously, but it seems a quick way to annotate BHL content. Much of this needs only be done once, as once we have article boundaries then searching BHL journal content using, say, OpenURL becomes easy, and we can link bibliographic records in nomenclators to BHL. Improving the metadata will also improve visualisation such as my BHL timeline.

I hope to play a bit more with the view over the next days and weeks. It's pretty simple (Javascript with PHP back end). The key to creating the viewer was a complete dump of BHL's page metadata kindly provided by Mike Lichtenberg. I use this to locate individual page images stored by the Internet Archive, which I then store locally (and generate 100 pixel wide thumbnails).

Potentially there's a lot more one could add to a tool like this. I'm playing with displaying the taxon names found by uBio so that I can flag instances where the page is where the name is first published. One could imagine adding other flags, such as when a taxon is depicted so that we could easily extract images of taxa from BHL content. It would also be nice to be able to add taxon names that uBio's algorithms have missed. Utlimately, one could even display the OCR text and correct/annotate that. Much to do...

Friday, October 23, 2009

n-gram fulltext indexing in MySQL

Continuing with my exploration of the Biodiversity Heritage Library one obstacle to linking BHL content with nomenclature databases is the lack of a consistent way to refer to the same bibliographic item (e.g., book or journal). For example, the Amphibia Species of the World (ASW) page for Gastrotheca aureomaculata gives the first reference for this name as:

Gastrotheca aureomaculata Cochran and Goin, 1970, Bull. U.S. Natl. Mus., 288: 177. Holotype: FMNH 69701, by original designation. Type locality: "in [Departamento] Huila, Colombia, at San Antonio, a small village 25 kilometers west of San Agustín, at 2,300 meters".


The journal that ASW abbreviates as "Bull. U.S. Natl. Mus." is in the BHL, which gives its title as "Bulletin - United States National Museum.". How do I link these two records? In my bioGUID OpenURL project I've been doing things like using SQL LIKE statements with periods (.) replaced by wildcards ('%') to find journal titles that match abbreviations (as well as building a database of these abbreviations). But this is error prone, and won't work for abbreviations such as "Bull. U.S. Natl. Mus." because the word "National" has been abbreviated to "Natl", which isn't a substring of "National".

After exploring various methods (including longest common subsequences, and sequence alignment algorithms) I came across a MySQL plugin for n-grams. The plugin tokenises strings into bi-grams (tokens with just two characters, see the Wikipedia page on N-grams for more information). This means that even though as words "National" and "Natl" are different, they will have some similarity due to the shared bi-grams "Na" and "at".

So, I grabbed the source for the plugin and the ICU dependency, compiled the plugin and added it to MySQL (I'm running MySQL 5.1.34 on Mac OS X 10.5.8). The plugin can be added while the MySQL server is running using this SQL command:

INSTALL PLUGIN bigram SONAME 'libftbigram.so';

Initial experiments seem promising. For the bhl_title table I created a bi-gram index:

ALTER TABLE `bhl_title` ADD FULLTEXT (`ShortTitle`) WITH PARSER bigram;

If I then take the abbreviation "Bull. U.S. Natl. Mus.", strip out the punctuation, and search for the resulting string ("Bull US Natl Mus")

SELECT TitleID, ShortTitle, MATCH(ShortTitle) AGAINST('Bull U S Natl Museum')
AS score FROM bhl_title
WHERE MATCH(ShortTitle) AGAINST('Bull U S Natl Museum') LIMIT 5;

I get this:
TitleIDShortTitle score
7548Bulletin - United States National Museum. 19.4019603729248
13855Bulletin du Muséum National d'Histoire Naturelle. 17.6493873596191
14964Bulletin du Muséum National d'Histoire Naturelle. 17.6493873596191
5943Bulletin du Muséum national d'histoire naturelle. 17.6493873596191
12908Bulletin du Muséum National d'Histoire Naturelle. 17.6493873596191


The journal we want is the top hit (if only just). I'll probably have to do some post-processing to check that the top hit makes sense (e.g., is it a supersequence of the search term?) but this looks like a promising way to match abbreviated journal names and book titles to records in BHL (and other databases).


Saturday, October 17, 2009

Memcached, Mac OS X, and PHP

Thinking about ways to improve the performance of some of my web servers I've begun to toy with Memcached. These notes are to remind me how to set it up (I'm using Mac OS X 10.5, Apache 2 and PHP 5.2.10, as provided by Apple). Erik's blog post Memcached with PHP on Mac OS X has a step-by-step guide, based on the post Setup a Memcached-Enabled MAMP Sandbox Environment by Nate Haug, and I've basically followed the steps they outline.
  1. Install the Memcached service on Mac OS X: Follow the instructions in Nate Haug's post.

  2. Install Memcache PHP Extension: Apple's PHP doesn't come with the PECL package for memcache so download it. To compile it go:

    phpize
    ./configure
    make
    sudo make install

    One important point. If you are running 64-bit Mac OS X (as I am), ./configure by itself won't build a usable extension. However, a comment by Matt on Erik's original post provides the solution. Instead of just ./configure, type this at the command prompt:

    MACOSX_DEPLOYMENT_TARGET=10.5 CFLAGS="-arch ppc -arch ppc64 -arch i386 -arch x86_64 -g -Os -pipe -no-cpp-precomp" CCFLAGS="-arch ppc -arch ppc64 -arch i386 -arch x86_64 -g -Os -pipe" CXXFLAGS="-arch ppc -arch ppc64 -arch i386 -arch x86_64 -g -Os -pipe" LDFLAGS="-arch ppc -arch ppc64 -arch i386 -arch x86_64 -bind_at_load" ./configure


    Then follow the rest of Erik's instructions for adding the extension to your copy of PHP.

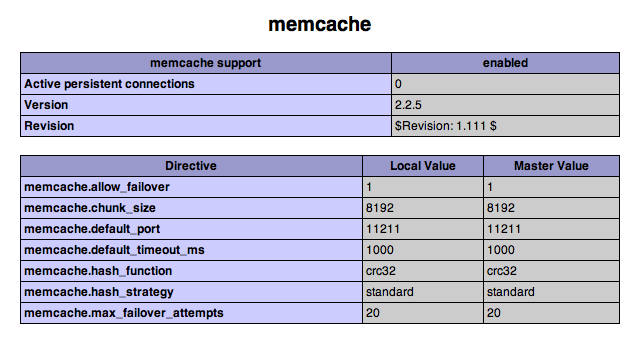
  3. Restart Apache: You can do this by restarting Web sharing in System preferences. Use the phpinfo(); command to check that the extension is working. You should see something like this:
    memcache.png

    If you don't see this, something's gone wrong. The Apache web log may help (for example, that's where I discovered that I had the problem reported by several people who commented on Erik's post.

  4. You can start the memcached daemon like this:

    # /bin/sh
    memcached -m 1 -l 127.0.0.1 -p 11211 -d

Now, I just need to explore how to actually use this...

Thursday, October 08, 2009

Linking Bulletin of Zoological Nomenclature to BHL

5839_200px.1254992426.png

After some fussing and hair pulling I've constructed a demo of linking a journal to the Biodiversity Heritage Library and displaying the results in Zotero (see my earlier post for rationale).

After some searching I managed to retrieve metadata for several hundred article from the Bulletin of Zoological Nomenclature. Using a local copy of the BHL metadata, I wrote a script that looked up each article in BHL and found the URL of the first page in the article. I then created a Zotero group for this journal and uploaded the linked references.

You can browse the group, and if you belong to Zotero you can join the group and get a local copy of the references (which you can edit and correct, the harvesting won't be perfect).

I've also added these references to my
bioGUID OpenURL resolver, making it easy to find a given article. For example, the OpenURL link http://bioguid.info/openurl/?genre=article&issn=0007-5167&volume=51&spage=7 displays a page for the article "Doris grandiflora Rapp, 1827 (currently Dendrodoris grandiflora; Mollusca, Gastropoda): proposed conservation of the specific name", together with a link to the article in BHL.


Wednesday, October 07, 2009

Zotero group for Biodiversity Heritage Library content

One thing I find myself doing (probably more often than I should) is adding a reference to my Zotero library for an item in the Biodiversity Heritage Library (BHL). BHL doesn't have article-level metadata (see But where are the articles?), so when I discover a page of interest (e.g., one that contains the original description of a taxon) I store metadata for the article containing that page in my Zotero library. Typically this involves manually step back through scanned pages until I find the start of the article, then store that URL as well as the page number as a Zotero item. As an example, here is the record for Ogilby , J. Douglas (1907). A new tree frog from Brisbane. Proceedings of the Royal Society of Queensland 20:31-32. The URL in the Zotero record http://www.biodiversitylibrary.org/page/13861218 take you to the first page of this article.

One reason for storing metadata in Zotero is so that these reference are made available through the bioGUID OpenURL resolver. This is achieved by regularly harvesting the RSS feed for my Zotero account, and adding items in that feed to the bioGUID database of articles. This makes Zotero highly attractive, as I don't have to write a graphical user interface to create bibliographic records. BHL have their own citation editor in the works ("CiteBank"), based on the ubiquitous Drupal, but I wonder whether Zotero is the better bet -- it has a bunch of nice features, including being able to sync local copies across multiple machines, and store local copies of PDFs (synced using WebDAV).

For fun I've created a Zotero group called Biodiversity Heritage Library which will list articles that I've extracted from BHL. At some point I may investigate automating this process of extracting articles (using existing blbiliographic metadata mapped to BHL page numbers), but for now there a mere 27 manually acquired items listed in the BHL group.


Tuesday, October 06, 2009

Wikipedia and Gregg's paradox

Continuing the theme of taxonomic classification in Wikipedia, I'm perversely delighted that Wikipedia demonstrates Gregg's paradox so nicely.
1s2mges1n3b5q1bnvf5a3i4u8y_2009-05-31.jpgThe late John R. Gregg wrote several papers and a book exploring the logical structure of taxonomy. His 1954 book The language of taxonomy stimulated a debate a decade later in Systematic Zoology concerning what Buck and Hull (1966) (doi:10.2307/2411628) termed "Gregg's Paradox".

Gregg showed that if we (a) treat taxa as sets defined by extension (i.e., by listing all members), and (b) accept that two sets with exactly the same content must be the same set, then many biological classifications violate these premises because the same taxon may be assigned to multiple levels in the Linnean hierarchy. For example, the aardvark, Orycteropus afer, is the only extant species of the genus Orycteropus, which is the only extant member of the family Orycteropodidae, which in turn is the sole extant representative of the order Tubulidentata. Under Gregg's model, Tubulidentata, Orycteropodidae, and Orycteropus are all the same thing as they have exactly the same content (i.e., Orycteropus afer). Put another way, monotypic taxa are redundant and violate basic set theory. Gregg would argue that they should be eliminated.

aardvark.pngWikipedia illustrates this nicely. Wikipedia conforms to Gregg's model in that taxa are defined by extension (each taxon comprises one or more wiki pages), and if taxa have the same content only one taxon (typically that with the lowest taxonomic rank) has a page in Wikipedia. Put another way, if the aardvark is the sole representative of the Tubulidentata, then there is nothing that could be put on the Tubulidentata page that shouldn't also belong on the page for the aardvark. As a result, the page for the aardvark gives a full classification of this animal, but most taxa in the hierarchy don't have their own pages.

Responses

There are several possible responses to Gregg's paradox. One is to argue that taxa should be defined intensionally (i.e., on the basis of their characters), which was Buck and Hull's approach. Essentially, they were arguing that we could (somewhat arbitrarily) specify properties of Orycteropodidae that weren't shared by all Tubulidentata, and hence we are justified in keeping these taxa separate. Gregg himself was less than impressed by this argument (doi:10.2307/2412017).

Another approach is to suggest that we may discover taxa in the future that will, say, be members of Orycteropus but which aren't O. afer, and that the taxa between the rank suborder and species are placeholders for these discoveries. Indeed, in the case of the Tubulidentata there are extinct aardvarks (doi:10.1163/002829675x00137, doi:10.1016/j.crpv.2005.12.016, and doi:10.1111/j.1096-3642.2008.00460.x) that could be added to Wikipedia, thus justifying the creation of pages for the taxa that Gregg would have us eliminate.

Of course, Gregg's paradox is a consequence of having ranks and requiring each rank (or at least a reasonable subset of them) to exist in a classification. If we ignore ranks, then there's no reason to put any taxa between Afrotheria and Orycteropus afer. So, we could drop this requirement for having taxa at each rank or, of course, drop ranks altogether, which is one of the motivations behind phylogenetic classifications (e.g., the phylocode).

Implications for parsing Wikipedia

From a practical point of view, Gregg's paradox means that one has to be careful parsing Wikipedia Taxoboxes. As I've argued earlier, the simplest way to ensure that a classification is a tree is for each taxon to include a unique parent taxon. The simplest way to extract this for a taxon in a Wikipedia page would be to retrieve the taxon immediately above it in the classification (i.e., for Orycteropus afer this would be Orycteropus). But Orycteropus doesn't have a page in Wikipedia (OK, it does, but it's a redirect to the page for the aardvark). So, we have to go up the classification until we hit Afrotheria before we get a taxon page.

Personally I quite like the fact that a largely forgotten argument from the middle of the last century concerning logic and Linnean taxonomy seems relevant again.

Monday, October 05, 2009

Wikipedia's taxonomic classification is badly broken

Wikipedia is wonderful, but parts of it are horribly broken. Take, for example, taxonomic classifications. A classification is a rooted tree, which means that each node in the tree has a single parent. We can store trees in databases in a variety of ways. For example, for each node we could store a list of its children, or we could store the single unique parent of each node. Ideally we'd choose to store one or other, but not both. If we store both sets of statements (i.e., that node A has node B as one of its children, and that node B's parent is node A) then there is enormous potential for these two statements to get out of sync.
tree.png


This is what has happened in Wikipedia. Each page for a taxon lists the lineage to which it belongs (i.e., its parent, and its parent's parent, and so on), and also lists the children of that node. What this means is that if somebody edits the page for taxon A and adds taxon B as a child, they also need to edit the page for taxon B to make A its parent. If only one of these two edits is made the classification may end up internally inconsistent.

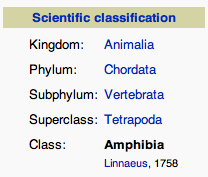
For example, the page for Amphibia lists the classification of Amphibia like this:
a1.png

It also lists the child taxa of Amphibia:
a2.png

So, the children of Amphibia are Temnospondyli, Lepospondyli, and Lissamphibia. Furthermore, Anura, Caudata, and Gymnophiona are children of Lissamphibia:

child.png


Given this, if I go to the pages for Anura, Caudata, and Gymnophiona I should see that each of these taxa lists Lissamphibia as its parent. However, only one of these (Caudata) does: the Anura and Gymnophiona both have Amphibia as their parents, not Lissamphibia.

The diagram below shows the taxa that have Amphibia as their parent:
parent.png


Note that Stegocephalia have now turned up as an addition amphibian order, and that only Caudata is included in Lissamphibia. But what is striking is that another 274 Wikipedia taxon pages have Amphibia as their parent. These pages are all for fossil amphibians that do not fit easily in the existing Wikipedia classification.

From the perspective of building a database, the "has parent" relationship is the one I'd prefer to use, because that statement is going to be made just once (on the page for the taxon of interest). This seems a lot safer than making the statement "has child" on another page (for one thing, more than one page could claim a taxon as their child, which again will break the tree). But if we use the "has parent" relationship, our tree will be very bushy, with lots of fossil amphibian genera attached to the Amphibia node. This is going to make the tree hard to interpret, because this basal bush isn't saying that all these genera radiated off at once, but rather that we don't really know where in the amphibian tree these things go, so we'll have to settle for saying merely "they are amphibians" (for the cladistic theorists among you, this is Nelson and Platnick's "interpretation 2" in their "Multiple Branching in Cladograms: Two Interpretations", doi:10.2307/2412630).

So, the dilemma is whether to use "has child" relationships, and accept that these are likely to be inconsistent with the inverse "has parent" relationship, or use the "has parent" relationship, which will be internally consistent, but at the cost of potentially very large, unresolved bushes due to fossil taxa of uncertain affinities.

Friday, October 02, 2009

Biodiversity Heritage Library sparklines

Time for a quick and dirty Friday afternoon hack. Based on responses to the BHL timeline I released two days ago, I've created a version that can compare the history of two names using sparklines (created using Google's Chart API). I use sparklines to give a quick summary of hits over time (grouped by decade).

The demo is here. It's crude (minimal error checking, no progress bars while it talks to BHL), but it's home time. As an example, here is a screen shot comparing the occurrences in BHL for two rival names for the sperm whale, Physeter catodon and Physeter macrocephalus:
physeter.png

There is a link to the full timeline for each of these names so you can investigate more. Note that the sparklines will be heavily biased by BHL coverage, but it may yield some interesting insights into the history of the usage of a name.

Thursday, October 01, 2009

Co-located Collaborative Tree Comparison

Stumbled across this cool visualisation project by Petra Isenberg at Calgary University. Collaborative tree comparison uses a tabletop system to enable two (or more) people to interact when comparing (in this case) phylogenies. I want one!

The system is described in "Interactive Tree Comparison for Co-located Collaborative Information Visualization" (doi:10.1109/TVCG.2007.70568), a PDF of which is available from her web site (which also has a great video entitled "how co-located collaborative data analysis should not take place").


Wednesday, September 30, 2009

Visualising the Biodiversity Heritage Library as a Timeline

bhlstrip.pngOne thing about the Encyclopedia of Life which bugs me no end is the awful way it displays the bibliography generated from the Biodiversity Heritage Library (BHL). The image on the right shows the bibliography for the frog Hyla rivularis Taylor, 1952. It's one long, alphabetical list of pages. How can a user make sense of this? It's even more annoying because the BHL is one of the cornerstones of EOL, and one could argue that BHL content is one of the few thing pages EOL offer that distinguishes them from cheap and cheerful mashups such as iSpecies. Can't we do something a little better?

BHL has an API (documented here), so I decided to experiment. As I mentioned in an earlier post (Biodiversity Heritage Library, Google books, and metadata quality), a key piece of metadata about a bibliographic reference is its date. This is especially so for the taxonomic literature, where the earliest reference that contains a name may (depending on how complete BHL scanning is) be the first description of that name. So, it would be nice to order the BHL bibliography by date. Turns out it's possible to get dates from quite a few BHL items, providing one fusses with regular expressions long enough.

So, in principle we could sort BHL content by dates. But, we could go one better and visualise them. As an experiment, I've put together a demo that uses the SIMILE Timeline widget to display the BHL bibliography for a taxon. Here's a screenshot of the bibliography for Hyla rivularis:
bhltimeline.png


You can generate others at http://bioguid.info/bhl/. The demo has been thrown together in haste, but here's what it does:
  1. Takes a taxon name and tries to find it in uBio. This gives us the NamebankID BHL needs
  2. Calls the BHL API and retrieves the bibliography for the NamebankID found in step 1
  3. Parses the BHL result, trying to extract dates (often the dates are ranges, e.g. 1950-1955)
  4. The previous step generates a JSON document which can be displayed by Timeline

If you click on an item you get a list of pages, clicking on any those takes to you to the page in BHL. Items that have a range of dates are displayed as horizontal lines, items with a well-defined date are shown as points. Note that my code for working out the date of an item will probably fail on some items, and some items don't have any dates at all. Hence, not every item in BHL will appear in the timeline.

It would be nice to embellish the results a little (for example, group pages into articles, refine the dates, etc.) but I think this goes a little way to demonstrating what can be done. We could also add articles obtained from other sources (e.g., Google Scholar, PubMed) to the same display, providing an overview of published knowledge about a taxon.