Saturday, June 07, 2014

Using GBIF to measure the lag between collection and description of a species (oh dear)

I'm adding more charts to the GBIF Chart tool, including some to explore the type status of specimens from the Solomon Islands. There are nearly 500 holotypes from this region, so quite a few new species have been discovered in this region.

Inspired by the Benoît Fontaine et al. paper on the lag time between a species being discovered and subsequently described (see Species wait 21 years to be described - show me the data) I thought I would do a quick and dirty plot of the difference between the year a specimen was collected and the year the name of the taxon it belongs to was published (from the authorship string for the scientific name). Plotting the results was *cough* interesting:
Types
In theory, the difference between the two dates should be negative (if you subtract publication year from collection year), the smaller number the less the wait for description. But I found some large positive numbers, implying that taxa had been described long before the types were discovered! Something is clearly wrong. What seems to be happening here is the GBIF has failed to match the species name for an occurrence, and so goes up the taxonomic hierarchy and just records the genus. For example, http://gbif.org/occurrence/472764211 was collected in 1965 and is the type of Pandanus guadalcanalius St.John. GBIF doesn't recognise this name, and so matches the occurrence to the genus Pandanus Linnaeus, 1782. hence it looks like we've used a time machine to describe a taxon in 1782 based on a specimen from 1965.

At the other end of the spectrum, there are a lot of specimens that seem to have waited over 200 years for description! Turns out these are mostly specimens from the MCZ that have their collection date recorded by GBIF as "1700-01-01". This seems an arbitrary date, and turns out it's an artefact. The MCZ records "unknown" collection dates as the range 1700-01-01 - 2100-01-01
(see http://mczbase.mcz.harvard.edu/guid/MCZ:IZ:DIPL-4985). Unfortunately, when it generates the export for GBIF, these get truncated to 1700-01-01, and GBIF then (not unreasonably) treats that as the actual collection date. Somewhere in the middle of the plot of lag between collection and description is some interesting information, but it's a pity that most of this is obscured by some serious data errors.

For me the bigger lesson here is the power of visualisation to explore the data and to expose errors. This is why I was underwhelmed by the new charts GBIF is releasing. Plots of ever upward trends are ultimately not very useful. They don't give much insight into the data, nor do they help tackle interesting questions. I think we need a much richer set of visualisations to really understand the strengths and limitations of the data in GBIF.

Update


Investigating further, there are some other reasons for the "back to the future" types. For example, http://www.gbif.org/occurrence/188826624 (CAS 5506 from FishBase) was collected in 1933 and is recorded as a holotype, with the scientific name Cypselurus opisthopus (Bleeker, 1865). 1933 - 1865 = 68, so the taxon was named 68 years before it was collected(!).

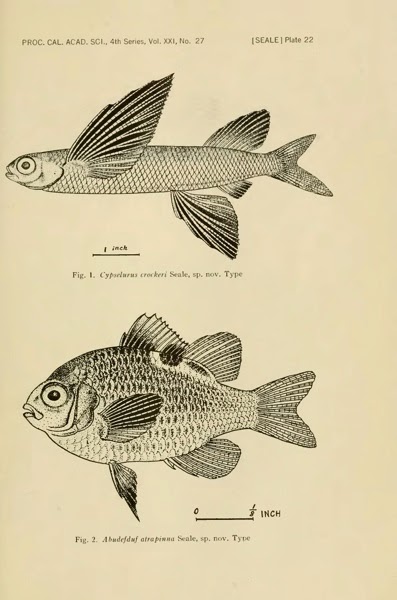
A bit of investigation using BioNames, BioStor, and GBIF (http://www.gbif.org/occurrence/473244692, another record for CAS 5506) reveals that CAS 5506 is the holotype for Cypselurus crockeri, shown below in a plate from it's original description (published in 1935):
Seale A (1935) The Templeton Crocker Expedition to western Polynesian and Melanesian islands, 1933. No. 27. Fishes. Proceedings of the California Academy of Sciences 21: 337–378. http://biostor.org/reference/59326

So, in fact this species was described shortly after its collection, with a lag of 1933 - 1935 = -2 years.

Proceedingsofcal421193336cali 0397
Apart from the duplication issue (FishBase has replicated some of the CAS dataset, sigh), the other problem is one of modelling the data. The CAS record has the original taxon name for which CAS 5506 is the type (Cypselurus crockeri), the FishBase record has the currently accepted name for the taxon (Cypselurus opisthopus). These two different approaches have very different implications for the charts I'm making, and simply reinforce my feeling that the GBIF data is both fascinating and full of "gotchas!".

Friday, June 06, 2014

Finding citations using full text search

Note to self on citation matching.

Looking for this paper "Fishes of the Marshall and Marianas islands. Vol. I. Families from Asymmetrontidae through Siganidae" I Googled it, adding "bistro" as a search term to see if I'd already added it to BioStor. The Google search:

https://www.google.co.uk/?gws_rd=ssl#q=Fishes+of+the+Marshall+and+Marianas+islands.+Vol.+I.+Families+from+Asymmetrontidae+through+Siganidae+biostor

found several hits in BioStor:

Google
What is interesting is that these hits are to full text of references that cite the article I'm after, not the article itself. I'm sure many have had this experience, where you are searching for an obscure article and you keep finding papers that cite it, rather than the actual paper you're after. But this suggests another strategy for building the citation graph for an article. If you have a decent corpus of full text articles, search for the article (using, say title, journal, pagination) in the text of those articles and store the hits. Those are the references that cite the article (OK, not all, but some of them). This may be a more attractive way of building the citation graph, rather than parsing citations in articles and trying to locate them. Indeed, it could be extended to help marking up those citations. Imagine grabbing blocks of text from near the end of an article, searching for those in a database of citations, using close matches to flag the corresponding block as a citation.

Need to think about this a little more...

Update


The paper is:

Polepeddi, L., Agrawal, A., & Choudhary, A. (n.d.). Poll: A Citation Text Based System for Identifying High-Impact Contributions of an Article. 2011 IEEE 11th International Conference on Data Mining Workshops. IEEE. doi:10.1109/icdmw.2011.136/blockquote>

More on visualisation of GBIF data

Following on from the previous post on visualising GBIF data, I've added some more interactivity. If you click on a pane in the treemap widget you get a list of the corresponding taxa, together with an image from EOL (if one exists). It's a fun way to quickly see what sort of species are present (in this case in the Solomon Islands). You can try it at http://bionames.org/~rpage/gbif-stats/.

Stats2

Pro tip


It's not obvious from the site, but to go back up the taxonomic hierarchy in the treemap, right click (ctrl-click on a Mac) on the grey bar corresponding to the higher taxon.

Wednesday, June 04, 2014

Visual analysis of GBIF data

Tim Roberston and the ream at GBIF are working on some nice visualisations of GBIF data, and have made an early release available for viewing: http://analytics.gbif-uat.org. For a given country, say, the Solomon Islands, you can see numerous plots, mostly like this:

Gbif

Ever the critic, as much as I like this (and appreciate the scale of the task underlying doing analytics on data at the scale of GBIF), what I would really like to see is something that more closely resembles Google Analytics. I want graphs that I can use to get some insight into the data, and which lead me to ask questions (and provide easy for me to discover the answers).

So, I put together a crude, live demo of the sort of thing I'd like to see. You can see it at http://bionames.org/~rpage/gbif-stats (can't promise that this link will be long-lived), and below is a screen shot:
Stats
What I've done is fetch all the occurrence records for the Solomon Islands from GBIF (using the API), dumped that into CouchDB, and generated some simple queries. I display the results using Google Charts. There are some similarities with the tools developed by Javier Otegui, Arturo Ariño, and colleagues.

Otegui, J., Ariño, A. H., Encinas, M. A., & Pando, F. (2013, January 25). Assessing the Primary Data Hosted by the Spanish Node of the Global Biodiversity Information Facility (GBIF). (G. P. S. Raghava, Ed.)PLoS ONE. Public Library of Science (PLoS). doi:10.1371/journal.pone.0055144
Otegui, J., & Arino, A. H. (2012, August 15). BIDDSAT: visualizing the content of biodiversity data publishers in the Global Biodiversity Information Facility network. Bioinformatics. Oxford University Press (OUP). doi:10.1093/bioinformatics/bts359


For fun I've also added a map of the GBIF occurrences (also served from CouchDB).

Here's quick guide to some of the charts. Below you can see (left) a plot of species accumulation over time, that is the total number of species that have been collected up to that time. If we had collected all the species we'd expect this to asymptote (flatten out). If it keeps going up, then we still need to do some sampling. On the right is the number of occurrences recorded for each year. You can see that collecting is highly episodic.

Stats2

To get a little more information on this, I've generated a crude chart where the rows are institutions (e.g., museums and herbaria) that have specimens, and the number of occurrences collected each decade are represented by the shaded boxes (the rightmost box is the current decade) (if you hover over a bar you will see a popup with the decade). To the right is the total number of occurrences.

Chart
From this we can see that there have been some major collections at various times (e.g., Kew in the 1960's, the Australian Museum in the 1970's to 1990's). Strangely, the MCZ has lots of specimens from the 1700's, I suspect we have a data quality issue here. There are certainly some issues with dates in this data set, with about a quarter of occurrences with no date:

Date

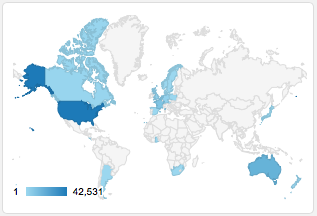
Note that the data for the Solomon Islands, comes from all around the world, mostly from the US. There is a big spike in the date of collection curve in 1944, suggesting a lot of material may be the result of collecting by US servicemen in WW2.

Map

I use a treemap to display the taxonomic distribution of the records, and a donut chart to summarise the taxonomic level to which the occurrences are identified:

Taxa
The treemap is dominated by vertebrates, which I suspect is a poor reflection of the actual taxonomic composition of the Solomon Islands biota. Over 3/4 of the occurrences are identified to species level, which is encouraging, but there's clearly a lot of material that needs some taxonomic work.

Where next


This has been made in a rush, and there is a lot which could be done. For example, some of the charts would be more useful if you could drill down and explore further. This could be done via the GBIF API or portal (for example, by constructing a URL that shows the portal results for the Solomon Islands for a given year of collection).

There are, of course, issues of scalability. I've made this for the 83,364 occurrences currently in the GBIF portal for the Solomon Islands. There would need to be some thought given to how this could be scaled to larger data sets. But I think this is worth pursuing so that we can get further insights into the remarkable database that GBIF is building.

Monday, June 02, 2014

BioNames one year on

B8e253dc3be3d84f2c69c51b0af86c03 400x400It is almost a year to the day that I released BioNames, a database of "taxa, texts, and trees". This project was my entry in EOL's Computable Data Challenge. Since it went live (after much late night programming by myself and Ryan Schenk) I've been tweaking the interface, cleaning (so much cleaning), and adding data (mostly DOIs, links to BioStor, and PDFs). I also wrote a paper describing the project, published in PeerJ (http://dx.doi.org/10.7717/peerj.190).

Why BioNames?


I'm building BioNames to scratch a very specific itch. To me it is a source of enormous frustration that one of the most basic questions we can ask about a name (where was it first published?) is difficult to answer using current taxonomic databases. And if there is an answer, it is usually given as a text string describing the publication (i.e., a literature citation) rather than an identifier such as a DOI that enables me to (a) go to the publication, (b) refer to the publication in a database in an unambiguous way, and (c) discover further information about that publication by querying services that recognise that identifier.

There are enormous digitisation efforts underway by commercial publishers, digital archives, and libraries, and all of this is putting more and more literature online. This is the primary evidence base for taxonomy, it is where new names are published, taxa are described, and hypotheses of synonym and relationship are proposed, and we should be actively linking to it. Of course, there are some projects that do this, but these are typically restricted in taxonomic or geographic scope. I want all this information together in one place. Hence, BioNames.

Of course, I could wait until projects like ZooBank have all the animal names, but as I pointed out in Why the ICZN is in trouble, the ICZN and ZooBank have only a tiny fraction of the published names:
ICZN
This renders ZooBank barely usable for my purposes. There are millions of animal names in circulation, and our inability to discover much about them leads to all sorts of headaches, such as the errors in GBIF that I've mentioned earlier on this blog. I want a tool that can help me interpret those errors, and I want it now, hence BioNames.

What is in BioNames?


The original data comes from the LSID metadata served by ION. At the moment BioNames has 4,880,925 names, 1,549,152 of which are linked to a bibliographic citation. The bulk of the time I spend on BioNames consists of cleaning and clustering these citations, and linking them to digital identifiers.

To get some insight into what is left to be done I created a CSV dump of the publication data underlying BioNames, and loaded it into Google's Cloud Storage (http://storage.googleapis.com/ion-names/names3.csv). I then used Google's BigQuery to write some simple SQL queries. You can find more details here: https://github.com/rdmpage/bionames-bigquery.

Here is a summary table of the number of names that are published in an article with one of the identifiers that I track. These include DOIs, PMIDs, as well as whether the article is in BioStor, has a URL (typically to a publisher's web site), or a PDF.
IdentifierNumber of names
DOI196,915
BioStor130,792
JSTOR23,483
CiNii11,296
PMID8,886
URL72,754
PDF161,474
(any)489,029


The final row is the number of articles that have at least one identifier (some articles have multiple identifiers, such as a DOI and a link to BioStor). Given that there are approximate 1.5 million names with bibliographic citations, and around 490,000 have an identifier, the user as a 30% chance of finding the original description for an animal name picked at random. Obviously, BioNames has gaps (ION has missed a number of names, and/or publications), the taxonomic coverage of bibliographic identifiers is uneven (depending on the publications chosen by taxonomists to publish in, and the level of digitisation of those publications), and there is still a lot of data cleaning to do. But an almost 1 in 3 chance of finding something useful for a name seems a reasonable level of progress.

Out of interest I created some quick and dirty charts in Excel for different categories of identifier. Here, for example, is the percentage of names published each year that are linked to a publication with a DOI:
Doi
Over 80% of names published in 2013 were in an article with a DOI, so we are fast heading to a situation where modern zoological taxonomy is fully part of the citation graph of science. Much of this spike in 2013 is due to the adoption of DOIs by Zootaxa, which is far and away the dominant journal in animal taxonomy.

Here is the same chart for publications in BioStor.
Biostor graph
The big spike at the start is for names where the year of publication is missing. Leaving that aside, we can see the impact of the 1923 copyright cut-off in the US, which puts a big dent in the Biodiversity Heritage Library's digitisation efforts. Note, however, that BHL has a lot of post-1923 content.


Does anyone use BioNames?


I use BioNames almost every day, and have devoted way more time than is healthy to populating it. As I explore issues like the quality of the taxonomy in GBIF, I find it useful to see the original descriptions of a taxa, and its fate in subsequent revisions. In the early days I'd spend more time adding missing papers to help answer a question, but increasingly I'm finding that the content is already there. So, I find it useful, but what (gulp) if I'm the only one?

Below is the number of "sessions" per day since BioNames was launched (data from Google Analaytics for May 1st, 2013 to May 31st, 2014). After an initial flurry of interest, web traffic pretty quickly died off. Since then it's been slowly gaining more visitors, then (for reasons which escape me), it started getting a lot more traffic in April onwards:
Bionames
To give these numbers some context, for the same period BioStor (my archive of articles from BHL) had the following traffic:
Biostor
Note the different scales, BioStor is getting around 500 sessions a day during week days, BioNames gets around 200. By way of comparison, GBIF gets up to 4000 sessions a day, and this blog typically has 50-100 sessions per day.

Where next?


There are a couple of directions for the future. There is still a lot of data cleaning and linking to do. Last year I did a quick analysis of which taxonomic journals should be digitised next. I've updated this by creating a a spreadsheet that ranks the journals in BioNames by the number of names each has published, and each is coloured by the fraction of those names for which I've found a digital identifier for the paper in which they are published. This table is incomplete, and reflects not only the extent of digitisation, but also the extent to which I've managed to locate the journals online. But it is a starting point for thinking about what journals to prioritise for digitisation, or if they are already divitised, journals that I need to target for addition to BioNames. The spreadsheet is available as a Google sheet.

Another direction is data mining. In addition to the obvious task, naming locating and indexing taxonomic names, there are other things to be done. In BioStor I extract geographic point localities and specimen codes from the OCR text. These could be indexed to enable geographic or specimen-based searching. The same approach could be generalised to the literature in BioNames, so that we could track the mentions of a particular specimen, or retrieve lists of publications about a specific locality (e.g., all taxonomic papers that refer to a particular mountain range, deep sea vent, or island).

BioNames also does some limited analysis of taxonomic name co-ocurrence, for example suggesting that species names with the same specific epithet but different generic names are possible synonyms if they occur on the same page. There is a lot of scope for expanding this. I'm also keen to explore citation indexing, that is, extracting lists of literature cited from articles in BioNames, and linking those to the corresponding record in BioNames. Ultimately I want to be able to navigate through the taxonomic literature along these citation links, so that we can trace the fate of names through time.

But this is still only a start, papers such as Seltmann et al. illustrate other things that are possible once we have a large corpus of taxonomic literature available:

Seltmann, K. C., Pénzes, Z., Yoder, M. J., Bertone, M. A., & Deans, A. R. (2013, February 18). Utilizing Descriptive Statements from the Biodiversity Heritage Library to Expand the Hymenoptera Anatomy Ontology. (C. S. Moreau, Ed.)PLoS ONE. Public Library of Science (PLoS). doi:10.1371/journal.pone.0055674


So, a lot still to be done. I hope to have achieved some of this if and when I write a follow up post on the status of BioNames in a year's time.


Thursday, May 15, 2014

DOIs are not enough

I had a long Twitter conversation with Terry Catapano (@catapanoth) today, and as can happen with a distracted stream of tweets, I think we were a little at cross purposes. This blog post is an attempt to unpack the debate.

What prompted the conversation was the following paper:
Emery, Carlo et al (1899). Formiche di Madagascar raccolte dal Sig. A. Mocquerys nei pressi della Baia di Antongil (1897-1898).. Bullettino della Società Entomologica Italiana: 31 (1899) pp. 263-290. 10.5281/zenodo.9785
Not the paper so much, as the fact that it is stored on the Zenodo repository (which I was only looking at because of the announcement that GitHub now supports DOIs through Zenodo). Given that the PDF for Emery's paper was uploaded by the Plazi project, I wondered what was the intention of assigning a Zenodo DOI to this paper, rather than one from CrossRef.

Not all DOIs are equal


As Geoffrey Bilder notes in his post DOIs unambiguously and persistently identify published, trustworthy, citable online scholarly literature. Right?
...some have adopted a cargo-cult practice of seeing the mere presence of a DOI on a publication as a putative sign of “citability” or “authority.”
There is a danger that we fall into the trap of thinking that all we need to do is slap a DOI on a paper and all the good things that we associate with DOIs will magically happen. This isn't the case. Not all DOIs are the same. Zenodo DOIs are proved by DataCite, and DataCite DOis don't have all the features that CrossRef provides for their DOIs.

CrossRef provides some key services, one of the most important is discoverability. Given a bibliographic references, CrossRef has tools that can find whether it has a DOI (e.g., http://search.crossref.org). I use this a lot to map taxonomic papers to DOIs (by a lot I mean searching for DOIs for tens of thousands of articles). Most people don't do this, but you benefit from this service every time you read an article and see the literature cited section decorated with DOIs. Publishers use CrossRef's tools to convert citations from dumb strings to useful links. This feature we come to expect from any modern article relies on CrossRef have definitive metadata for lots (millions) or articles, all of which have DOIs. When publishers submit article metadata when registering their DOIs, they usually submit lists of literature cited (and the DOIs). This means that CrossRef is building a citation database, which you can see if you visit the web page for an article and see a "cited by" link.

Then there are additional services. Given that CrossRef has high quality bibliographic metadata for articles, if you have a DOI there is no need to type in the details of a paper. Most bibliographic software such as Mendeley and Zotero can take a DOI and flesh out those details for you. If a DOI fails to resolve, you can contact CrossRef Support and have somebody investigate. Then there are the new services such as FundRef and Prospect, which provide information on who funded a paper, and what text and data mining rights are available for a paper.

Why use DOIs?


The rationale for using DOIs for articles is so that they can be unambiguously identified, which in turn means we can build a robust citation network. But this requires infrastructure, and that is what CrossRef provides through tools like citation to DOI matching. Other DOI registration agencies don't do this, and CrossRef isn't aware of other DOIs, so putting, say, a DataCite DOI (such as those used by Zenodo) on an article doesn't achieve the primary goal of a DOI (embedding it in the citation graph of academic literature).

Hence, I regard putting a Zenodo DOI as basically a wasted opportunity. If we aren't making the primary biodiversity literature discoverable, and hence linkable, then all we are doing is keeping that literature in a ghetto (and reinforcing the impression that this literature, and taxonomy itself, really doesn't matter). It is striking that if you read a recent paper that describes a new species, the bulk of the systematic or ecological literature has DOIs, but the bulk of the taxonomic literature does not. If it doesn't have a CrossRef DOI, it's effectively invisible. All academic literature should get first class DOIs. Whether it's "legacy" or not is irrelevant, the Royal Society of London has DOIs on articles going back to 1800, these are now as accessible as any paper published today.

Eyes on the prize


So, if we are going to bring the taxonomic literature into the mainstream, make it discoverable and citable, then we should focus on bringing that literature into CrossRef's infrastructure. Archives like JSTOR do it, the Biodiversity Heritage Library (BHL) does it for some of its content (and they should be doing it at article level, right now).

One response to this is to say "but doesn't this cost money?" Of course it does. Everything does, nothing is free. What frustrates me most about this is that it's the wrong question. The first question should not be "how much does this cost?". If it is, you've already lost sight of the goal. Instead, we should be asking, "What do we want? Where do we need to be able to do to progress our field?". Once we articulate that, then we figure out how to pay for it. And we figure that out because we've decided this is what we need.

I think we want discoverable, citable taxonomic literature, embedded in the rest of the scientific literature and the publishing process. We don't get that by simply buying the cheapest DOIs available and slapping them on articles. To do so is to fundamentally misunderstand why DOIs matter, and to ignore the role that infrastructure plays in their success in academic publishing.

Tuesday, May 06, 2014

Very large phylogeny viewer

As announced on phylobabble I've started to revisit visualising large phylogenies, building on some work I did a couple of years ago (my how time flies). This time, there is actual code (see https://github.com/rdmpage/deep-tree) as well as a live demo http://iphylo.org/~rpage/deep-tree/demo/.

You can see the amphibian tree below at http://iphylo.org/~rpage/deep-tree/demo/show.php?id=5369171e32b7a:

Tree

You can upload or paste a tree (for now in NEXUS format), or paste in a URL to a NEXUS file (e.g., from TreeBASE). I'll formats when I get the chance. The viewer uses the same approach as Google Maps, breaking the image of the tree into "tiles" of a fixed size, so even if the tree image is huge, the web browser only ever displays the same number of tiles. You can zoom in to see individual taxa, or zoom out for an overview. One reason I'm building this is to display DNA barcoding trees alongside the million DNA barcode map.

As ever this is a crude first attempt, but feel free to try it and let me know how you get on.

Monday, April 21, 2014

Is collecting specimens necessary?

Some interesting threads in TAXACOM today (yes, really). The following article has appeared in Science:
Minteer, B. A., Collins, J. P., Love, K. E., & Puschendorf, R. (2014, April 18). Avoiding (Re)extinction. Science. American Association for the Advancement of Science (AAAS). doi:10.1126/science.1250953 (paywall)
The authors argue that "The availability of adequate alternative methods of documentation, including high-resolution photography, audio recording, and nonlethal sampling, provide an opportunity to revisit and reconsider field collection practices and policies."

This has brought a swift response from Kevin Winkler
(Re)affirming the specimen gold standard who argues that physical specimens are vital for much of the science that museum collections support.

At the same time, David Schindel has posted on Minimum standards for e-voucher documentation, that is, DNA samples where no physical voucher exists (e.g., because the organism is a member of an endangered species, or still alive).

Wednesday, April 16, 2014

Breaking the Biodiversity Heritage Library

The Biodiversity Heritage Library (BHL) has recently introduced a feature that I strongly dislike. The post describing this feature (Inspiring discovery through free access to biodiversity knowledge... states:

Now BHL is expanding the data model for its portal to be able to accommodate references to content in other well-known repositories. This is highly beneficial to end users as it allows them to search for articles, alongside books and journals, within a single search interface instead of having to search each of these siloes separately.

What this means is that, whereas in the past a search in BHL would only turn up content actually in BHL, now that search may return results from other sources. What's not to like? Well, for me this breaks the fundamental BHL experience that I've come to rely on, namely:

If I find something in BHL I can read it there and then

With the new feature, the search results may include links to other sources. Sometimes these are useful, but sometimes they are anything but. Once you start including external links in your search results, you have limited control over what those links point to. For example, if I search BHL for the journal Revista Chilena de Historia Natural I get two hits. Cool! So I click on one hit and I can read a fairly limited set of scanned volumes in BHL, if I click on the other hit I'm taken to a page at the Digital Library of the Real Jardín Botánico of Madrid. This is a great resource, but the experience is a little jarring. Worse, for this journal the Real Jardín Botánico doesn't actually have any content, instead the "View Book" link takes me to SciElo in Chile, where I can see a list of recent volumes of this journal.

In this case, BHL is basically a link farm that doesn't give me direct access to content, but instead sends me on a series of hops around the Internet until I find something (and I could have gotten there more quickly via Google).

What is wrong with this?


There are two reasons I dislike what BHL have done. The first is that it breaks the experience of search then read within a consistent user interface. Now I am presented with different reading experiences, or, indeed, no reading at all, just links to where I might find something to read.

More subtlety, it undermines a nice feature of BHL, namely searching by taxonomic names. The content BHL has scanned has also been indexed by taxonomic name, so often I find what I'm looking for not by using bibliographic details (journal name, volume, etc.), which are often a bit messy, but by searching on a name. External content has not been indexed by name, so it can't be found in this way. Whereas before, if I search by name I would be reasonably confident that if BHL had something on that name I could find it (barring OCR errors), now BHL may well have what I looking for (in an external source) but can't show me that because it hasn't been indexed.

From my perpsective, the things I've come to rely on have been broken by this new feature (and I haven't even begun to talk about how this breaks things I rely on to harvest BHL for article metadata, which I then put into BioStor, which in turn gets fed back into BHL).

What should BHL have done?


To be clear, I'm not arguing against BHL being "able to accommodate references to content in other well-known repositories". Indeed, I'd wish they'd go further and incorporate content from BHL-Europe, whose portal is, frankly, a mess. Rather, my argument is that they should not have done this within the existing BHL portal. Doing so dilutes the fundamental experience of that portal ("if I find it I can read it").

Here's what I would do instead:
  1. Keep the current BHL portal as it was, with only content actually scanned and indexed by BHL.
  2. Create a new site that indexes all relevant content (e.g., BHL, BHL-Europe, and other repositories.
  3. Model this new portal on something like CrossRef's wonderful metadata search. That is, throw all the metadata into a NoSQL database, add a decent search engine, and provide users with a simple, fast tool.
  4. The portal should clearly distinguish hits that are to BHL content (e.g. by showing thumbnails) and hits that are to external links (and please filter links to links!).
  5. Add taxonomic names to the index (you have these for BHL content, adding them for external content is pretty easy).
  6. Even more useful, start indexing full text content, maybe starting at articles ("parts"). At the moment Google is doing a better job of indexing BHL content (indirectly via indexing Internet Archive) than BHL does.

Creating a new tool would also give BHL the freedom to explore some new approaches without annoying users like me who have come to rely on the currently portal working in a certain way. Otherwise BHL risks "feature creep", however well motivated.

Thursday, April 10, 2014

User interface to edit a point location

Circle
Following on from earlier posts on annotating biodiversity data (Rethinking annotating biodiversity data and More on annotating biodiversity data: beyond sticky notes and wikis) I've started playing with user interfaces for editing data.

For example, here's a simple interface to edit the location of a specimen or observation (inspired by the iNaturalist observation editor). You can play with this below or on on bl.ocks.org, and the source code is on GitHub https://gist.github.com/rdmpage/9951904.


Tuesday, April 08, 2014

The Experimenter’s Museum: GenBank, Natural History, and the Moral Economies of Biomedicine

An undergraduate student (Aime Rankin) doing a project with me on citation and impact of museum collections came across a paper I hadn't seen before:
Strasser, B. J. (2011, March). The Experimenter’s Museum: GenBank, Natural History, and the Moral Economies of Biomedicine. Isis. University of Chicago Press. doi:10.1086/658657


Unfortunately the paper is behind a paywall, but here's the abstract (you can also get a PDF here):

Today, the production of knowledge in the experimental life sciences relies crucially on the use of biological data collections, such as DNA sequence databases. These collections, in both their creation and their current use, are embedded in the experimentalist tradition. At the same time, however, they exemplify the natural historical tradition, based on collecting and comparing natural facts. This essay focuses on the issues attending the establishment in 1982 of GenBank, the largest and most frequently accessed collection of experimental knowledge in the world. The debates leading to its creation—about the collection and distribution of data, the attribution of credit and authorship, and the proprietary nature of knowledge—illuminate the different moral economies at work in the life sciences in the late twentieth century. They offer perspective on the recent rise of public access publishing and data sharing in science. More broadly, this essay challenges the big picture according to which the rise of experimentalism led to the decline of natural history in the twentieth century. It argues that both traditions have been articulated into a new way of producing knowledge that has become a key practice in science at the beginning of the twenty-first century.

It's well worth a read. It argues that sequence databases such as Genbank are essentially the equivalent of the great natural history museums of the 19th Century. There are several ironies here. One is that some early advocates of molecular biology cast it as a modern, experimental science as opposed to mere natural history. However, once the amount of molecular data became too great for individuals to easily manage, and once it became clear that many of the questions being asked required a comparative approach, the need for a centralised database of sequences (the "experimenter's museum" of the title of the paper) became increasingly urgent. Another irony is that the clash between molecular and morphological taxonomy overlooks these striking similarities in history (collecting ever increasing amounts of data eventually requiring centralisation).

Bruno Strasser's article also discusses the politics behind setting up GenBank, including the inevitable challenge of securing funding, and the concerns of many individual scientists about the loss of control over their data. A final irony is that, having gone through this process once with the formation of the big museums in the 19th century, we are going through it again with the wrangling over aggregating the digitised versions of the content of those museums.

Update: See also
Strasser, B. J. (2008, October 24). GENETICS: GenBank--Natural History in the 21st Century? Science. American Association for the Advancement of Science (AAAS). doi:10.1126/science.1163399
(via Guanyang Zhang).

Friday, April 04, 2014

More on annotating biodiversity data: beyond sticky notes and wikis

Following on from the previous post Rethinking annotating biodiversity data, here are some more thoughts on annotating biodiversity data.

Annotations as sticky notes


I get the sense that most people think of annotations as "sticky notes" that someone puts on data. In other words, the data is owned by somebody, and anyone who isn't the owner gets to make comments, which the owner is free to use or ignore as they see fit. With this model, the focus is on how the owner deals with the annotations, and how they manage the fact that their data may have changed since the annotations were made.

This model has limitations. For a start, it privileges the "owner", and puts annotators at their mercy. For example, I posted an issue regarding a record in the Museum of Comparative Zoology Herpetology database (see https://github.com/mcz-vertnet/mcz-subset-for-vertnet/issues/1). VertNet has adopted GitHub to manage annotations of collection data, which is nice, but it only works if there's someone at the other end ready to engage with people like me who are making annotations. I suspect this is mostly not going to be the case, so why would I bother annotating the data? Yes, I know that VertNet has only just set this up, but that's missing the point. Supporting this model requires customer support, and who has the resources for that? If I don't get the sense that someone is going to deal with my annotation, why bother?

So, the issues here are that the owner gets all the rights, the annotators have none, and in practice the owners might not be in a position to make use of the annotations anyway.

Wikis


OK, if the owner/annotator model doesn't seem attractive, what about wikis? Let's put the data on a wiki and let folks edit it, that'll work, right? There's a lot to be said in favour of wikis, but there's a disadvantage to the basic wiki model. On a wiki, there is one page for an item, and everyone gets to edit that same page. The hope is that a consensus will emerge, but if it doesn't then you get edit wars (e.g., When taxonomists wage war in Wikipedia). If you've made an edit, or put your data on a wiki, anyone can overwrite it. Sure, you can roll back to an earlier version, but so can anyone else.

Wikis bring tools for community editing, but overturn ownership completely, so the data owner, or indeed any individual annotator has no control over what happens to their contributions. Why would an expert contribute if someone else can undo all their hard work?

Social data


So, if sticky notes and wikis aren't the solution, what is? I've been looking at Fluidinfo lately. There's an interview here, and a book here. The company has gone quiet lately (apparently focussing on enterprise customers), but what matters here is the underlying idea, namely "social data".

Fluidinfo's model is that it is a database of objects (representing things or concepts), and anyone can add data to those objects (they are "openly writable"). The key is that every tag is linked to the user, and by default you can only add, edit, or delete your own tags. This means that if a data provider adds, say a bibliographic reference to the database, I can edit it by adding tags, but I can't edit the data provider's tags. To make this a bit more concrete, suppose we have a record for the article with the DOI 10.1163/187631293X00262. We can represent the metadata from CrossRef like this:

{
"_id": "10.1163/187631293X00262",
"crossref/doi" : "10.1163/187631293X00262",
"crossref/title" : "A taxonomic review of the pondskater...",
"crossref/journal" : "Insect Systematics & Evolution",
"crossref/issn" : [ "1399-560X", "1876-312X"]
}

Note the use of the namespace "crossref" in the tags. This is data that, notionally, CrossRef "owns" and can edit, and nobody else. Now, as I've discussed earlier (Orwellian metadata: making journals disappear) some publishers have an annoying habit of retrospectively renaming journals. This article was published in Entomologica Scandinavica, which has since been renamed Insect Systematics & Evolution, and CrossRef gives the latter as the journal name for this article. But most citations to the article will use the old journal name. Under the social data model, I can add this information (in bold):

{
"_id": "10.1163/187631293X00262",
"crossref/doi" : "10.1163/187631293X00262",
"crossref/title" : "A taxonomic review of the pondskater...",
"crossref/journal" : "Insect Systematics & Evolution",
"crossref/issn" : ["1399-560X", "1876-312X"],
"rdmpage/journal" : "Entomologica Scandinavica","rdmpage/issn" : ["0013-8711" ]
}

My tags have the namespace "rdmpage", so they are "mine". I haven't overwritten the "crossref" tags. Somebody else could add their own tags, and of course, CrossRef could update their tags if they wish. We can all edit this object, we don't need permission to do so, and we can rest assured that our own edits won't be overwritten by somebody else.

This model can be quite liberating. If you are a data provider/owner, you don't have to worry about people trampling over your data, because you (and any users of your data) can simply ignore tags not in your namespace ("ignore those rdmpage' tags, that Rod Page chap is clearly a nutter"). Annotators are freed from their reliance on data providers doing anything with the annotations they created. I don't care whether CrossRef decides to revert the journal name Insect Systematics & Evolution to Entomologica Scandinavica for earlier article (or not), I can just use the "rdmpage/journal" (if it exists) to get what I think is the appropriate journal name. My annotations are immediately usable. Because everyone gets to edit in their own namespace, we don't need to form a consensus, so we don't need the version control feature of wikis to enable roll backs, there are no more edit wars (almost).

Implementation


A key feature of the Fluidinfo social data model is that the data is stored in a single, globally accessible place. Hence we need a global annotation store. Fluidinfo itself doesn't seem to have a publicly accessible database, I guess in part because managing one is a major undertaking (think Freebase). Despite Nicholas Tollervey's post (FluidDB is not CouchDB (and FluidDB's secret sauce)), I think CouchDB is exactly the way I'd want to implement this (it's here, it works, and it scales). The "secret sauce" is essentially application logic (every key has a namespace corresponding to a given user).

The more I think about this model the more I like it. It could greatly simplify the task of annotating biodiversity data, and avoid what I fear are going to be the twin dead ends of sticky note annotation and wikis.

Monday, March 31, 2014

Rethinking annotating biodiversity data

TL;DR By using bookmarklets and a central annotation store, we can build a system to annotate any biodiversity database, and display those annotations on those databases.

A couple of weeks ago I was at GBIF meeting in Copenhagen, and there was a discussion about adding a new feature to the GBIF portal. The conversation went something like this:

Advisor: "We really need this feature, now!"

Developer: "OK, but which of these other things you've told us we need to do should we stop doing, so we can add this new feature?"

Resources are limited, and adding new features to a project can be difficult. This got me thinking about the issue of annotating data, in GBIF and other biodiversity projects. There have been a number of recent papers on annotating biodiversity data, such as:

Morris, R. A., Dou, L., Hanken, J., Kelly, M., Lowery, D. B., Ludäscher, B., Macklin, J. A., et al. (2013, November 4). Semantic Annotation of Mutable Data. (I. N. Sarkar, Ed.)PLoS ONE. Public Library of Science (PLoS). doi:10.1371/journal.pone.0076093
Tschöpe, O., Macklin, J. A., Morris, R. A., Suhrbier, L., & Berendsohn, W. G. (2013, December 20). Annotating biodiversity data via the Internet. Taxon. International Association for Plant Taxonomy (IAPT). doi:10.12705/626.4

It seems to me that these potentially suffer the assumption that data aggregators such as GBIF, and data providers such as natural history collections have sufficient resources in place to (a) implement such systems, and (b) process the annotations made by the community and update their records. What if neither assumption holds true?

Everyone is busy


Any system which requires a project to add another feature is going to have to compete with other priorities. I ran into this with my BioNames project, which was partly funded by EOL. BioNames links taxonomic names for animals (obtained from ION) to the primary literature, for example Pinnotheres atrinicola was published in the following paper:

Page, R. D. M. (1983). Description of a new species of Pinnotheres , and redescription of P. novaezelandiae (Brachyura: Pinnotheridae) . New Zealand Journal of Zoology, 10(2), 151–162. doi:10.1080/03014223.1983.10423904.

Ideally, all the links between names and publications that I'd assembled in BioNames would have been added to EOL, so that (wherever possible) users of EOL could see the original description of a taxon in EOL. But this didn't happen. In order to get BioNames into EOL I had to export the data in Darwin Core format, which is poorly suited to this kind of data. It also became clear that BioNames and EOL had rather different data models when it came to taxa, names, and publications. This meant it was going to be challenge providing the data in w ay that was usable by EOL. Plus, EOL was pretty busy doing other things such as developing TraitBank™ (yes, that's a "™" after TraitBank). So, I never did get BioNames content into EOL.

But there's another way to do this.

The Web means never having to ask for permission


It occurred to me (around about the time that I was at the pro-iBiosphere hackathon at Leiden) that there's another way to tackle this, a way which uses bookmarklets. Bookmarklets are little snippets of Javascript that can be stored as bookmarks in your web browser, and they can add extra functionality to an existing web page. You may well have come across these already, such as Save to Mendeley , or Altmetric it.

How does this help us with annotation? Well, with a little programming, you can add features that you think are "missing" from a web page, and you don't need to ask anyone's permission to do it. So, I could negotiate with EOL about how to get data from BioNames into EOL, or I can simply do this:

2014 03 31 17 05 26

What I've done here is create a bookmarklet that recognises that you are looking at an EOL page, it then calls the BioNames API and displays the original publication of the taxon displayed on the page (in this case, Pinnotheres atrincola). So, I've added the information from BioNames to the EOL page, without needing EOL to do anything.

But it gets better. We can do this with pretty much any web page. The example above displays the original publication of a taxon name, but imagine we are looking at the publisher's page for that article (you can see it here: http://dx.doi.org/10.1080/03014223.1983.10423904). Wouldn't it be nice if the publisher knew that this paper described a new species of crab? We could negotiate with the publisher about how to give them that information, and how they could display it, or we can just add it:

2014 03 31 17 15 08

This time the bookmarklet recognises that the web page has a DOI, then asks BioNames whether there have been any names published in the paper with that DOI, if it finds any they are displayed in the popup.

Bookmarklets enable you to enhance a web page with any information you like. This makes them ideal for displaying annotations on a page. If you want to try yourself, you can grab the bookmarklet from here.

Making annotations visible


Bookmarklets can be used to solve one part of the annotation problem, namely showing existing annotations. I have lots of exmaples of errors in datasets, I blog about some of these, I store some in Evernote for future reference, some end up in unfinished manuscripts, and so on. The problem is that these annotations are of little use to anyone else because if you go to GBIF you don't see my annotations (or, indeed, anyone else's). But we can use a bookmarklet to display these, without having to pester GBIF themselves to add this feature! Imagine a bookmarklet that you could click on and it shows you whether anyone as queried the identification of a specimen, or the location of a specimen?

Where do the annotations come from?


Of course, all this presupposes that we have annotations to start with. I think there are at least two classes of annotations. The first, most obvious annotations are ones that change or add attributes to an object. For example, adding latitude and longitude coordinates to a specimen. These are annotations we would want to display just on the corresponding page in the source database (e.g., displaying a map in the annotation popup on GBIF for a record we've georeferenced).

The second class comprise cross-links between data sets. For example, linking a species in EOL to DOI of the publication that first described that species. Or linking a specimen in GBIF to the sequences in GenBank that were obtained from that specimen. These annotations are different in that we might want to display them on multiple web pages (e.g., pages served by both a biodiversity database and an academic publisher). From this perspective, a database like BioNames is essentially a big store of annotations.

But we need more than this, we need to be able to annotate any class of data that is relevant to biodiversity. We need to be able to edit erroneous GBIF records, flag Genbank sequences that have been misidentified, document taxonomic names that are entirely spurious, and so on. And we need to make these annotations available via APIs so that anywone can access them. To me, it seems obvious that we need a single, centralised annotation store.

A global annotation store


One way to implement an annotation store would be to create a wiki-style database that the community could edit. This database gets populated with data that can then be edited, refined, and discussed. For example, imagine a GBIF user spots an occurrence that is clearly wrong (a frog in the middle of the ocean). They could have a bookmarklet that they click on, and it displays any existing annotations of that record. If there aren't any, let's imagine there is a link to the annotaion store. Clicking on that creates a record for that occurrence, and the user then edits that. Perhaps they discover that the latitude and longitudes have been swapped, so they swap them back, and save the record. The next person to go to that page in GBIF clicks on their bookmarklet and discoveres that there is a potential issue with that record (the popup displayed by the bookmarklet will have a "warning symbol", and an updated map).

Some annotations will be simple, some may require some analysis. For example, a claim that a GenBank sequence has been misidentified would be stronger if it was backed up by a BLAST analysis that demonstrated that the sequence was clustered with taxa that you would not expect based on its putitative identification.

We can also annotate in bulk, and upload these annotations directly to the annotation store. For example, we could map GBIF taxa to taxonomic name identifiers from nomenclators such as ION, ZooBank, IPNI, Index Fungorum, etc., then map those identifiers to the primary litertaure, and upload all of that data to the annotation store, making them available to anyone visiting GBIF (or, indeed, the nomenclators). We could BLAST DNA barcode sequences and suggest potential identifications. We could add lists of publications that cite museum specimen codes, and display those on the GBIF page that corresponds to each code. There is almost no limit to the richness of annotations we could add to existing webpages.

Filtered push


One aspect of annotation that I've glossed over is how the annotations get back to the primary data providers. There has been some work on this (see papers cited at the start), but in a sense I don't think this is the most pressing problem (in part because I suspect most providers are in no position to undertake the kind of data editing and cleaning required). My concern is at the other end of the process. Users of biodiversity data are frequently presented with data that is demonstrably erroneous, and it inconveniences them, as well as hurting the reputation of aggregators such as GBIF, or databases such as GenBank. Anyone doing an analysis of these sorts of data will spend some time cleaning and correcting the data, we desperately need mechanisms to capture these annotations and make them available to other users. The extent to which these annotations filter back to the primary data providers is, in my view, a less pressing issue.

That said, a central annotation store would have lots of advantages for primary providers. It's one place to go to get annotations. The fate of a user's edits could help develop metrics of reliability of annotations, and so on.

Summary


The reason I find this approach attractive is that it frees us from having to wait for projects like GBIF and GenBank to support annotations. We don't need to wait, we can simply do it ourselves right now. We can add overlays that augment existing data (e.g., adding original publications to EOL web pages), or flag errors. Take the example bookmarklet from here for a spin and see what it can do. It's very crude, but I think it gives an indication of the potential of this approach.

So, "all" we need is a centralised, editable, database of annotations that we can hook the bookmarklet into. Simples.

Thursday, March 13, 2014

Publishing biodiversity data directly from GitHub to GBIF

GoogleEarth Image
Today I managed to publish some data from a GitHub repository directly to GBIF. Within a few minutes (and with Tim Robertson on hand via Skype to debug a few glitches) the data was automatically indexed by GBIF and its maps updated. You can see the data I uploaded here.

The data I uploaded came from this paper:

Shapiro, L. H., Strazanac, J. S., & Roderick, G. K. (2006, October). Molecular phylogeny of Banza (Orthoptera: Tettigoniidae), the endemic katydids of the Hawaiian Archipelago. Molecular Phylogenetics and Evolution. Elsevier BV. doi:10.1016/j.ympev.2006.04.006
This is the data I used to build the geophylogeny for Banza using Google Earth. Prior to uploading this data, GBIF had no georeferenced localities for these katydids, now it has 21 occurrences:

DatasetHow it works

I give details of how I did this in the GitHub repository for the data. In brief, I took data from the appendix in the Shapiro et al. paper and created a Darwin Core Archive in a repository in GitHub. Mostly this involved messing with Excel to format the data. I used GBIF's registry API to create a dataset record, pointed it at the GitHub repository, and let GBIF do the rest. There were a few little hiccups, such as needing to tweak the meta.xml file that describes the data, and GBIF's assumption that specimens are identified by the infamous "Darwin Core Triplet" meant I had to invent one for each occurrence, but other than that it was pretty straightforward.

I've talked about using GitHub to help clean up Darwin Core Archives from GBIF, and VertNet are using GitHub as an issue tracker, but what I've done here differs in one crucial way. I'm not just grabbing a file from GBIF and showing that it is broken (with no way to get those fixes to GBIF), nor am I posting bug reports for data hosted elsewhere and hoping that someone will fix it (like VertNet), what I'm doing here is putting data on GitHub and having GBIF harvest that data directly from GitHub. This means I can edit the data, rebuild the Darwin Core Archive file, push it to GitHub, and GBIF will reindex it and update the data on the GBIF portal.

Beyond nodes

GBIF's default publishing model is a federated one. Data providers in countries (such as museums and herbaria) digitise their data and make it available to national aggregators ("nodes"), which typically host a portal with information about the biodiversity of that nation (the Atlas of Living Australia is perhaps the most impressive example). These nodes then make the data available to GBIF, which provides a global portal to the world's biodiversity data (as opposed to national-level access provided by nodes).

This works well if you assume that most biodiversity data is held by national natural history collections, but this is debatable. There are other projects, some of them large and not necessarily "national" that have valuable data. These projects can join GBIF and publish their data. But what about all the data that is held in other databases (perhaps not conventionally thought of as biodiversity databases), or the huge amount of information in the published literature. How does that get into GBIF? People like me who data mine the literature for information on specimens and localities, such as this map of localities mentioned in articles in BioStor. How do we get that data into GBIF?

BiostorData publishing

Being able to publish data directly to GBIF makes putting the effort into publishing data seem less onerous, because I can see it appear in GBIF within minutes. Putting 21 records of katydids is clearly a drop in the ocean, but there is potentially vastly more data waiting to be mined. managing the data on GitHub also makes the whole process of data cleaning and edit transparent. As ever, there are a couple of things that still need to be tackled.

It's who you know

I've been able to do this because I have links with GBIF, and they have made the (hopefully reasonable) assumption that I'm not going to publish just any old crap to GBIF. I still had to get "endorsed" by the UK node (being the chair of the GBIF Science Committee probably helped), and I'm lucky that Tim Roberston was online at the time and guided me through the process. None of this is terribly scalable. It would be nice if we had a way to open up GBIF to direct publishing, but also with a review process built in (even if it's a post-review so that data may have to be pulled if it becomes clear it's problematic). Perhaps this could be managed via GitHub, for example data could be uploaded and managed there, and GBIF can then choose to pull that repository and the data would appear on GBIF. Another model is something like the Biodiversity Data Journal, but that doesn't (as far as I know) have a direct feed into GBIF.

Whichever approach we take, we need a simple, frictionless way to get data into GBIF, especially if we want to tackle the obvious geographic and taxonomic biases in the data GBIF currently has.

DOIs please

It would be great if I could get a DOI for this data set. I had toyed with putting it on Figshare which would give me a DOI, but that just puts an additional layer between GitHub and GBIF. Ideally instead (or as well as) the UUID I get from GBIF to identify the dataset, I'd get a DOI that others can cite, and which would appear on my ORCID profile. I'd also want a way to link the data DOI to the DOI for the source paper (doi:10.1016/j.ympev.2006.04.006), so that citations of the data can pass some of that "link love" to the original authors. So, GBIF needs to mint DOIs for datasets.

Summary

The ability to upload data to GitHub and then have that harvested by GBIF is really exciting. We get great tools for managing changes in data, with a simple publication process (OK, simple if you know Tim, and can speak REST to the GBIF API). But we are getting closer to easy publishing and, just as importantly, easy editing and correcting data.


Monday, March 10, 2014

Displaying a million DNA barcodes on Google Maps using CouchDB

BarcodeFollowing on from the previous post on putting GBIF data onto Google Maps, I'm now going to put DNA barcodes onto Google Maps. You can see the result at http://iphylo.org/~rpage/bold-map/, which displays around 1.2 million barcodes obtained from the International Barcode of Life Project (iBOL) releases. Let me describe how I made it.

Tiles


Typically when people put markers on a Google Map it is done in Javascript using the Google Maps API, and all the work is done by the browser. This works well if you haven't got too many points, but once you have more than, say, a few hundred, the browser struggles to cope. Hence, for something like GBIF or DNA barcodes where we have millions of records we need a different approach. In the GBIF data example I discussed previously I used tiles supplied by GBIF. Tiles are the basis of the "slippy maps" used by Google and others to create the experience of beig able to zoom in and out at any point on the map. At any time, the map you see in the web browser is made up of a small number of images ("tiles") that are typically 256 × 256 pixels in size. At the lowest zoom level (0) the world is represented by a single tile:

WorldTile
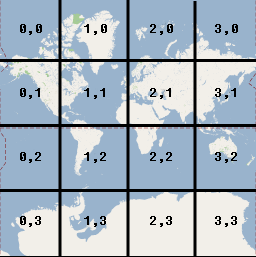
If you zoom in to the next level (1), the world now covers 41=4 tiles, zoom in again and the world now covers 42 = 16 tiles, and so on.

TileCoordinates
At each zoom level the tiles cover a smaller part of the world, and have increasing detail, so the user has the experience of zooming in closer and closer to an ever larger and more detailed map. But the browser only ever has to display enough 256 × 256 pixel tiles to fill the browser window.

Not only can we have tiles for the map of the world, we can also have tiles for data that we want to display on that map. For example, GBIF can create tiles for the hundreds of millions of occurrences in its database, so what looks like a giant map of millions of records is actually just a set of 256 x 256 tiles coloured to represent the number of records at each position on the tile.

DNA Barcodes


I wanted to make a map for DNA barcodes, but unfortunately there aren't any tiles I can use to create the map. So, I set about making my own. Here's what I did. Firstly, I downloaded the DNA barcode data from the BOLD site, and put the barcodes into a CouchDB database hosted by Cloudant. I simply parsed the tab-delimited data files and created a JSON document for each barcode, and stored that in CouchDB.

I then created a view in CouchDB that generated data for each tile. Each zoom level has its own tiles (for zoom level n there are 4n tiles). There's a nice web page on the Open Street Map wiki that describes how to compute slippy map tilenames. Here's the code I use to generate the CouchDB view:


function(doc) {
var tile_size = 256;
var pixels = 4;

if (doc.lat && doc.lon) {

for (var zoom = 0; zoom < 7; zoom++) {

var x_pos = (parseFloat(doc.lon) + 180)/360
* Math.pow(2, zoom);
var x = Math.floor(x_pos);

var relative_x = Math.round(tile_size * (x_pos - x));

var y_pos = (1-Math.log(Math.tan(parseFloat (doc.lat)
* Math.PI/180) + 1/Math.cos(parseFloat(doc.lat)
* Math.PI/180))/Math.PI)/2
* Math.pow(2,zoom);
var y = Math.floor(y_pos);
var relative_y = Math.round(tile_size * (y_pos - y));

relative_x = Math.floor(relative_x / pixels) * pixels;
    relative_y = Math.floor(relative_y / pixels) * pixels;

var tile = [];
tile.push(zoom);
tile.push(x);
tile.push(y);
tile.push(relative_x);
tile.push(relative_y);

emit(tile, 1);
}
}
}

For each zoom level that I support (0 to 6) I convert the latitude and longitude of the DNA barcode sample into the coordinates of the corresponding 256 × 256 tile. I then compute the position of the sample within that tile. This is rounded to the nearest 4 pixels, which is the size of marker I've chosen to display. As an example, the barcode AMSF292-10.COI-5P has location latitude -77.8064, longitude 177.174, which for a zoom level of 6 places it in tile [63,54].

To display the marker I also need to know where in the 256 × 256 tile I should draw the marker. Coordinates in tiles start at the top left corner:

PixelCoordinates
For the example above, the marker would be at x = 124, y = 200. This means that this barcode would have a key of [6, 63, 54, 124, 200] in the CouchDB view computed above. If we ignore the position within the tile, then this barcode belongs on tile [6, 63, 54].

To display the barcodes I added a layer to the Google Map. Whenever a map tile is drawn by Google maps, it calls a simple web service I created, and sends to that service the zoom level and tile coordinates for the tile it wants to draw. I then lookup that key [zoom, x, y] in CouchDB, and return all the points within that tile as a 256 x 256 SVG image. Google Maps then draws that over its own tile, and as a result the user sees both the Google Map and the location of the barcodes. To keep things manageable I only generate tiles down to zoom level 6. After that, the barcodes simply disappear.

So, with some fairly trivial coding, I've created a map tile server in CouchDB that displays over a million barcodes in Google Maps.

Barcodebig

Hit testing


Of course, a map by itself is a bit boring. What you want to do is be able to click on a point and get some more information. If you are using the Google Maps API to add markers, then it's pretty easy to handle user clicks and do something with them. But because I'm using tiles I can't use that approach. Instead what I do is capture any clicks on the map, convert that click to tile coordinates, then query CouchDB to see if any barcodes full within that location. If so, I display them down the right side of the map. It's a bit finicky about where you click on the map, but seems to work. It would be fun to extend this approach to the GBIF map, so that you could click on a point and see what GBIF says is there.

Summary


This is all a bit crude, but as far as I'm aware this is the only interactive map of all DNA barcodes (at least, the publicly available animal barcodes). There's a lot more that could be done with this, but for now it's functional. Take it for a spin at http://iphylo.org/~rpage/bold-map/, I'd welcome any comments. If you are curious about the technical details, the source code is on GitHub at https://github.com/rdmpage/bold-map.

Friday, March 07, 2014

GBIF data overlayed on Google Maps

SquareAs part of a project exploring GBIF data I've been playing with displaying GBIF data on Google Maps. The GBIF portal doesn't use Google Maps, which is a pity because Google's terrain and satellite layers are much nicer than the layers used by GBIF (I gather there are issues with the level of traffic that GBIF receives is above the threshold at which Google starts charging for access).

But because the GBIF developers have a nice API it's pretty easy to put GBIF data on Google maps, like this (the map is live):


The source code for this map is available as a gist, and you can see it live above, and at http://bl.ocks.org/rdmpage/9411457.

Monday, March 03, 2014

GBIF liverwort taxonomy broken

Lunularia cruciataA quick note to myself to document a problem with the GBIF classification of liverworts (I've created issue POR-1879 for this).

While building a new tool to browse GBIF data I ran into a problem that the taxon "Jungermanniales" popped up in two different places in the GBIF classification, which broke a graphical display widget I was using.

If you search GBIF for Jungermanniales you get two results, both listed as "accepted":
Jungermanniales

Plantae > Marchantiophyta > Jungermanniopsida

Jungermanniales

Plantae > Bryophyta > Jungermanniopsida

Based on Wikipedia pages for
Marchantiophyta, traditionally liverworts such as the Jungermanniales were included in the Bryophyta, but are now placed in the Marchantiophyta. The GBIF classification has both the old and the new placement for liverworts (sigh).

As an aside, I couldn't figure out why Wikipedia gave the following as the reference for the publication of the name "Marchantiophyta":
Stotler, R., & Crandall-Stotler, B. (1977). A Checklist of the Liverworts and Hornworts of North America. The Bryologist. JSTOR. doi:10.2307/3242017

This paper doesn't mention "Marchantiophyta" anywhere. The other authority Wikipedia gives is:
Crandall-Stotler, B., Stotler, R. E., Long, D. G., & Goffinet, B. (2001). Morphology and classification of the Marchantiophyta. (A. J. Shaw, Ed.)Bryophyte Biology. Cambridge University Press. doi:10.1017/cbo9780511754807.002

which is behind a paywall that my University doesn't subscribe too. However, the following reference
Stotler, R., & Crandall-Stotler, B. (2008). Correct Author Citations for Some Upper Rank Names of Liverworts (Marchantiophyta). Taxon, 57(1):289-292. jstor:25065970

states that:

Marchantiophyta was validly published (Crandall Stotler & Stotler, 2000) by reference to the Latin description of Hepatophyta in Stotler & Crandall-Stotler (1977:425), a designation formed from an illegitimate generic name, Hepatica Adans. non Mill, and hence not validly published under Article 16.1, cross-referenced in Article 32.1(c) of the ICBN (McNeill & al, 2006). Marchantiophyta phylum nov. is redundant in Doweld (2001) who established a later isonym by likewise citing the Latin description in Stotler & Crandall-Stotler (1977) for his proposed "new name."

And who said taxonomy couldn't be fun?

Wednesday, February 19, 2014

Five Stages of Data Grief

OdiThere is a great post by Jeni Tennison on the Open Data Institute blog entitled Five Stages of Data Grief. It resonates so much with my experience working with biodiversity data (such as building BioNames, or exploring data errors in GBIF) that I've decide to reproduce it here.

Five Stages of Data Grief

by Jeni Tennison (@JeniT)

As organisations come to recognise how important and useful data could be, they start to think about using the data that they have been collecting in new ways. Often data has been collected over many years as a matter of routine, to drive specific processes or sometimes just for the sake of it. Suddenly that data is repurposed. It is probed, analysed and visualised in ways that haven’t been tried before.

Data analysts have a maxim:

If you don’t think you have a quality problem with your data, you haven’t looked at it yet.

Every dataset has its quirks, whether it’s data that has been wrongly entered in the first place, automated processing that has introduced errors, irregularities that come from combining datasets into a consistent structure or simply missing information. Anyone who works with data knows that far more time is needed to clean data into something that can be analysed, and to understand what to leave out, than in actually performing the analysis itself. They also know that analysis and visualisation of data will often reveal bugs that you simply can’t see by staring at a spreadsheet.

But for the people who have collected and maintained such data — or more frequently their managers, who don’t work with the data directly — this realisation can be a bit of a shock. In our last ODI Board meeting, Sir Tim Berners-Lee suggested that the data curators need to go through was something like the five stages of grief described by the Kübler-Ross model.

So here is an outline of what that looks like.

Denial

This can’t be right: there’s nothing wrong with our data! Your analysis/code/visualisation must be doing something wrong.

At this stage data custodians can’t believe what they are seeing. Maybe they have been using the data themselves but never run into issues with it because they were only using it in limiting ways. Maybe they had only ever been collecting the data, and not actually using it at all. Or maybe they had been viewing it in a form where the issues with data quality were never surfaced (it’s hard to spot additional spaces, or even zeros, when you just look at a spreadsheet in Excel, for example).

So the first reason that they reach for is that there must be something wrong with the analysis or code that seems to reveal issues with the data. There may follow a wild goose chase that tries to track down the non-existent bug. Take heart: this exercise is useful in that it can pinpoint the precise records that are causing the problems in the first place, which forces the curators to stop denying them.

Anger

Who is responsible for these errors? Why haven’t they been spotted before?

As the fact that there are errors in the data comes to be understood, the focus can come to rest on the people who collect and maintain the data. This is the phase that the maintainers of data dread (and can be a reason for resisting sharing the data in the first place), because they get blamed for the poor quality.

This painful phase should eventually result in an evaluation of where errors occur — an evaluation that is incredibly useful, and should be documented and kept for the Acceptance phase of the process — and what might be done to prevent them in future. Sometimes that might result in better systems for data collection but more often than not it will be recognised that some of the errors are legacy issues or simply unavoidable without massively increasing the maintenance burden.

Bargaining

What about if we ignore these bits here? Can you tweak the visualisation to hide that?

And so the focus switches again to the analysis and visualisations that reveal the problems in the data, this time with an acceptance that the errors are real, but a desire to hide the problems so that they’re less noticeable.

This phase puts the burden on the analysts who are trying to create views over the data. They may be asked to add some special cases, or tweak a few calculations. Areas of functionality may be dropped in their entirety or radically changed as a compromise is reached between utility of the analysis and low quality data to feed it.

Depression

This whole dataset is worthless. There’s no point even trying to capture this data any more.

As the number of exceptions and compromises grows, and a realisation sinks in that those compromises undermine the utility of the analysis or visualisation as a whole, a kind of despair sets in. The barriers to fixing the data or collecting it more effectively may seem insurmountable, and the data curators may feel like giving up trying.

This phase can lead to a re-examination of the reasons for collecting and maintaining the data in the first place. Hopefully, this process can aid everyone in reasserting why the data is useful, regardless of some aspects that are lower quality than others.

Acceptance

We know there are some problems with the data. We’ll document them for anyone who wants to use it, and describe the limitations of the analysis.

In the final stage, all those involved recognise that there are some data quality problems, but that these do not render the data worthless. They will understand the limits of analyses and interpretations that they make based on the data, and they try to document them to avoid other people being misled.

The benefits of the previous stages are also recognised. Denial led to double-checking the calculations behind the analyses, making them more reliable. Anger led to re-examination of how the data was collected and maintained, and documentation that helps everyone understand the limits of the data better. Bargaining forced analyses and visualisations to be focused and explicit about what they do and don’t show. Depression helped everyone focus on the user needs from the data. Each stage makes for a better end product.


Of course doing data analysis isn’t actually like being diagnosed with a chronic illness or losing a loved one. There are things that you can do to remedy the situation. So I think we need to add a sixth stage to the five stages of data grief described above:

Hope

This could help us spot errors in the data and fix them!

Providing visualisations and analysis provides people with a clearer view about what data has been captured and can make it easier to spot mistakes, such as outliers caused by using the wrong units when entering a value, or new categories created by spelling mistakes. When data gets used to make decisions by the people who capture the data, they have a strong motivation to get the data right. As Francis Irving outlined in his recent Friday Lunchtime Lecture at ODI, Burn the Digital Paper, these feedback loops can radically change how people think about data, and use computers within their organisations.

Making data open for other people to look at provides lots more opportunities for people to spot errors. This can be terrifying — who wants people to know that they are running their organisation based on bad-quality data? — but those who have progressed through the five stages of data grief find hope in another developer maxim:

Given enough eyeballs, all bugs are shallow.

Linus’s Law, The Cathedral and the Bazaar by Eric Raymond

The more people look at your data, the more likely they are to find the problems within it. The secret is to build in feedback mechanisms which allow those errors to be corrected, so that you can benefit from those eyes and increase your data quality to what you thought it was in the first place.


Monday, February 10, 2014

Mark-up of biodiversity literature

UnknownI gave a remote presentation at a proiBioSphere workshop this morning. The slides are below (to try and make it a bit more engaging than a desk of Powerpoints I played around with Prezi).


There is a version on Vimeo that has audio as well.


I sketched out the biodiversity "knowledge graph", then talked about how mark-up relates to this, finishing with a few questions. The question that seems to have gotten people a little agitated is the relative importance of markup versus, say, indexing. As Terry Catapano pointed out, in a sense this is really a continuum. If we index content (e.g., locate a string that is a taxonomic name) and flag that content in the text, then we are adding mark-up (if we don't, we are simply indexing, but even then we have mark-up at some level, e.g. "this term occurs some where on this page"). So my question is really what level of markup do we need to do useful work? Much of the discussion so far has centered around very detailed mark-up (e.g., the kind of thing ZooKeys does to each article). My concern has always been how scalable this is, given the size of the taxonomic literature (in which ZooKeys is barely a blip). It's the usual trade off, do we go for breadth (all content indexed, but little or no mark-up), or do we go for depth (extensive mark-up for a subset of articles)? Where you stand on that trade off will determine to what extent you want detailed mark up, versus whether indexing is "good enough".