Tuesday, May 10, 2016

State of open knowledge about the World's Plants

A1BHupvRKew has released a new report today, entitled the State of the World's Plants, complete with it's own web site https://stateoftheworldsplants.com. Its aim:

...by bringing the available information together into one document, we hope to raise the profile of plants among the global community and to highlight not only what we do know about threats, status and uses, but also what we don’t. This will help us to decide where more research effort and policy focus is required to preserve and enhance the essential role of plants in underpinning all aspects of human wellbeing.

This is, of course, a laudable goal, and a lot of work has gone into this report, and yet there are some things about the report that I find very frustrating.

  1. PDF but no ePub It's nice to have an interactive web site as well as a glossy PDF, but why restrict yourself to a PDF? Why not an ePub so people can view it and rescale fonts for their device, etc. Why not provide the original text in a form people can translate? The report states that much of the newly discovered plant biodiversity is found in Brazil and China, why not make it easier to support automatic translation into Portuguese and Chinese?
  2. Why no DOI for the report? If this is such an important document, why doesn't it have a DOI so it can be easily cited?
  3. Why no DOIs for cited literature? The report cites 219 references, very few of them are accompanied by a DOI, yet most of the references have them. Why not include the DOI so readers can click on that and go straight to the literature. Surely you want to encourage readers to engage with the subject by reading more? The whole point of having digital documents online is that they can link to other documents.
  4. No open access taxonomy Sadly the examples of exciting new plant species discovered are all in closed access publications, including The Gilbertiodendron species complex (Leguminosae: Caesalpinioideae), Central Africa DOI:10.1007/s12225-015-9579-4 published in Kew's own journal Kew Bulletin. This article costs $39.95 / €34.95 / £29.95 to read. Why do taxonomists continue to publish their research, often about taxa in the developing world, behind paywalls?
  5. Why is the data not open? Much of the section on "Describing the world’s plants" uses data from Kew's database IPNI. This database is not open, so how does the reader verify the numbers in the report? Or, more importantly, how does the reader explore the data further and ask questions not asked in the report?

These may seem like small issues given the subject of the report (the perilous state of much of the planet's biodiversity), but if we are to take seriously the goal of "help[ing] us to decide where more research effort and policy focus is required to preserve and enhance the essential role of plants in underpinning all aspects of human wellbeing" then I suggest that open access to knowledge about plant diversity is a key part of that goal.

Over a decade ago Tom Moritz wrote of the need for a "biodiversity commons": DOI:10.1045/june2002-moritz

Provision of free, universal access to biodiversity information is a practical imperative for the international conservation community — this goal should be accomplished by promotion of the Public Domain and by development of a sustainable Biodiversity Information Commons adapting emergent legal and technical mechanisms to provide a free, secure and persistent environment for access to and use of biodiversity information and data. - "Building the Biodiversity Commons" DOI:10.1045/june2002-moritz

The report itself alludes to the importance of "opening up of global datasets with long-time series (such as maps of forest loss)", and yet botany has been slow to do this for much of its data (see Why are botanists locking away their data in JSTOR Plant Science?). We need data on plant taxonomy, systematics, traits, sequences, and distribution to be open and freely available to all, not closed behind paywalls or limited access APIs. Indeed, Donat Agosti has equated copyright to biopiracy (Biodiversity data are out of local taxonomists' reach DOI:10.1038/439392a.

It would be nice to think that Kew, as well as leading the way in summarising the state of the world's plants, would also be leading the way in making that knowledge about those plants open to all.

Wednesday, April 27, 2016

Possible project: Biodiversity dashboard

Mattern 1 dashboard 1020x703 Despite the well deserved scepticism about dashboards voiced by Shannon Mattern @shannonmattern (see Mission Control: A History of the Urban Dashboard, I discovered this by reading Ignore the Bat Caves and Marketplaces: lets talk about Zoning by Leigh Dodds @ldodds) I'm intrigued by the idea a dashboard for biodiversity. We could have several different kinds of information, displayed in a single place.

Immediate information

There are sites such as Global Forest Watch Fires that track events that affect biodiversity and which are haoppoening right now. Some of this data can be harvested (e.g., from the NASA Fire Information for Resource Management System) to show real-time forest fires. Below is an image for the last 24 hours:

We could also have Twitter feeds of these sorts of events

Historical trends

We could have longer-term trends, such as changes in forest cover, or changes in abundance of species over time.

Trends in information

We could have feeds that show us how our knowledge is changing. For example, we could have a map of data from the newest datasets uploaded to GBIF, the lastest DNA barcodes, etc.

As an example, @wikiredlist tweets overtime an article about a species from the IUCN Red List is edited on the English language Wikipedia.

Imagine several such streams, both as lists and as maps. As another example, a while ago I created a visualisation of new species discoveries:

Summary

I'm aware of the irony of drawing inspiration from a critique of dashboards, but I still think there is value in having an overview of global biodiversity. But we shouldn't loose site of the fact that such views will be biassed and constrained, and in many cases it will be much easy to visualise what is going on (or, at least, what our chosen sources reveal) than to effect change on those trends that we find most alarming.

Thursday, April 21, 2016

Searching GBIF by drawing on a map

One of my frustrations with the GBIF portal is that it is hard to drill down and search in a specific area. You have to zoom in and then click for a list of occurrences in the current bounding box of the map. You can't, for example, draw a polygon such as the boundary of a protected area and search within that area.

As a quick and dirty hack I've thrown together a demo of how it would be possible to search GBIF by drawing the search area on a map. Once a shape is drawn, we call GBIF's API to retrieve the first 300 occurrences from that area. The code is here, and below is a live demo (see also http://bl.ocks.org/rdmpage/43073981694598fecab725a16e890d3b).

This demo uses Leaflet.draw to draw shapes, and Wicket to convert the GeoJSON shape to the WKT format required by GBIF's API. I was inspired by the Leaflet.draw plugin with options set demo by d3noob, and used it as a starting point.

Friday, April 15, 2016

GBIF and impact: CrossRef, FundRef, and Altmetric

Wiki hitFor anyone doing research or involved in scientific infrastructure, demonstrating the "impact" of those activities is becoming increasingly important. This has fostered a growth industry in "alt metrics", tools to track how research gathers attention outside academia (of course, we can argue whether attention is the same as impact).

For an organisation such as GBIF there's a clear need to show that it has impact on the field of biodiversity (and beyond), especially to its funders (which are ultimately national governments). To do this GBIF needs to track how its data is used by the research communities, both to do science and to inform policy. This is hard to do, especially if there's a limited culture of data citation. It occurs to me that another way to tackle this problem is to invert it by looking not at the impact of GBIF, but at GBIF as a source of impact.

For a moment let's replace GBIF with Wikipedia. We can ask "what is the impact of Wikipedia on the research community?" For example, Wikipedia is the 8th largest referrer of DOIs, which means that Wikipedia is a major source traffic to academic publishing sites. All those Wikipedia pages which cite the primary literature are driving traffic to those articles.

Conversely, if we regard Wikipedia as important we can use citations of articles in Wikipedia pages as a measure of a researcher's impact. For example, according to Impact story I am "Wikitastic" as 11 Wikipedia pages cite articles that I am an author of (authorship is discovered by using my ORCID 0000-0002-7101-9767).

Likewise, altmetric tracks citations on Wikipedia, so that a paper like the one below may have minimal social media impact but as the gray donut rings signifying that it's been cited on Wikipedia.

JENKINS, P. D., & ROBINSON, M. F. (2002, June). Another variation on the gymnure theme: description of a new species of Hylomys (Lipotyphla, Erinaceidae, Galericinae). Bulletin of The Natural History Museum. Zoology Series. Cambridge University Press (CUP) doi:10.1017/S0968047002000018

Hence, we can look at Wikipedia in two different ways. The first is to ask "what is the impact of Wikipedia?", the second is to assume that Wikipedia has impact, and then use that as one measure of the impact of researchers (how "Wikitastic" you are).

So, let's go back to GBIF. Imagine we leave aside the question of whether GBIF has impact and imagine that we can use GBIF as a measure of impact ("GBIFtastic", sorry, that was unforgivable).

Example 1: From DOI to FundRef to GBIF

In a previous post I discussed the lack of mosquito data in GBIF and how I plugged this gap by using open data cite by a paper in eLife. This paper has the DOI 10.7554/elife.08347 and if I plug that into CrossRef's search engine I can get back some information on the funders of that paper:

Research funded by Sir Richard Southwood Graduate Scholarship | Rhodes Scholarships | National Institutes of Health (RAPIDD program, R01-AI069341, R01-AI091980, R01-GM08322, N01-A1-25489) | Wellcome Trust (#095066, Vecnet, #099872) | National Aeronautics and Space Administration (#NNX15AF36G) | Biotechnology and Biological Sciences Research Council | Bill and Melinda Gates Foundation (#OPP1053338, #OPP52250) | Studienstiftung des Deutschen Volkes | Directorate-General for Research and Innovation (#21803) | European Centre for Disease Prevention and Control (ECDC/09/018)

Now, this gives me a connection between funding agencies, a paper they funded, and the data in GBIF. For example, the Bill and Melinda Gates Foundation (doi:10.13039/100000865) funded doi:10.7554/elife.08347 which generated data in GBIF doi:10.15468/7apj8n.

I suspect that the Bill and Melinda Gates Foundation don't know that they've funded data gathering that has ended up in GBIF, but I suspect they'd be interested. Especially if that could be quantified (een better if we can demonstrate reuse). The process of linking funders to data can be largely automated, especially as more and more papers are now automatically linked to funder information. The link between publications and data in GBIF can be harder to establish, but at least one publisher (Pensoft) has establish a direct feed from publication to GBIF.

So, what if GBIF could computationally discover the funders of the data it holds, and could then communicate that to the funders. I think there's scope here for funders to take an interest in GBIF and it's role in expanding the reuse (and hence impact) of data that funders have paid for. Demonstrating to governments that national funding agencies are supporting research that generates data that ends up in GBIF may help make the case that GBIF is worth supporting.

Example 2: GBIF as altmetric source

The little altmetric donuts that we see on papers require sources of data, such as Twitter, Wikipedia, blogs, etc. For example, the Plant List dataset I recently put into GBIF has a DOI (doi:10.15468/btkum2)and this has received some attention so it has a altimetric donut (wouldn't it be nice if GBIF showed these on dataset pages?):

What if GBIF itself became a source that altimetric scanned when measuring impact? What if having your papers mentioned in GBIF (for example, as a source of distributional data or a taxonomic name) contributed to the visible impact of that work. Wouldn't that encourage people to mobilise their data? Wouldn't that help people discover the wider conversation about the data and associated publications? Wouldn't that help generate more impact for papers that might otherwise gather less attention?

Summary

I realise that I've somewhat avoided the question of the impact of GBIF itself, which is something that also needs to be tackled (and this is one reason why GBIF assigns DOIs to datasets and downloads to support data citation), but I think that may be only a part of the bigger picture. If we assume GBIF is impactful to start with, then I think we can start to think how GBIF can help persuade researchers and funders that contributing to GBIF is a good thing.

The Zika virus, GBIF, and the missing mosquitoes

One of GBIF's goals is to provide up to date, comprehensive data on the distribution of species. Although GBIF's taxonomy and geographic scope is global, not all species are equal, in the sense that the need for information on some species is potentially much more pressing. An example are mosquitoes of the genus Aedes, such as the species A. aegypti and A. albopictus that spread the Zika virus.

Over the last few days I discovered how poor GBIF's coverage of these two vectors is, and a way to fix that gap quickly. Like many things I work on, I stumbled across the problem by accident. GBIF has released a report on whether GBIF data are fit for modeling species distributions. The publicity material included a psychedelic image showing a map for Aedes aegypti from a recent eLife paper by Kraemer et al. (The global distribution of the arbovirus vectors Aedes aegypti and Ae. albopictus http://doi.org/10.7554/elife.08347 ).

Moritz et al 2015 Global Aedes aegypti distribution detail2

Curious, I read the paper and the phrase "GBIF" occurs only once in the text:

we selected 10,000 occurrence records of Aedes species from the Global Biodiversity Information Facility (http://www.gbif.org), omitting all records of Ae. aegypti and Ae. albopictus. This dataset is intended to reflect biases in mosquito reporting in areas which are suitable for Aedes mosquitoes.

So, GBIF data on these two mosquitoes wasn't used. A quick look at what GBIF had for Aedes albopictus and it's not surprising why GBIF data played such a small role:

1651430

Compare this with the data shown in the Scientific Data paper (http://doi.org/10.1038/sdata.2015.35 on the data that underpins the eLife paper.

Sdata201535 f3

Note the striking lack of any GBIF records from Brazil. Fortunately the data collected by Kraemer et al. are freely available in Dryad http://doi.org/10.5061/dryad.47v3c, so I grabbed the files, fussed about with them a bit (https://github.com/rdmpage/global-distribution-arbovirus-vectors) to get them into the format required by GBIF, and uploaded them. Below is the data for Aedes albopictus in GBIF:

1651430 updated

This is looking more like it! If you are more interested in Aedes aegypti then that data is also available.

Questions

This example raises a number of questions:

  1. How come GBIF had such poor data to start with? If GBIF is going to be relevant to people who need biodiversity data, in some cases urgently, then there's an argument to be made that GBIF should be targeting species such as disease vectors that are likely to be in demand in the future.
  2. Why wasn't the latest data in GBIF? One reason GBIF's data was poor is that the relevant data was widely scattered in the literature (Kraemer et al. list over 1000 papers that they looked at, not including the unpublished sources). This clearly requires a lot of effort to assemble. But once assembled, why wasn't it deposited in GBIF? Is it a case of researchers not thinking this would be a useful thing to do, or not knowing how to do it?
  3. What about all the other data out there? This particular example was prompted by me wondering what is that hideous image on the GBIF post, reading the eLife article, wondering where the data was, and having sufficient access to GBIF to simply upload the data. This is clearly not a scalable approach. How can we improve this process? Can we automate harvesting relevant data from repositories such as Dryad so that this data gets fed into GBIF automatically? Should GBIF become a data repository itself so authors can store their data there? And how do we retrospectively harvest all the rest of the data languishing in the scientific literature?

Side note

One aspect of the Kraemer et al. data I've not focussed on is that it is derived from the literature, most of it unpublished, but some is in the primary literature (the list of papers is missing from the Dryad repository but I obtained a copy from Moritz Kraemer (@MOUGK and it's now on github). This means we can link individual occurrence records back to the evidence for that occurrence (i.e., the paper that made the assertion that this species of mosquito is found at this locality). This means we can (a) provide provenance for the data, and (b) provide credit to the authors of that observation. I hope to explore this topic in a subsequent blog post.

References

Kraemer, M. U. G., Sinka, M. E., Duda, K. A., Mylne, A., Shearer, F. M., Brady, O. J., … Hay, S. I. (2015, July 7). The global compendium of Aedes aegypti and Ae. albopictus occurrence. Scientific Data. Nature Publishing Group. http://doi.org/10.1038/sdata.2015.35

Kraemer, Moritz U. G., Sinka, Marianne E., Duda, Kirsten A., Mylne, Adrian, Shearer, Freya M., Brady, Oliver J., … Hay, Simon I. (2015). Data from: The global compendium of Aedes aegypti and Ae. albopictus occurrence. Dryad Digital Repository. http://doi.org/10.5061/dryad.47v3c

Kraemer, M. U., Sinka, M. E., Duda, K. A., Mylne, A. Q., Shearer, F. M., Barker, C. M., … Hay, S. I. (2015, June 30). The global distribution of the arbovirus vectors Aedes aegypti and Ae. albopictus . eLife. eLife Sciences Organisation, Ltd. http://doi.org/10.7554/elife.08347

The Biodiversity Heritage Library at 10: Let's talk impact interview by @UDCMRK

As part of BHL's "Celebrating 10 years of inspiring discovery through free access to biodiversity knowledge" at the NHM and Kew Gardens in London, I was interviewed by Martin Kalfatovic (@UDCMRK). We chatted about BHL, the work I've been doing on BioStor, and the future of BHL. I haven't had the courage to watch it myself, but if you want to watch an academic giving Roger Hyam a run for his money in the "flappy hands" stakes, and not knowing whether to look at the camera, Martin, or towards the distant horizon, then here is the video.

Friday, April 08, 2016

Guest post: 10 explanations for messy data, by Bob Mesibov

The follow is a guest post by Bob Mesibov, who has contributed to iPhylo before. Bob

Like many iPhylo readers, I deal with large, pre-existing compilations of biodiversity data. The compilations come from museums, herbaria, aggregation projects and government agencies. For simplicity in what follows and to avoid naming names, I'll lump all these sources into a single fictional entity, the PAI (for Projects, Agencies and Institutions).

The datasets I get from the PAI typically contain duplicate records, inconsistencies in content and format, unexplained data gaps, data in wrong fields, fields improperly used, no flagging of doubtful data, etc. Data cleaning consumes most of the time I spend on a data project. Cleaning can take weeks, analysing the cleaned data takes minutes, reporting the results of the analysis takes hours or days. (Example: doi:10.3897/BDJ.2.e1160)

I can understand how datasets get messy. Data entry errors account for a lot of the problems I see, and I make data entry errors myself. But the causes of messiness are one thing and its cure is another. The custodians of those data compilations don't seem to have done much (or any) data checking. Why not?

When I'm brave enough to ask that question, I usually get a polite response from the PAI. Here are 10 explanations I've heard for inadequate data checking and cleaning:

(1) The data are fit for use, as-is. No cleaning is needed, because the data are fit for some use, and the PAI is satisfied with that. One data manager wrote to me in an email: '...even records with lower certainty, in this case an uncertain identification, can be useful at a coarser resolution. Although we have no idea as to the reliability of the identification to the species or even genus they are likely correctly identify[ing] something as at least an animal, arthropod and possibly to class so the record is suitable for analysis at that level.'

(2) The PAI is exposing its data online. The crowd will spot any problems and tell the PAI about them.

I've previously pointed out (doiL10.3897/zookeys.293.5111) how lame this explanation is. As a strategy for data cleaning it's slow, piecemeal and wildly optimistic. At best, it accumulates data-cleaning 'tickets' with no guarantee that any will ever be closed. What I hear from the PAI is 'We're aware of problems of that kind and are hoping to find a general solution, rather than deal with a multitude of individual cases'. Years pass and the individual cases don't get fixed, so interested members of the crowd lose faith in the process and stop reporting problems.

(3) No one outside the PAI is allowed to look at the whole dataset, and no one inside the PAI has the time (or skills) to do data checking and cleaning.

This is a particularly nice Catch-22. I once offered to check a portion of the PAI's data holdings for free, and was told that PAI policy was that the dataset was not to be shared with anyone outside the PAI. The same data were freely available on the PAI's website in bits and pieces through a database search page.

(4) The PAI is migrating to new database software next year. Data cleaning will be part of the migration.

No, it won't. Note that this response isn't always simple procrastination, because it's sometimes the case that the PAI's database has only limited capabilities for data checking and editing. PAI staff are hopeful that checking and editing will be easier with the new software. They'll be disappointed.

(5) The person who manages data is on leave / was seconded to another project / resigned and hasn't been replaced yet / etc.

This is another way of saying that no one inside the PAI has the time to do data checking and cleaning. When the data manager returns to work or gets replaced, data checking and cleaning will have the same low priority it had before. That's why it didn't get done.

(6) Top management says any data cleaning would have to be done by outside specialists, but there's not enough money in the current budget to hire such people.

Not only a Catch-22, but a solid, long-term excuse, applicable in any financial year. It would cost less to train PAI staff to do the job in-house.

(7) The PAI would prefer to use a specialist data tool to clean data, like OpenRefine, but hasn't yet got up to speed on its use.

The PAI believes in magic. OpenRefine will magically clean the data without any thought required on the part of PAI staff. The magic will have to be applied repeatedly, because the sources of the duplications, gaps and errors haven't been found and squashed.

(8) The PAI staff best qualified to check and clean the data aren't allowed to do so.

IT policy strictly forbids anyone but IT staff from tinkering with the PAI database, whose integrity is sacrosanct. A very specific request from biodiversity staff may be ticketed by IT staff for action, but global checking and editing is out of the question. IT staff are not expected to understand biodiversity studies, and biodiversity staff are not expected to understand databases.

This explanation is interesting because it implies a workaround. If a biodiversity staffer can get a dump from the database as a simple text file, she can do global checking and editing of the data using the command line or a spreadsheet. The cleaned data can then be passed to IT staff for incorporation into the database as replacement data items. The day that happens, pigs will be seen flying outside the PAI windows.

(9) The PAI datasets have grown so big that global data checking and editing is no longer possible.

Harder, yes; impossible, no. And the datasets didn't suddenly appear, they grew by accretion. Why wasn't data checking and editing done as data was added?

(10) All datasets are messy and data users should do their own data cleaning.

The PAI shrugs its shoulders and says 'That's just the way it is, live with it. Our data are no messier than anyone else's'.

I've left this explanation for last because it begs the question. Yes, users can do their own data cleaning — because it's not that hard and there are many ways to do it. So why isn't it done by highly qualified, well-paid PAI data managers?

Towards a biodiversity knowledge graph now in RIO

E2asamswAfter experimenting with a dynamic, online version of my notes "Towards a biodiversity knowledge graph" I've published a static version in RIO: doi:10.3897/rio.2.e8767.

Friday, March 18, 2016

The Plant List, GBIF, and the primary literature

TL;DR; The Plant List is now in GBIF http://doi.org/10.15468/btkum2.

Readers of this blog may recall that I've had a somewhat jaundiced view of The Plant List. The first version was release with a Creative Commons Attribution-NonCommercial-NoDerivs (CC BY-NC-ND) license which allowed copying so long as didn't create a derived work (The Plant List: nice data, shame it's not open). This is frankly about the silliest possible license for a data set as, from my perspective, the whole reason for releasing data is so that it can be combined and enhanced with other data.

The second release (version 1.1) dropped an explicit CC license in favour of almost the reverse position (!). You can't copy the list "as is" without permission, but you can make derivative works "without prior written permission from us" (see Terms of Use for The Plant List). Progress, of a sort.

So, for the last week I've been working on getting a version of The Plant List into GBIF, and I've finally managed to achieve this. There's isn't a single place you can grab the whole plant list, so you have to scrape the web site for CSV files, then glue them together. I would could argue that converting the data into the Darwin Core Archive is a derived work, but in case this seems not derivative enough (of course, nobody seems ready to define just what "derived" actually means) I started to augment the list of names by adding bibliographic identifiers. I've long argued (see e.g. Surfacing the deep data of taxonomy) that a fundamental limitation of existing taxonomic database is that they don't explicitly link to the primary literature. This is why I built BioNames, and why I've been working to link the "micro citations" in IPNI to identifiers such as DOIs, JSTOR likes, BioStor URLs and BHL page links (see project on github). So, I've added about 120,000 DOIs and JSTOR links to names in the plant list. This is a subset of the links I've found for IPNI, but for this first release I've tried to keep things simple. I've also made the link between Plant List name and DOI/JSTOR via the IPNI identifier for a name, and the Plant List has ommitted quite a few IPNI ids for reasons which aren't clear.

The Plant List version I've created is available in GBIF (http://doi.org/10.15468/btkum2 and http://www.gbif.org/dataset/d9a4eedb-e985-4456-ad46-3df8472e00e8). Having another list of plant names will be a useful addition to the checklists that GBIF already has, even if the Plant List is already somewhat out of date.

DOIs

One feature of enhanced Plant List in GBIF is that for a subset of names (currently about 10%) there are direct links to the original publication of that name. For example, the record for Haniffia albiflora in the Plant List has a fairly cryptic bibliographic citation Nordic J. Bot. 20: 287 2000 and no link to that publication. In the version I've uploaded to GBIF the name Haniffia albiflora looks like this: Haniffia Note the full citation. But more importantly, the Publisher record link is the DOI http://doi.org/10.1111/j.1756-1051.2000.tb00745.x so clicking on it takes you to the original description of this species: Doi4 There is a lot of plant taxonomic literature available in JSTOR, sadly most of it (along with specimen images) behind a paywall (see Why are botanists locking away their data in JSTOR Plant Science?). Some of the links from GBIF take you to JSTOR: Doi3 The DOI landscape is evolving, and there are now multiple DOI registration agencies minting DOIs for scientific papers. CrossRef provides easily the best services for discovery and metadata harvesting, other agencies often have no equivalent, which makes it hard to discover DOIs for those papers hard. I've spent some time getting this information for Chinese and Taiwanese articles, e.g. http://dx.doi.org/10.6165/tai.1985.30.5: Doi1 and http://dx.doi.org/10.3969/j.issn.2095-0845.2005.04.002: Doi2 to give two example of articles that are now linked to from the corresponding species page in GBIF.
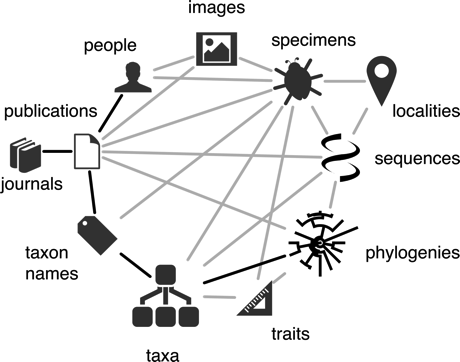
It's all about the links To reiterate, I believe that one of the key challenges facing biodiversity informatics is cross linking between disparate types of data and source of information. At the moment most of our data resides in disconnected silos. The links I'm adding to plant names are a small step, but they can lead to all sorts of possibilities. For example, users of GBIF can click on a link and see the original paper. If, for example, GBIF doesn't have a map for the species discussed in that paper, it's likely that the paper may have some information (e.g., the type locality). If users click on the links, then that is going to drive more traffic to the original literature, thus increasing its visibility. Furthermore, now that we have a taxon identifier (from GBIF) linked to a bibliographic identifier, we can go in the opposite direction. Earlier I proposed a Javascript bookmarklet as a way to augment the information on a web page (see Rethinking annotating biodiversity data). We could have a popup on a article web page that can tell the user about the taxa mentioned in that paper. If GBIF has a ma for those taxa, we can immediately place that paper in a geospatial context (e.g., Africa). This is barely scratching the surface of what is possible once we start breaking out of silos and share deeply linked data.

Monday, March 14, 2016

Towards a biodiversity knowledge graph

TL;DR; In order to build a usable biodiversity knowledge graph we should adopt JSON-LD for biodiversity data, develop reconciliation services to match entities to identifiers, and a use a mixture of document and graph databases to store and query the data. To bootstrap this project we can create wrappers around each biodiversity data provider, and a central cache that is both a document store and a simple graph database. This power of this approach should be showcased by applications that use the central cache to tackle specific problems, such as augmenting existing data.
Fig 1 full

I’ve thrown together some notes on building a biodiversity knowledge graph, and in the interests of making it interactive it's in the form of a web page: http://bionames.org/~rpage/towards-knowledge-graph/. There are buttons to click that display live data, and I hope to dd more examples as I flesh out the ideas. I'm hoping to have a fully-functioning live demo that can be used to explore the notion of a knowledge graph and demonstrate what we can do with it. It will be pretty obvious that this is all a bit crude, but my goal is to try and sketch out a fully-functioning system that can create and query the graph, and support interesting applications.

Thursday, March 03, 2016

Cisco Pit Stop: Digitising the Natural History Museum’s collections

Last week (25-26 February) I was in London for CISCO Pit Stop event. Thursday evening was at the Natural History Museum where I gave a talk extolling the virtues of linking stuff together:

My slides are here:

Friday we assembled at the Digital Catapult Centre, which as Sandy Knapp notes, has some amazing views from it's 9th floor.

A group of experts (loosely defined, at least, if they include me in that category) and small businesses (with backgrounds in digitisation, text-mining, publishing, etc.) got together to try and come up with workable ideas where we could marry issues in digitisation and subsequent use of that data with tools and markets. A fascinating experience, although I'm not yet sure what the outcome will be. But it's always useful talking (and listening) to people with very different backgrounds and notions of what matters (and what is possible).

iSpecies meets TreeBASE

I'm continuing to play with the new version of iSpecies, seeing just how far one can get by simply grabbing JSON from various sources and mashing them up. Since the Open Tree of Life is pretty unresolved ("OMG it's full of stars") I've started to grab trees from TreeBASE and add those. Sadly TreeBASE is showing it's age and doesn't have a JSON API, so I had to break my rule of only using HTML and Javascript in iSpecies and I had to write some PHP wrappers to talk to TreeBASE. Now, when you search for a genus or species you may see a list of studies from TreeBASE, and a popup menu where you can select a tree to view.

Below is a example (searching for the plant genus Fitzalania). Ispecies treebase

This example shows one reason phylogenies are useful. Although GBIF (which supplies the data for the map) recognises Fitzalania, a recent study in TreeBASE shows that this renders Meiogyne paraphyletic, and so moves the Fitzalania to Meiogyne. Hence GBIF's taxonomy is somewhat behind the current state of knowledge about these plants.

The paper merging these two genra (doi:10.1600/036364414x680825) also shows up in the CrossRef results. Unfortunately TreeBASE doesn't have the DOI for the paper, so linking these two results (the TreeBASE study and the corresponding paper) will require some work. This is another reason why I'm playing with iSpecies: I want to see how many identifiers we can uncover to connect results from different sources, and how many cross links we need to add before it all comes together in a nice linked graph of data.

Wednesday, February 03, 2016

Bootstrapping the biodiversity knowledge graph with JSON-LD

In a recent Twitter conversation including David Shorthous and myself (and other poor souls who got dragged in) we discussed how to demonstrate that adopting JSON-LD as a simple linked-data friendly format might help bootstrap the long awaited "biodiversity knowledge graph" (see below for some suggestions for keeping JSON-LD simple). David suggests partnering with "Three small, early adopting projects". I disagree.

I think we need to approach this problem, not from the perspective of who would like to try this approach, but what would it take to really be useful? I think if we look at the structure of the biodiversity knowledge graph and look at who has what identifiers, we can gain some insight into what the next steps are.

Sinks

A fundamental problem is that many data providers are essentially dead ends in terms of building a network. They have data, but no connections, and so they are "sinks". A data browser goes there and can't go any further, it has to retrace its steps and go somewhere else. For example, your typical museum might serve up its collection data like this: Museum The museum has its own identifiers (e.g., a URL) and that's the only identifier in the data. Nomenclators are much the same: Nomen You get a nomenclator-specific identifier such as an LSID, but no other identifiers. Once again, if you are a data-crawler traversing the web of data, this is a dead end. (This is why I've become obsessed with linking nomenclators to the primary literature, I want to stop them being dead ends).

Connected sources

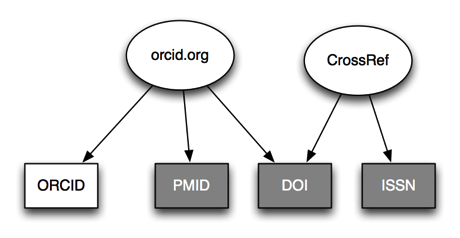
Then there are sources which have at least one external identifier, that is, an identifier that they themselves don't control. For example, CrossRef manages DOIs for articles, but if you get metadata for a DOI you also get an ISSN (identifying a journal): Crossref Now we have a connection to an external source of data, and some we can traverse the data graph further, which means we can start asking questions (such as how many articles in this journal have DOIs?).

Another connected source is ORCID: Orcid This gives us identifiers for authors (the ORCID) linked to article identifiers such as DOIs and PubMed ids (PMID). Follow the DOI to CrossRef and we can link people to articles to journals. Oc
Another connected source is the NCBI: Ncbi NCBI has several internal identifiers (PMIDs, GenBank accession numbers, tax_ids) all of which lead to rich resources, and it's possible to get a lot of information by staying within NCBI's own silo, but there are external links such as DOIs (usually found attached to PubMed articles or to GenBank accessions) and links to external records such as DNA barcodes in BOLD.
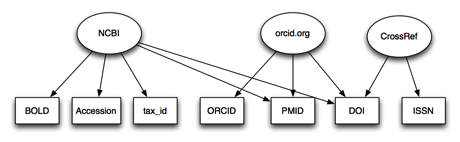
Lets join CrossRef, ORCID, and NCBI together: All Now we have a bipartite graph linking sources with identifiers. We can imagine playing a game where we try and connect different entities by moving through the graph. For example, we could take an author identified by an ORCID, follow a DOI to a PMID, a PMID to a set of accessions numbers, and then be able to list all the sequences that an author has published. We could also step back and ask questions about which identifiers are the most useful in terms of making connections between different sources, and which sources provide the most cross links.

Filling in the gaps

Now, the graph above is obviously incomplete. I've restricted it to a few of the key services that I'm familiar with, and make use of external identifiers. One of the big obstacles to fleshing out the biodiversity knowledge graph is the frequent lack of reuse of identifiers. It's not enough to pump out data in linked-data form, you need to build the links. And not just "same as" style links connecting multiple identifiers for the same thing, you need to connect identifiers for different things. Until we tackle that, linked data approaches will not deliver much in the way of value. Hence we need sources that provide genuinely linked data by reusing exiting, external identifiers. If we have name in a nomenclator with a citation string, it needs to link that dumb literature string to a DOI. If we have a taxon concept, it needs to link the name of that taxon to a name in a nomenclator. If we have a specimen that has been sequenced, it needs to give the accession number of that sequence.

From this perspective, choosing which kinds of data with which to explore JSON-LD and a linked data graph should be driven by how connected those sources are: the more connected the more interesting the questions that we can ask. Sadly the vast majority of biodiversity data providers don't provide the kind of connected data we need, which means we continually pay lip service to linked data without feeding it the kind of data it needs in order to grow.

* Notes on JSON-LD

It is relatively easy to write horrible JSON-LD, so I think it would be useful to strive to make it as simple and as human-readable as possible (ignoring the @context block which is always going to be awful, this is the price we pay for simplicity elsewhere). To this end I think we should do at least the following:

  1. No URLs as identifiers URLs are ugly, and they are not reliable as identifiers. Providers can change URLs, even for persistent identifiers. The DOI prefix has changed from http://dx.doi.org/ to the preferred http://doi.org/, and the rise of HTTPS (prompted by concerns about security, among other issues, see Google's motives, part 2) is going to break a lot of older URLs (see Web Security - "HTTPS Everywhere" harmful). These changes keep happening, so lets try and shield ourselves from these by using standard prefixes for identifiers (such as 'DOI') for a DOI. Put all the alternative URL resolver prefixes in the @context block and use prefixes such as those standardised by http://identifiers.org (which basically formalises what many people in bioinformatics have been doing for a while).
  2. No prefixes for keys In other words, no CURIEs. Don't write "dwc:CatalogueNumber", just write "CatalogueNumber". I don't want to be told where the term comes from (that's what @context is for). If you have a namespace clash (i.e., two terms that are the same unless you include the namespace) then IMHO you're doing it wrong. Either you're using more than one vocabulary for the same thing (why?), or you've not modelling the data at the appropriate level of granularity. Either way, let's avoid clutter and keep things simple and readable.

Monday, January 25, 2016

iSpecies is back: mashing up species data

A decade ago (OMG, that can't be right, an actual decade ago) I created "iSpecies", a simple little tool to mashup a variety of data from GBIF, NCBI, Yahoo, Wikipedia, and Google Scholar to create a search engine for species. It was written in PHP, relied on some degree of *cough* web scraping to get its data, and was a bit of a toy (although that didn't stop me complaining that it could do more than EOL at the time). Eventually I got sick of dealing with Google Scholar constantly changing it's HTML and blocking IP addresses to stop people harvesting data (I once managed to get my entire campus blocked), or services disappearing such as Yahoo's image search, and I eventually pulled the plug on it.

A short course I run on "phyloinformatics" starts this week and one of the examples I show is a crude Javascript-based mashup. It struck me that I could tweak that and recreate a simple version of iSpecies, and that's exactly what I've done: http://ispecies.org.

Ispecies

It's nothing fancy, just takes a species name and searches GBIF, EOL, CrossRef, and Open Tree of Life, grabs some data and puts it together on a web page. There are lots of limitations (e.g., only fetches the first 300 localities in GBIF, requires scientific names, tree viewer is pretty awful) but it was pretty simple to put together. It's entirely client-side based, the code is all in the HTML file (and a few Javascript libraries) (the code is on GitHub: https://github.com/rdmpage/ispecies).

Fun as this was, there's a bigger problem with iSpecies and that's that it is a "mashup". I'm simply grabbing data from different sources and redisplaying it. What I really want is what has been described as a "mashup" (awful term, don't use it), that is, I want to combine the data so that it is more than the sum of its parts. For example, some of the data could be cross linked (especially if add a few more sources and we drill down a bit). Some of the papers discovered by CrossRef may include original descriptions, or may be the source of some of the points plotted on the GBIF map. Some may include the phylogenies used to build the Open Tree of Life tree. In order to build a data mashup instead of a web mashup we need to operate at the level of data rather than just human-readable web pages. That is the next thing I'd like to work on, and in many ways it shouldn't be a big leap. The new iSpecies was fairly easy to create because we now have a bunch of web services that all speak JSON. It's a small step from JSON to JSON-LD (especially if the JSON-LD is constructed with reuse in mind). So while it's nice to see iSpecies back, there's a much more interesting next step to think about.

Wednesday, January 13, 2016

Surfacing the deep data of taxonomy

My paper "Surfacing the deep data of taxonomy" (based on a presentation I gave in 2011) has appeared in print as part to a special issue of Zookeys:

Page, R. (2016, January 7). Surfacing the deep data of taxonomy. ZooKeys. Pensoft Publishers. http://doi.org/10.3897/zookeys.550.9293
The manuscript was written shortly after the talk, but as is the nature of edited volumes it's taken a while to appear.

My tweet about the paper sparked some interesting comments from David Shorthouse.

This is an appealing vision, because it seems unlikely that having multiple, small communities clustered around taxa will ever have the impact that taxonomists might like to have. Perhaps if we switch to focussing on objects (sequences, specimens, papers), notions of identity (e.g., DOIs, ORCID), and alternative measures of impact we can increase the visibility and perceived importance of the field. In this context, the recent paper "Wikiometrics: A Wikipedia Based Ranking System" http://arxiv.org/abs/1601.01058 looks interesting. A big consideration will be how connected is the network connecting taxonomists, papers, sequences, specimens, and names. If it's anything like the network of readers in Mendeley then we may face some challenges in community building around such a network.

Thursday, December 17, 2015

Will JSON, NoSQL, and graph databases save the Semantic Web?

OK, so the title is pure click bait, but here's the thing. It seems to me that the Semantic Web as classically conceived (RDF/XML, SPARQL, triple stores) has had relatively little impact outside academia, whereas other technologies such as JSON, NoSQL (e.g., MongoDB, CouchDB) and graph databases (e.g., Neo4J) have got a lot of developer mindshare.

In biodiversity informatics the Semantic Web has been a round for a while. We've been pumping out millions of RDF documents (mostly served by LSIDs) since 2005 and, to a first approximation, nothing has happened. I've repeatedly blogged about why I think this is (see this post for a summary).

I was an early fan of RDF and the Semantic Web, but soon decided that it was far more hassle than it was worth. The obsession with ontologies, the problems of globally unique identifiers based on HTTP (http-14 range, anyone?), the need to get a lot of ducks in a row all mad it a colossal pain. Then I discovered the NoSQL document database CouchDB, which is a JSON store that features map-reduce views rather than on the fly queries. To somebody with a relational database background this is a bit of a headfuck:

Fault tolerance

But CouchDB has a great interface, can be replicated to the cloud, and is FUN (how many times can you say that about a database?). So I starting playing with CouchDB for small projects, then used it to build BioNames and more recently moved BioStor to CouchDB hosted both locally and in the cloud.

Then there are graph databases such as Neo4J, which has some really cool things such as GraphGists which is a playground where you can create interactive graphs and query them (here's an example I created). Once again, this is FUN.

Another big trend over the last decade is the flight from XML and its hideous complexities (albeit coupled with great power) to the simplicity of JSON (part of the rise of JavaScript). JSON makes it very easy to pass around data in simple key-value documents (with more complexity such as lists if you need them). Pretty much any modern API will serve you data in JSON.

So, what happened to RDF? Well, along with a plethora of formats (XML, triples, quads, etc., etc.) it adopted JSON in the form of JSON-LD (see JSON-LD and Why I Hate the Semantic Web for background). JSON-LD lets you have data in JSON (which both people and machines find easy to understand) and all the complexity/clarity of having the data clearly labelled using controlled vocabularies such as Dublin Core and schema.org. This complexity is shunted off into a "@context" variable where it can in many cases be safely ignored.

But what I find really interesting is that instead of JSON-LD being a way to get developers interested in the rest of the Semantic Web stack (e.g. HTTP URIs as identifiers, SPARQL, and triple stores), it seems that what it is really going to do is enable well-described structured to get access to all the cool things being developed around JSON. For example, we have document databases such as CouchDB which speaks HTTP and JSON, and search servers such as ElasticSearch which make it easy to work with large datasets. There are also some cool things happening with graph databases and Javascript, such as Hexastore (see also Weiss, C., Karras, P., & Bernstein, A. (2008, August 1). Hexastore. Proc. VLDB Endow. VLDB Endowment. http://doi.org/10.14778/1453856.1453965, PDF here) where we create the six possible indexes of the classic RDF [subject,predicate,object] triple (this is the sort of thing can also be done in CouchDB). Hence we can have graph databases implemented in a web browser!

So, when we see large-scale "Semantic Web" applications that actually exist and solve real problems, we may well be more likely to see technologies other than the classic Semantic Web stack. As an example, see the following paper:

Szekely, P., Knoblock, C. A., Slepicka, J., Philpot, A., Singh, A., Yin, C., … Ferreira, L. (2015). Building and Using a Knowledge Graph to Combat Human Trafficking. The Semantic Web - ISWC 2015. Springer Science + Business Media. http://doi.org/10.1007/978-3-319-25010-6_12

There's a free PDF here, and a talk online. The consortium behind this project researchers did extensive text mining, data cleaning and linking, creating a massive collection of JSON-LD documents. Rather than use a triple store and SPARQL, they indexed the JSON-LD using ElasticSearch (notice that they generated graphs for each of the entities they care about, in a sense denormalising the data).

I think this is likely to be the direction many large-scale projects are going to be going. Use the Semantic Web ideas of explicit vocabularies with HTTP URIs for definitions, encode the data in JSON-LD so it's readable by developers (no developers, no projects), then use some of the powerful (and fun) technologies that have been developed around semi-structured data. And if you have JSON-LD, then you get SEO for free by embedding that JSON-LD in your web pages.

In summary, if biodiversity informatics wants to play with the Semantic Web/linked data then it seems obvious that some combination of JSON-LD with NoSQL, graph databases, and search tools like ElasticSearch are the way to go.

Wednesday, December 09, 2015

Visualising the difference between two taxonomic classifications

It's a nice feeling when work that one did ages ago seems relevant again. Markus Döring has been working on a new backbone classification of all the species which occur in taxonomic checklists harvested by GBIF. After building a new classification the obvious question arises "how does this compare to the previous GBIF classification?" A simple question, answering it however is a little tricky. It's relatively easy to compare two text files -- and this function appears in places such as Wikipedia and GitHub -- but comparing trees is a little trickier. Ordering in trees is less meaningful than in text files, which have a single linear order. In other words, as text strings "(a,b,c)" and "(c,b,a)" are different, but as trees they are the same.

Classifications can be modelled as a particular kind of tree where (unlike, say, phylogenies) every node has a unique label. For example, the tips may be species and the internal nodes may be higher taxa such as genera, families, etc. So, what we need is a way of comparing two rooted, labelled trees and finding the differences. Turns out, this is exactly what Gabriel Valiente and I worked on in this paper doi:10.1186/1471-2105-6-208. The code for that paper (available on GitHub) computes an "edit script" that gives a set of operations to convert one fully labelled tree into another. So I brushed up my rusty C++ skills (I'm using "skills" loosely here) and wrote some code to take two trees and the edit script, and create a simple web page that shows the two trees and their differences. Below is a screen shot showing a comparison between the classification of whales in the Mammals Species of the World, and one from GBIF (you can see a live version here).

Treediff

The display uses colours to show whether a nodes has been deleted from the first tree, inserted into the second tree, or moved to a different position. Clicking on a node in one tree scrolls the corresponding node in the other tree (if it exists) to scroll into view. Most of the differences between the two trees are due to the absence of fossils from Mammals Species of the World, but there are other issues such as GBIF ignoring tribes, and a few taxa that are duplicated due to spelling typos, etc.

Tuesday, December 01, 2015

Frontiers of biodiversity informatics and modelling species distributions #GBIFfrontiers @AMNH videos

For those of you who, like me, weren't at the "Frontiers Of Biodiversity Informatics and Modelling Species Distributions" held at the AMNH in New York, here are the videos of the talks and panel discussion, which the organisers have kindly put up on Vimeo with the following description:

The Center for Biodiversity and Conservation (CBC) partnered with the Global Biodiversity Information Facility (GBIF) to host a special "Symposium and Panel Discussion: Frontiers Of Biodiversity Informatics and Modelling Species Distributions" at the American Museum of Natural History on November 4, 2015.

The event kicked off a working meeting of the GBIF Task Group on Data Fitness for Use in Distribution Modelling at the City College of New York on November 5-6. GBIF convened the Task Group to assess the state of the art in the field, to connect with the worldwide scientific and modelling communities, and to share a vision of how GBIF support them in the coming decade.

The event successfully convened a broad, global audience of students and scientists to exchange ideas and visions on emerging frontiers of biodiversity informatics. Using inputs from the symposium and from a web survey of experts, the Data Fitness task group will prepare a report, which will be open for consultation and feedback at GBIF.org and on the GBIF Community Site in December 2015.

Guest post: 10 years of global biodiversity databases: are we there yet?

YtNkVT2UThis guest post by Tony Rees explores some of the themes from his recent talk 10 years of Global Biodiversity Databases: Are We There Yet?.

A couple of months ago I received an invitation to address the upcoming 2015 meeting of the Malacological Society of Australasia (Australian and New Zealand mollusc persons for the uninitiated) on some topic associated with biodiversity databases, and I decided that a decadal review might be an interesting exercise, both for my potential audience (perhaps) and for my own interest (definitely). Well, the talk is delivered and the slides are available on the web for viewing if interested, and Rod has kindly invited me to present some of its findings here, and possibly stimulate some ongoing discussion since a lot of my interests overlap his own quite closely. I was also somewhat influenced in my choice of title by a previous presentation of Rod's from some 5 years back, "Why aren't we there yet?" which provides a slightly pessimistic counterpoint to my own perhaps more optimistic summary.

I decided to construct the talk around 5 areas: compilations of taxonomic names and associated valid/accepted taxa; links to the literature (original citations, descriptions, more); machine-addressable lists of taxon traits; compilations of georeferenced species data points such as OBIS and GBIF; and synoptic efforts in the environmental niche modelling area (all or many species so as to be able to produce global biodiversity as well as single-species maps). Without recapping the entire content of my talk (which you can find on SlideShare), I thought I would share with readers of this blog some of the more interesting conclusions, many of which are not readily available elsewhere, at least not with effort to chase down and/or make educated guesses.

In the area of taxonomic names, for animals (sensu lato) ION has gone up from 1.8m to 5.2m names (2.8m to 3.5m indexed documents) from all ranks (synonyms not distinguished) over the cited period 2005-2015, while Catalogue of Life has gone up from 0.5m species names + ?? synonyms to 1.6m species names + 1.3m synonyms over the same period; for fossils, BioNames database is making some progress in linking ION names to external resources on the web but, at less than 100k such links, is still relatively small scale and without more than a single-operator level of resourcing. A couple of other "open access" biological literature indexing activities are still at a modest level (e.g. 250k-350k citations, as against an estimated biological literature of perhaps 20m items) at present, and showing few signs of current active development (unless I have missed them of course).

Comprehensive databases of taxon traits (in machine addressable form) appear to have started with the author’s own "IRMNG" genus- and species- level compendium which was initially tailored to OBIS needs for simply differentiating organisms into extant vs. fossil, marine vs. nonmarine. More comprehensive indexes exist for specific groups and recently, Encyclopedia of Life has established "TraitBank" which is making some headway although some of the "traits" such as geographic distribution (a bounding box from either GBIF or OBIS) and "number of GenBank sequences" stretch the concept of trait a little (just my two cents' worth, of course), and the newly created linkage to Google searches is to be applauded.

With regard to aggregating georeferenced species data (specimens and observations), both OBIS (marine taxa only) and GBIF (all taxa) have made quite a lot of progress over the past ten years, OBIS increasing its data holdings ninefold from 5.6m to 44.9m (from 38 to 1,900+ data providers) and GBIF more than tenfold from 45m to 577m records over the same period, from 300+ to over 15k providers. While these figures look healthy there are still many data gaps in holdings e.g. by location sampled, year/season, ocean depth, distance to land etc. and it is probably a fair question to ask what is the real "end point" for such projects, i.e. somewhere between "a record for every species" and "a record for every individual of every species", perhaps...

Global / synoptic niche modelling projects known to the author basically comprise Lifemapper for terrestrial species and AquaMaps for marine taxa (plus some freshwater). Lifemapper claims "data for over 100,000 species" but it is unclear whether this corresponds to the number of completed range maps available at this time, while AquaMaps has maps for over 22,000 species (fishes, marine mammals and invertebrates, with an emphasis on fishes) each of which has a point data map, a native range map clipped to where the species is believed to occur, an "all suitable habitat map" (the same unclipped) and a "year 2100 map" showing projected range changes under one global warming scenario. Mapping parameters can also be adjusted by the user using an interactive "create your own map" function, and stacking all completed maps together produces plots of computed ocean biodiversity plus the ability to undertake web-based "what [probably] lives here" queries for either all species or for particular groups. Between these two projects (which admittedly use different modelling methodologies but both should produce useful results as a first pass) the state of synoptic taxon modelling actually appears quite good, especially since there are ongoing workshops e.g. the recent AMNH/GBIF workshop Biodiversity Informatics and Modelling Species Distributions at which further progress and stumbling blocks can be discussed.

So, some questions arising:

  • Who might produce the best "single source" compendium of expert-reviewed species lists, for all taxa, extant and fossil, and how might this happen (my guess: a consortium of Catalogue of Life + PaleoBioDB at some future point)
  • Will this contain links to the literature, at least citations but preferably as online digital documents where available? (CoL presently no, PaleoBioDB has human-readable citations only at present)
  • Will EOL increasingly claim the "TraitBank" space, and do a good enough job of it? (also bearing in mind that EOL is still an aggregator, not an original content creator, i.e. somebody still has to create it elsewhere)
  • Will OBIS and/or GBIF ever be "complete", and how will we know when we’ve got there (or, how complete is enough for what users might require)?
  • Same for niche modelling/predicted species maps: will all taxa eventually be covered, and will the results be (generally) reliable and useable (and at what scale); or, what more needs to be done to increase map quality and reliability.

Opinions, other insights welcome!

Wednesday, November 18, 2015

Comments on "Widespread mistaken identity in tropical plant collections"

Zoë A. Goodwin (@Drypetes) and collegagues have published a paper with a title guaranteed to get noticed:

Goodwin, Z. A., Harris, D. J., Filer, D., Wood, J. R. I., & Scotland, R. W. (2015, November). Widespread mistaken identity in tropical plant collections. Current Biology. Elsevier BV. http://doi.org/10.1016/j.cub.2015.10.002http://doi.org/10.1016/j.cub.2015.10.002

Their paper argues that "more than half of all tropical plant collections may be wrongly named." This is clearly a worrying conclusion with major implications for aggregators such as GBIF that get the bulk of their data (excluding birds) from museums and herbaria.

I'm quite prepared to accept that there are going to be considerable problems with herbarium and museum labels, but there are aspects of this study that are deeply frustrating.

Where's the data?

The authors don't provide any data! This difficult to understand, especially as they downloaded data from GBIF which provides DOIs for each and every download. Why don't the authors cite those DOIs (which would enable others to grab the same data, and also ultimately provides a way to provide credit to the original data providers)? The authors obtained data from multiple herbaria, matched specimens that were the same, and compared their taxonomic names. This is a potentially very useful data set, but the authors don't provide it. Anybody wanting to explore the problem immediately hits a brick wall.

Unpublished taxonomy

The first group of plants the authors looked at is Aframomum, and they often refer to a recent monograph of this genus which is cited as "Harris, D.J., and Wortley, A.H. (In Press). Monograph of Aframomum (Zingiberaceae). Syst. Bot. Monogr.". As far as I can tell, this hasn't been published. This not only makes it hard for the reader to investigate further, it means the authors mention a name in the paper that doesn't seem to be have been published:
In 2014 the plant was recognized as a new species, Aframomum lutarium D.J.Harris & Wortley, by Harris & Wortley as part of the revision of the genus Aframomum
I confess ignorance of the Botanical Code of Nomenclature, but in zoology this is a no no.

What specimen is show in Fig. 1?

Gr1 lrg Figure 1 shows a herbarium specimen, but there's no identifier or link for the specimen. Is this specimen available online? Can I see it in GBIF? Can I see it's history and explore further? if not, why not? If it's not available online, why not pick one that is?

What is "wrong"?

The authors state:
Examination of the 560 Ipomoea names associated with 49,500 specimens in GBIF (Figure S1A) revealed a large proportion of the names to be nomenclatural and taxonomic synonyms (40%), invalid, erroneous or unrecognised names (16%, ‘invalid’ in Figure S1A). In addition, 11% of the specimens in GBIF were unidentified to species.
Are synonyms wrong? If it's a nomenclatural synonym, then it's effectively the same name. If it's a taxonomic synonym, then is that "wrong"? Identifications occur at a given time, and our notion of what constitutes a taxon can change over time. It's one thing to say a specimen has been assigned to a taxon which we now regard as a synonym of another, quite another to say that a specimen has been wrongly identified. What are "invalid, erroneous or unrecognised names"? Are these typos, or genuinely erroneous names? Once again, if the authors provided the data we could investigate. But they haven't, so we can't examine whether their definition of "wrong" is reasonable.

I'm all for people flagging problems (after all, I've made something of career of it), but surely one reason for flagging problems is so that they can be recognised and fixed. By basing their results on an unpublished monograph, and by not providing any data in support of their conclusions, the authors prevent those of us interested in fixing problems being able to drill down and understand the nature of the problem. If the authors had both published the article and provided the data they would have done the community a real service. Instead we are left with a study with a click bait title that will get lots of attention, but which doesn't provide any way for people to make progress on the problem the paper identifies.