Showing posts sorted by date for query bob mesibov. Sort by relevance Show all posts

Friday, September 11, 2020

Darwin Core Million reminder, and thoughts on bad data

Bob mesibovThe following is a guest post by Bob Mesibov.

No winner yet in the second Darwin Core Million for 2020, but there are another two and a half weeks to go (to 30 September). For details of the contest see this iPhylo blog post. And please don’t submit a million RECORDS, just (roughly) a million DATA ITEMS. That’s about 20,000 records with 50 fields in the table, or about 50,000 records with 20 fields, or something arithmetically similar.


The purpose of the Darwin Core Million is to celebrate high-quality occurrence datasets. These are extraordinarily rare in biodiversity informatics.

I’ll unpick that. I’m not talking about the accuracy of the records. For most records, the “what”, “where”, “when” and “by whom” are probably correct. An occurrence record is a simple fact: Wilma Flintstone collected a flowering specimen of an Arizona Mountain Dandelion 5 miles SSE of Walker, California on 27 June 2019. More technically, she collected Agoseris parviflora at 38.4411 –119.4393, as recorded by her handheld GPS.

What could possibly go wrong in compiling a dataset of simple records like that in a spreadsheet or database? Let me count a few of the ways:

  • data items get misspelled or misnumbered
  • data items get put in the wrong field
  • data items are put in a field for which they are invalid or inappropriate
  • data items that should be entered get left out
  • data items get truncated
  • data items contain information better split into separate fields
  • data items contain line breaks
  • data items get corrupted by copying down in a spreadsheet
  • data items disagree with other data items in the same record
  • data items refer to unexplained entities (“habitat type A”)
  • paired data items don’t get paired (e.g. latitude but no longitude)
  • the same data item appears in different formats in different records
  • missing data items are represented by blanks, spaces, “?”, “na”, “-”, “unknown”, “not recorded” etc, all in the same data table
  • character encoding failures create gibberish, question marks and replacement characters (�)
  • weird control characters appear in data items, and parsing fails
  • dates get messed up (looking at you, Excel)
  • records get duplicated after minor edits

In previous blog posts (here and here) I’ve looked at explanations for poor-quality data at the project, institution and agency level — data sources I referred to collectively as the “PIA”. I don’t think any of those explanations are controversial. Here I’m going to be rude and insulting and say there are three further obstacles to creating good, usable and shareable occurrence data:

Datasets are compiled as though they were family heirlooms.

The PIA says “This database is OUR property. It’s for OUR use and WE understand the data, even if it’s messy and outsiders can’t figure out what we’ve done. Ambiguities? No problem, we’ll just email Old Fred. He retired a few years back but he knows the system back to front.”

Prising data items from these heirlooms, mapping them to new fields and cleaning them are complicated exercises best left to data specialists. That’s not what happens.

Datasets are too often compiled by people with inadequate computer skills. Their last experience of data management was building a spreadsheet in a “digital learning” class. They’re following instructions but they don’t understand them. Both the data enterers and their instructors are hoping for a good result, which is truly courageous optimism.

The (often huge) skills gap between the compilers of digital PIA data and the computer-savvy people who analyse and reformat/repackage the data (users and facilitators-for-users) could be narrowed programmatically, but isn’t. Hands up all those who use a spreadsheet for data entry by volunteers and have comprehensive validation rules for each of the fields? Thought so.

People confuse software with data. This isn’t a problem restricted to biodiversity informatics, and I’ve ranted about this issue elsewhere. The effect is that data compilers blame software for data problems and don’t accept responsibility for stuff-ups.

Sometimes that blaming is justified. As a data auditor I dread getting an Excel file, because I know without looking that the file will have usability and shareability issues on top of the usual spreadsheet errors. Excel isn’t an endpoint in a data-use pipeline, it’s a starting point and a particularly awful one.

Another horror is the export option. Want to convert your database of occurrence records to format X? Just go to the “Save as” or “Export data” menu item and click “OK”. Magic happens and you don’t need to check the exported file in format X to see that all is well. If all is not well, it’s the software’s fault, right? Not your problem.

In view of these and the previously blogged-about explanations for bad data, it’s a wonder that there are any high-quality datasets, but there are. I’ve audited them and it’s a shame that for ethical reasons I can’t enter them myself in the current Darwin Core Million.

Monday, August 10, 2020

Australian museums and ALA

Bob mesibovThe following is a guest post by Bob Mesibov.

The Atlas of Living Australia (ALA) adds "assertions" to Darwin Core occurrence records. "Assertions" are indicators of particular data errors, omissions and questionable entries, such as "Coordinates are transposed", "Geodetic datum assumed WGS84" and "First [day] of the century".

Today (8 August 2020) I looked at assertions attached to records in ALA for non-fossil animals in the Australian State museums. There were 62 occurrence record collections from the seven museums (I lumped the two Tasmanian museums together), with 45 different assertions. I then calculated assertions per record for each collection. The worst performer was the Queensland Museum Porifera collection (3.84 ass/rec), and tied for best were the Museums Victoria Herpetology and Ichthyology collections (1.09 ass/rec).

I also aggregated museum collections to build a kind of league table by State:

The clear winner is Museums Victoria.

But how well do ALA's assertions measure the quality of data records? Not all that well, actually.

  • The tests used to make the assertions generate false positives and false negatives, although at a low rate
  • The tests aren't independent, so that a single data error can "smear" across several assertions
  • The tests ignore errors and omissions in DwC fields that many data users would consider important

ALA's assertions also have a strong spatial/geographical bias, with 23 of the 45 assertions in my sample dataset saying something about the "where" of the occurrence. Looking just at those 23 "where" assertions, the museums league table again shows Museums Victoria ahead, this time by a wide margin:

ALA is currently working on better ways for users to filter out records with selected assertions, in what's misleadingly called a "Data Quality Project". The title is misleading because the overall quality of ALA's holdings doesn't improve one bit. Getting data providers to fix their data issues would be a more productive way to upgrade data quality, but I haven't seen any evidence that Australian museums (for example) pay much attention to ALA's assertions. (There are no or minimal changes in assertion totals between data updates.)

It's been pointed out to me that that museum and herbarium records amount to only a small fraction of ALA's ca 90 million records, and that citizen scientists are growing the stock of occurrence records far faster than institutions do. True, and those citizen science records are often of excellent quality (see https://www.datafix.com.au/BASHing/2020-02-05.html). However, citizen science observations are strongly biased towards widespread and common species. ALA's records for just six common Australian birds (5,072,599 as of 8 August 2020; https://dashboard.ala.org.au/) outnumber all the museum animal records I looked at in the assertion analysis (4,669,508).

In my humble view, the longer ALA's institutional data providers put off fixing their mistakes, the less valuable ALA becomes as a bridge between biodiversity informatics and biodiversity science.


Wednesday, July 15, 2020

Darwin Core Million now twice a year

Bob mesibovThe following is a guest post by Bob Mesibov.

The first Darwin Core Million closed on 31 March with no winner. Since I'm seeing better datasets this year in my auditing work for Pensoft, I've decided to run the competition every six months.

Missed the first Darwin Core Million and don't know what it's about? Don't get too excited by the word "million". It refers to the number of data items in a Darwin Core occurrences table, not to the prize!

The rules

  • Anyone can enter, but the competition applies only to publicly available Darwin Core occurrence datasets. These might have been uploaded to an aggregator, such as GBIF, ALA or iDigBio, or to an open-data repository.
  • Select about one million data items from the dataset. That could be 50000 records in 20 populated Darwin Core fields, or 20000 records in 50 populated Darwin Core fields, or something in between. Email the dataset to me after 1 September and before 30 September as a zipped, plain-text file, together with a DOI or URL for the online version of the dataset.
  • I'll audit datasets in the order I receive them. If I can't find serious data quality problems (see below) in your dataset, I'll pay your institution AUD$150 and declare your institution the winner of the Darwin Core Million here on iPhylo. There's only one winner in each competition round; datasets received after the first problem-free dataset won't be checked.
  • If I find serious data quality problems, I'll let you know by email. If you want to learn what the problems are, I'll send you a report detailing what should be fixed and charge your institution AUD$150. At 0.3-0.75c/record, that's a bargain compared to commercial data-checking rates. And it would be really good to hear, later on, that those problems had indeed been fixed and that corrected data items had replaced the originals online.

How the data are judged

For a list of data quality problems, see this page in my Data Cleaner's Cookbook. The key problems I look for are:

  • duplicate records
  • invalid data items
  • missing-but-expected items
  • data items in the wrong fields
  • data items inappropriate for their field
  • truncated data items
  • records with items in one field disagreeing with items in another
  • character encoding errors
  • wildly erroneous dates or coordinates
  • incorrect or inconsistent formatting of dates, names and other items

This is not just nit-picking. Your digital data items aren't mainly for humans to read and interpret, they're intended in the first place for parsing and managing by computers. "Western Hill" might not be the same as "Western Hill" in processing, for example, because the second placename might have a no-break space between the words instead of a plain space. Another example: humans see these 22 variations on collector names as "the same", but computers don't.

Please also note that data quality isn't the same as data accuracy. Is Western Hill really at those coordinates? Is the specimen ID correct? Is the barely legible collector name on the specimen label correctly interpreted? These are questions about data accuracy. But it's possible to have entirely correct digital data that can't be processed by an application, or moved between applications, because the data suffer from one or more of the problems listed above.

Fine points

I think I'm pretty reasonable about the "serious" in "serious data quality problems". One character encoding error, such as "L'H?rit" repeated in the "scientificNameAuthorship" field, isn't serious, but multiple errors scattered through several fields are grounds for rejection.

For an understanding of "invalid", please refer to the Darwin Core field definitions and recommendations.

"Missing-but-expected" is important. I've seen GBIF mis-match a scientific name because the Darwin Core "kingdom" field was left blank by the data provider, even though all the other higher-taxon fields were filled in.

Please remember, entries received before 1 September won't be audited.

Monday, March 23, 2020

Darwin Core Million promo: best and worst

Bob mesibovThe following is a guest post by Bob Mesibov.
There's still time (to 31 March) to enter a dataset in the 2020 Darwin Core Million, and by way of encouragement I'll celebrate here the best and worst Darwin Core datasets I've seen.
The two best are real stand-outs because both are collections of IPT resources rather than one-off wonders.


The first is published by the Peabody Museum of Natural History at Yale University. Their IPT website has 10 occurrence datasets totalling ca 1.6M records updated daily, and I've only found minor data issues in the Peabody offerings. A recent sample audit of the 151,138 records with 70 populated Darwin Core fields in the botany dataset (as of 2020-03-18) showed refreshingly clean data:
  • entries correctly assigned to DwC fields
  • no missing-but-expected entry gaps
  • consistent, widely accepted vocabularies and formatting in DwC fields
  • no duplicate records
  • no character encoding errors
  • no gremlin characters
  • no excess whitespace or fancy alternatives to simple ASCII characters
The dataset isn't perfect and occurrenceRemarks entries are truncated at 254 characters, but other errors are scarce and easily fixed, such as
  • 14 records with plant taxa mis-classified as animals
  • 4 records with dateIdentified earlier than eventDate
  • minor pseudo-duplication in several fields, e.g. "Anna Murray Vail; Elizabeth G. Britton" and "Anne Murray Vail; Elizabeth G. Britton" in recordedBy
  • minor content errors in some entries, e.g. "tissue frozen; tissue frozen" and "|" (with no other characters in the entry).
I doubt if it would take more than an hour to fix all the Peabody Museum issues besides the truncation one, which for an IPT dataset with 10.5M data items is outstanding. There are even fields in which the Museum has gone beyond what most data users would expect. Entries in vernacularName, for example, are semicolon-separated hierarchies of common names: "dwarf snapdragon; angiosperms; tracheophytes; plants" for Chaenorhinum minus.

The second IPT resource worth commending comes from GBIF Portugal and consists of 108 checklist, occurrence record and sampling event datasets. As with the Peabody resource, the datasets are consistently clean with only minor (and scattered) structural, format or content issues.

The problems appearing most often in these datasets are "double-encoding" errors with Portugese words and no-break spaces in place of plain spaces, and for both of these we can probably blame the use of Windows programs (like Excel) at the contributing institutions. An example of double-encoding: the Portugese "prôximo" is first encoded in UTF-8 as a 2-byte character, then read by a Windows program as two separate bytes, then converted back to UTF-8, resulting in the gibberish "prôximo". A large proportion of the no-break spaces in the Portugese datasets unfortunately occur in taxon name strings, which don't parse correctly and which GBIF won't taxon-match.

And the worst dataset? I've seen some pretty dreadful examples from around the world, but the UK's Natural History Museum sits at the top of my list of delinquent providers. The NHM offers several million records and a disappointingly high proportion of these have very serious data quality problems. These include invalid and inappropriate entries, disagreements between fields and missing-but-expected blanks.

Ironically, the NHM's data portal allows the visitor to select and examine/download records with any one of a number of GBIF issues, like "taxon_match_none". Further, for each record the data portal reports "GBIF quality indicators", as shown in this screenshot:


Clicking on that indicator box gives the portal visitor a list of the things that GBIF found wrong with the record (a list that overlaps incompletely with the list I can find with a data audit). I'm sure the NHM sees this facility differently, but to me it nicely demonstrates that NHM has prioritised Web development over data management. The message I get is
"We know there's a lot wrong with our data, but we're not going to fix anything. Instead, we're going to hand our mess as-is to any data users out there, with cleverly designed pointers to our many failures. Suck it up, people."
In isolation NHM might be seen as doing what it can with the resources it has. In a broader context the publication of multitudes of defective records by NHM is scandalous. Institutions with smaller budgets and fewer staff do a lot better with their data — see above.

Coronavirus

If your institution is closed and you have spare work-from-home time, consider doing some data cleaning. For those not afraid of the command line, I've archived the websites A Data Cleaner's Cookbook (version 2) and its companion blog BASHing data (first 100 posts) in Zenodo with local links between the two, so that the two resources can be downloaded and used offline in any Web browser.

Tuesday, March 03, 2020

The 2020 Darwin Core Million

Bob mesibovThe following is a guest post by Bob Mesibov.

You're feeling pretty good about your institution's collections data. After carefully tucking all the data items into their correct Darwin Core fields, you uploaded the occurrence records to GBIF, the Atlas of Living Australia (ALA) or another aggregator, and you got back a great report:

  • all your scientific names were in the aggregator's taxonomic backbone
  • all your coordinates were in the countries you said they were
  • all your dates were OK (and in ISO 8601 format!)
  • all your recorders and identifiers were properly named
  • no key data items were missing

OK, ready for the next challenge for your data? Ready for the 2020 Darwin Core Million?

How it works

From the dataset you uploaded to the aggregator, select about one million data items. That could be, say, 50000 records in 20 populated Darwin Core fields, or 20000 records in 50 populated Darwin Core fields, or something in between. Send me the data for auditing before 31 March 2020 as a zipped plain-text file by email to robert.mesibov@gmail.com, together with a DOI or other identifier for their online, aggregated presence.

I'll audit datasets in the order I receive them. If I can't any find data quality problems in your dataset, I'll pay your institution AUD$150 and declare your institution the winner of the 2020 Darwin Core Million here on iPhylo. (One winner only; datasets received after the first problem-free dataset won't be checked.)

If I find data quality problems, I'll let you know by email. If you want to learn what the problems are, I'll send you a report detailing what should be fixed and you'll pay me AUD$150. At 0.3-0.75c/record, that's a bargain compared to commercial data-checking rates. And it would be really good to hear, later on, that those problems had indeed been fixed and corrected data had been uploaded to the aggregator.

What I look for

For a list of data quality problems, see this page in my Data Cleaner's Cookbook. The key problems are:

  • duplicate records
  • invalid data items
  • data items in the wrong fields
  • data items inappropriate for their field
  • truncated data items
  • records with items in one field disagreeing with items in another
  • character encoding errors
  • wildly erroneous dates or coordinates
  • incorrect or inconsistent formatting of dates, names and other data
  • items

If you think some of this is just nit-picking, you're probably thinking of your data items as things for humans to read and interpret. But these are digital data items intended for parsing and managing by computers. "Western Hill" might not be the same as "Western Hill" in processing, for example, because the second item might have a no-break space between the words instead of a plain space. Another example: humans see these 22 variations on collector names as "the same", but computers don't.

You might also be thinking that data quality is all about data correctness. Is Western Hill really at those coordinates? Is the specimen ID correct? Is the barely legible collector name on the specimen label correctly interpreted? But it's possible to have entirely correct digital data that can't be processed by an application, or moved between applications, because the data suffer from one or more of the problems listed above.

I think my money is safe

The problems I look for are all easily found and fixed. However, as mentioned in a previous iPhylo post, the quality of the many institutional datasets that I've sample-audited ranges from mostly OK to pretty awful. I've also audited more than 100 datasets (many with multiple data tables) for Pensoft Publishers, and the occurrence records among them were never error-free. Some of those errors had vanished when the records had been uploaded to GBIF, because GBIF simply deleted the offending data items during processing (GBIF, bless 'em, also publish the original data items).

Neither institutions nor aggregators seem to treat occurrence records with the same regard for detail that you find in real scientific data, the kind that appear in tables in scientific journal articles. A comparison with enterprise data is even more discouraging. I'm not aware of any large museum or herbarium with a Curator of Data on the payroll, probably because no institution's income depends on the quality of the institution's data, and because collection records don't get audited the way company records do, for tax, insurance and good-governance purposes.

So there might be a winner this year, but I doubt it. Maybe next year. ALA has a year-long data quality project underway, and GBIF Executive Secretary Joe Miller (in litt.) says that GBIF is now paying closer attention to data quality. The 2021 Darwin Core Million prize could be yours...

Tuesday, September 11, 2018

Guest post - Quality paralysis: a biodiversity data disease

Bob mesibovThe following is a guest post by Bob Mesibov.

In 2005, GBIF released Arthur Chapman's Principles of Data Quality and Principles and Methods of Data Cleaning: Primary Species and Species-Occurrence Data as freely available electronic publications. Their impact on museums and herbaria has been minimal. The quality of digitised collection data worldwide, to judge from the samples I've audited (see disclaimer below), varies in 2018 from mostly OK to pretty awful. Data issues include:

  • duplicate records
  • records with data items in the wrong fields
  • records with data items inappropriate for a given field (includes Chapman's "domain schizophrenia")
  • records with truncated data items
  • records with items in one field disagreeing with items in another
  • character encoding errors and mojibake
  • wildly erroneous dates and spatial coordinates
  • internally inconsistent formatting of dates, names and other data items (e.g. 48 variations on "sea level" in a single set of records)

In a previous guest post I listed 10 explanations for the persistence of messy data. I'd gathered the explanations from curators, collection managers and programmers involved with biodiversity data projects. I missed out some key reasons for poor data quality, which I'll outline in this post. For inspiration I'm grateful to Rod Page and to participants in lively discussions about data quality at the SPNHC/TDWG conference in Dunedin this August.

  1. Our institution, like all natural history collections these days, isn't getting the curatorial funding it used to get, but our staff's workload keeps going up. Institution staff are flat out just keeping their museums and herbaria running on the rails. Staff might like to upgrade data quality, but as one curator wrote to me recently, "I simply don't have the resources necessary."
  2. We've been funded to get our collections digitised and/or online, but there's nothing in the budget for upgrading data quality. The first priority is to get the data out there. It would be nice to get follow-up funding for data cleaning, but staff aren't hopeful. The digitisation funder doesn't seem to think it's important, or thinks that staff can deal with data quality issues later, when the digitisation is done.
  3. There's no such thing as a Curator of Data at our institution. Collection curators and managers are busy adding records to the collection database, and IT personnel are busy with database mechanics. The missing link is someone on staff who manages database content. The bigger the database, the greater the need for a data curator, but the usual institutional response is "Get the collections people and the IT people together. They'll work something out."
  4. Aggregators act too much like neutrals. We're mobilising our data through an aggregator, but there are no penalties if we upload poor-quality data, and no rewards if we upload high-quality data. Our aggregator has a limited set of quality tests on selected data fields and adds flags to individual records that have certain kinds of problems. The flags seem to be mainly designed for users of our data. We don't have the (time/personnel/skills) to act on this "feedback" (or to read those 2005 GBIF reports).

There's a 15th explanation that overlaps the other 14 and Rod Page has expressed it very clearly: there's simply no incentive for anyone to clean data.

  • Museums and herbaria don't get rewards, kudos, more visitors, more funding or more publicity if staff improve the quality of their collection data, and they don't get punishments, opprobrium, fewer visitors, reduced funding or less publicity if the data remain messy.
  • Aggregators likewise. Aggregators also don't suffer when they downgrade the quality of the data they're provided with.
  • Users might in future get some reputational benefit from alerting museums and herbaria to data problems, through an "annotation system" being considered by TDWG. However, if users clean datasets for their own use, they get no reward for passing blocks of cleaned data to overworked museum and herbarium staff, or to aggregators, or to the public through "alternative" published data versions.

With the 15 explanations in mind, we can confidently expect collection data quality to remain "mostly OK to pretty awful" for the foreseeable future. Data may be upgraded incrementally as loans go out and come back in, and as curators, collection managers and researchers compare physical holdings one-by-one with their digital representations. Unfortunately, the improvements are likely to be overwhelmed by the addition of new, low-quality records. Very few collection databases have adequate validation-on-entry filters, and staff don't have time for, or assistance with checking. Or a good enough reason to check.

"Quality paralysis" is endemic in museums and herbaria and seems likely to be with us for a long time to come.


DISCLAIMER: Believe it or not, this post isn't an advertisement for my data auditing services.

I began auditing collection data in 2012 for my own purposes and over the next few years I offered free data auditing to a number of institutions in Australia and elsewhere. There were no takers.

In 2017 I entered into a commercial arrangement with Pensoft Publishers to audit the datasets associated with data papers in Pensoft journals, as a free Pensoft service to authors. Some of these datasets are based on collections data, but when auditing I don't deal with the originating institutions directly.

I continue to audit publicly available museum and herbarium data in search of raw material for my website A Data Cleaner's Cookbook and its companion blog BASHing data. I also offer free training in data auditing and cleaning.

Wednesday, January 24, 2018

Guest post: The Not problem

Bob mesibovThe following is a guest post by Bob Mesibov.

Nico Franz and Beckett Sterner created a stir last year with a preprint in bioRxiv about expert validation (or the lack of it) in the "backbone" classifications used by aggregators. The final version of the paper was published this month in the OUP journal Database (doi:10.1093/database/bax100).

To see what effect "backbone" taxonomies are having on aggregated occurrence records, I've recently been auditing datasets from GBIF and the Atlas of Living Australia. The results are remarkable, and I'll be submitting a write-up of the audits for formal publication shortly. Here I'd like to share the fascinating case of the genus Not Chan, 2016.

I found this genus in GBIF. A Darwin Core record uploaded by the New Zealand Arthropod Collection (NZAC02015964) had the string "not identified on slide" in the scientificName field, and no other taxonomic information.

GBIF processed this record and matched it to the genus Not Chan, 2016, which is noted as "doubtful" and "incertae sedis".

There are 949 other records of this genus around the world, carefully mapped by GBIF. The occurrences come from NZAC and nine other datasets. The full scientific names and their numbers of GBIF records are:

NumberName
2Not argostemma
14not Buellia
1not found, check spelling
1Not given (see specimen note) bucculenta
1Not given (see specimen note) ortoni
1Not given (see specimen note) ptychophora
1Not given (see specimen note) subpalliata
1not identified on slide
1not indentified
1Not known not known
1Not known sp.
1not Lecania
4Not listed
873Not naturalised in SA sp.
18Not payena
5not Punctelia
18not used
6Not used capricornia Pleijel & Rouse, 2000

GBIF cites this article on barnacles as the source of the genus, although the name should really be Not Chan et al., 2016. A careful reading of this article left me baffled, since the authors nowhere use "not" as a scientific name.

Next I checked the Catalogue of Life. Did CoL list this genus, and did CoL attribute it to Chan? No, but "Not assigned" appears 479 times among the names of suprageneric taxa, and the December 2018 CoL checklist includes the infraspecies "Not diogenes rectmanus Lanchester,1902" as a synonym.

The Encyclopedia of Life also has "Not" pages, but these have in turn been aggregated on the "EOL pages that don't represent real taxa" page, and under the listing for the "Not assigned36" page someone has written:

This page contains a bunch of nodes from the EOL staff Scratchpad. NB someone should go in and clean up that classification.

"Someone should go in and clean up that classification" is also the GBIF approach to its "backbone" taxonomy, although they think of that as "we would like the biodiversity informatics community and expert taxonomists to point out where we've messed up". Franz and Sterner (2018) have also called for collaboration, but in the direction of allowing for multiple taxonomic schemes and differing identications in aggregated biodiversity data. Technically, that would be tricky. Maybe the challenge of setting up taxonomic concept graphs will attract brilliant developers to GBIF and other aggregators.

Meanwhile, Not Chan, 2016 will endure and aggregated biodiversity records will retain their vast assortment of invalid data items, character encoding failures, incorrect formatting, duplications and truncated data items. In a post last November on the GitHub CoL+ pages I wrote:

Being old and cynical, I can speculate that in the time spent arguing the "politics" of aggregation in recent years, a competent digital librarian or data scientist would have fixed all the CoL issues and would be halfway through GBIF's. But neither of those aggregators employ digital librarians or data scientists, and I'm guessing that CoL+ won't employ one, either.

Monday, September 18, 2017

Guest post: Our taxonomy is not your taxonomy

Bob mesibov The following is a guest post by Bob Mesibov.

Do you know the party game "Telephone", also known as "Chinese Whispers"? The first player whispers a message in the ear of the next player, who passes the message in the same way to a third player, and so on. When the last player has heard the whispered message, the starting and finishing versions of the message are spoken out loud. The two versions are rarely the same. Information is usually lost, added or modified as the message is passed from player to player, and the changes are often pretty funny.

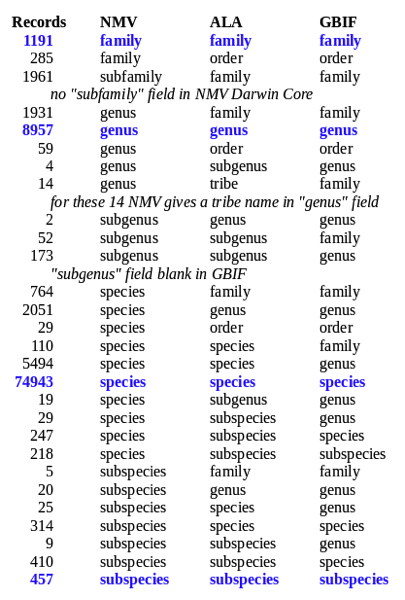
I recently compared ca 100 000 beetle records as they appear in the Museums Victoria (NMV) database and in DarwinCore downloads from the Atlas of Living Australia (ALA) and the Global Biodiversity Information Facility (GBIF). NMV has its records aggregated by ALA, and ALA passes its records to GBIF. The "Telephone" effect in the NMV to ALA to GBIF comparison was large and not particularly funny.

Many of the data changes occur in beetle names. ALA checks the NMV-supplied names against a look-up table called the National Species List, which in this case derives from the Australian Faunal Directory (AFD). If no match is found, ALA generalises the record to the next higher supplied taxon, which it also checks against the AFD. ALA also replaces supplied names if they are synonyms of an accepted name in the AFD.

GBIF does the same in turn with the names it gets from ALA. I'm not 100% sure what GBIF uses as beetle look-up table or tables, but in many other cases their GBIF Backbone Taxonomy mirrors the Catalogue of Life.

To give you some idea of the magnitude of the changes, of ca 85000 NMV records supplied with a genus+species combination, about one in five finished up in GBIF with a different combination. The "taxonRank" changes are summarised in the overview below, and note that replacement ALA and GBIF taxon names at the same rank are often different:

Generalised

Of the species that escaped generalisation to a higher taxon, there are 42 names with genus triples: three different genus names for the same taxon in NMV, ALA and GBIF.

Just one example: a paratype of the staphylinid Schaufussia mona Wilson, 1926 is held in NMV. The record is listed under Rytus howittii (King, 1866) in the ALA Darwin Core download, because AFD lists Schaufussia mona as a junior subjective synonym of Tyrus howitti King, 1866, and Tyrus howittii in AFD is in turn listed as a synonym of Rytus howittii (King, 1866). The record appears in GBIF under Tyraphus howitti (King, 1865), with Rytus howittii (King, 1866) listed as a synonym. In AFD, Rytus howittii is in the tribe Tyrini, while Tyraphus howitti is a different species in the tribe Pselaphini.

ALA gives "typeStatus" as "paratype" for this record, but the specimen is not a paratype of Rytus howittii. In the GBIF download, the "typeStatus" field is blank for all records. I understand this may change in future. If it does, I hope the specimen doesn't become a paratype of Tyraphus howitti through copying from ALA.

There are lots of "Telephone" changes in non-taxonomic fields as well, including some geographical howlers. ALA says that a Kakadu National Park record is from Zambia and another Northern Territory record is from Mozambique, because ALA trusts the incorrect longitude provided by NMV more than it does the NMV-supplied locality text. GBIF blanks this locality text field, leaving the GBIF user with two African records for Australian specimens and no internal contradictions.

ALA trusts latitude/longitude to the extent of changing the "stateProvince" field for localities near Australian State borders, if a low-precision latitude/longitude places the occurrence a short distance away in an adjoining State.

Manglings are particularly numerous in the "recordedBy" field, where name strings are reformatted, not always successfully. Complex NMV strings suffer worst, e.g. "C Oke; Charles John Gabriel" in NMV becomes "Oke, C.|null" in ALA, and "Ms Deb Malseed - Winda-Mara Aboriginal Corporation WMAC; Ms Simone Sailor - Winda-Mara Aboriginal Corporation WMAC" is reformatted as in ALA "null|null|null|null"

Most of the "Telephone" effect in the NMV-ALA-GBIF comparison appears in the NMV-ALA stage. I contacted ALA by email and posted some of the issues on the ALA GitHub site; I haven't had a response and the issues are still open. I also contacted Tim Robertson at GBIF, who tells me that GBIF is working on the ALA-GBIF stage.

Can you get data as originally supplied by NMV to ALA, through ALA? Well, that's easy enough record-by-record on the ALA website, but not so easy (or not possible) for a multi-record download. Same with GBIF, but in this case the "original" data are the ALA versions.

Friday, September 30, 2016

Guest post: It's 2016 and your data aren't UTF-8 encoded?

Bob mesibov The following is a guest post by Bob Mesibov.

According to w3techs, seven out of every eight websites in the Alexa top 10 million are UTF-8 encoded. This is good news for us screenscrapers, because it means that when we scrape data into a UTF-8 encoded document, the chances are good that all the characters will be correctly encoded and displayed.

It's not quite good news for two reasons.

In the first place, one out of eight websites is encoded with some feeble default like ISO-8859-1, which supports even fewer characters than the closely related windows-1252. Those sites will lose some widely-used punctuation when read as UTF-8, unless the webpage has been carefully composed with the HTML equivalents of those characters. You're usually safe (but see below) with big online sources like Atlas of Living Australia (ALA), APNI, CoL, EoL, GBIF, IPNI, IRMNG, NCBI Taxonomy, The Plant List and WoRMS, because these declare a UTF-8 charset in a meta tag in webpage heads. (IPNI's home page is actually in ISO-8859-1, but its search results are served as UTF-8 encoded XML.)

But a second problem is that just because a webpage declares itself to be UTF-8, that doesn't mean every character on the page sings from the Unicode songbook. Very odd characters may have been pulled from a database and written onto the page as-is. In ALA I recently found an ancient rune — the High Octet Preset control character (HOP, hex 81):

http://biocache.ala.org.au/occurrences/6191ca90-873b-44f8-848d-befc29ad7513 http://biocache.ala.org.au/occurrences/5077df1f-b70a-465b-b22b-c8587a9fb626

HOP replaces ü on these pages and is invisible in your browser, but a screenscrape will capture the HOP and put SchHOPrhoff in your UTF-8 document.

Another example of ALA's fidelity to its sources is its coding of the degree symbol, which is a single-byte character (hex b0) in windows-1252, e.g. in Excel spreadsheets, but a two-byte character (hex c2 b0) in Unicode. In this record, for example:

http://biocache.ala.org.au/occurrences/5e3a2e05-1e80-4e1c-9394-ed6b37441b20

the lat/lon was supplied (says ALA) as 37°56'9.10"S 145° 0'43.74"E. Or was it? The lat/lon could have started out as 37°56'9.10"S 145°0'43.74"E in UTF-8. Somewhere along the line the lat/lon was converted to windows-1252 and the ° characters were generated, resulting in geospatial gibberish.

When a program fails to understand a character's encoding, it usually replaces the mystery character with a ?. A question mark is a perfectly valid character in commonly used encodings, which means the interpretation failure gets propagated through all future re-uses of the text, both on the Web and in data dumps. For example,

http://biocache.ala.org.au/occurrences/dfbbc42d-a422-47a2-9c1d-3d8e137687e4

gives N?crophores for Nécrophores. The history of that particular character failure has been lost downstream, as is the case for myriads of other question marks in online biodiversity data.

In my experience, the situation is much worse in data dumps from online sources. It's a challenge to find a dump without question marks acting as replacement characters. Many of these question marks appear in author and place names. Taxonomists with eastern European names seem to fare particularly badly, sometimes with more than one character variant appearing in the same record, as in the Australian Faunal Directory (AFD) offering of Wêgrzynowicz, W?grzynowicz and Węgrzynowicz for the same coleopterist. Question marks also frequently replace punctuation, such as n-dashes, smart quotes and apostrophes (e.g. O?Brien (CoL) and L?Échange and d?Urville (AFD)).

Character encoding issues create major headaches for data users. It would be a great service to biodiversity informatics if data managers compiled their data in UTF-8 encoding or took the time to convert to UTF-8 and fix any resulting errors before publishing to the Web or uploading to aggregators.

This may be a big ask, given that at least one data manager I've talked to had no idea how characters were encoded in the institution's database. But as ALA's Miles Nicholls wrote back in 2009, "Note that data should always be shared using UTF-8 as the character encoding". Biodiversity informatics is a global discipline and UTF-8 is the global standard for encoding.

Readers needing some background on character encoding will find this and especially this helpful, and a very useful tool to check for encoding problems in small blocks of text is here.

Friday, April 08, 2016

Guest post: 10 explanations for messy data, by Bob Mesibov

The follow is a guest post by Bob Mesibov, who has contributed to iPhylo before. Bob

Like many iPhylo readers, I deal with large, pre-existing compilations of biodiversity data. The compilations come from museums, herbaria, aggregation projects and government agencies. For simplicity in what follows and to avoid naming names, I'll lump all these sources into a single fictional entity, the PAI (for Projects, Agencies and Institutions).

The datasets I get from the PAI typically contain duplicate records, inconsistencies in content and format, unexplained data gaps, data in wrong fields, fields improperly used, no flagging of doubtful data, etc. Data cleaning consumes most of the time I spend on a data project. Cleaning can take weeks, analysing the cleaned data takes minutes, reporting the results of the analysis takes hours or days. (Example: doi:10.3897/BDJ.2.e1160)

I can understand how datasets get messy. Data entry errors account for a lot of the problems I see, and I make data entry errors myself. But the causes of messiness are one thing and its cure is another. The custodians of those data compilations don't seem to have done much (or any) data checking. Why not?

When I'm brave enough to ask that question, I usually get a polite response from the PAI. Here are 10 explanations I've heard for inadequate data checking and cleaning:

(1) The data are fit for use, as-is. No cleaning is needed, because the data are fit for some use, and the PAI is satisfied with that. One data manager wrote to me in an email: '...even records with lower certainty, in this case an uncertain identification, can be useful at a coarser resolution. Although we have no idea as to the reliability of the identification to the species or even genus they are likely correctly identify[ing] something as at least an animal, arthropod and possibly to class so the record is suitable for analysis at that level.'

(2) The PAI is exposing its data online. The crowd will spot any problems and tell the PAI about them.

I've previously pointed out (doiL10.3897/zookeys.293.5111) how lame this explanation is. As a strategy for data cleaning it's slow, piecemeal and wildly optimistic. At best, it accumulates data-cleaning 'tickets' with no guarantee that any will ever be closed. What I hear from the PAI is 'We're aware of problems of that kind and are hoping to find a general solution, rather than deal with a multitude of individual cases'. Years pass and the individual cases don't get fixed, so interested members of the crowd lose faith in the process and stop reporting problems.

(3) No one outside the PAI is allowed to look at the whole dataset, and no one inside the PAI has the time (or skills) to do data checking and cleaning.

This is a particularly nice Catch-22. I once offered to check a portion of the PAI's data holdings for free, and was told that PAI policy was that the dataset was not to be shared with anyone outside the PAI. The same data were freely available on the PAI's website in bits and pieces through a database search page.

(4) The PAI is migrating to new database software next year. Data cleaning will be part of the migration.

No, it won't. Note that this response isn't always simple procrastination, because it's sometimes the case that the PAI's database has only limited capabilities for data checking and editing. PAI staff are hopeful that checking and editing will be easier with the new software. They'll be disappointed.

(5) The person who manages data is on leave / was seconded to another project / resigned and hasn't been replaced yet / etc.

This is another way of saying that no one inside the PAI has the time to do data checking and cleaning. When the data manager returns to work or gets replaced, data checking and cleaning will have the same low priority it had before. That's why it didn't get done.

(6) Top management says any data cleaning would have to be done by outside specialists, but there's not enough money in the current budget to hire such people.

Not only a Catch-22, but a solid, long-term excuse, applicable in any financial year. It would cost less to train PAI staff to do the job in-house.

(7) The PAI would prefer to use a specialist data tool to clean data, like OpenRefine, but hasn't yet got up to speed on its use.

The PAI believes in magic. OpenRefine will magically clean the data without any thought required on the part of PAI staff. The magic will have to be applied repeatedly, because the sources of the duplications, gaps and errors haven't been found and squashed.

(8) The PAI staff best qualified to check and clean the data aren't allowed to do so.

IT policy strictly forbids anyone but IT staff from tinkering with the PAI database, whose integrity is sacrosanct. A very specific request from biodiversity staff may be ticketed by IT staff for action, but global checking and editing is out of the question. IT staff are not expected to understand biodiversity studies, and biodiversity staff are not expected to understand databases.

This explanation is interesting because it implies a workaround. If a biodiversity staffer can get a dump from the database as a simple text file, she can do global checking and editing of the data using the command line or a spreadsheet. The cleaned data can then be passed to IT staff for incorporation into the database as replacement data items. The day that happens, pigs will be seen flying outside the PAI windows.

(9) The PAI datasets have grown so big that global data checking and editing is no longer possible.

Harder, yes; impossible, no. And the datasets didn't suddenly appear, they grew by accretion. Why wasn't data checking and editing done as data was added?

(10) All datasets are messy and data users should do their own data cleaning.

The PAI shrugs its shoulders and says 'That's just the way it is, live with it. Our data are no messier than anyone else's'.

I've left this explanation for last because it begs the question. Yes, users can do their own data cleaning — because it's not that hard and there are many ways to do it. So why isn't it done by highly qualified, well-paid PAI data managers?

Tuesday, December 09, 2014

Guest post: Top 10 species names and what they mean

The following is a guest post by Bob Mesibov. Bob

The i4Life project has very kindly liberated Catalogue of Life (CoL) data from its database, and you can now download the latest CoL as a set of plain text, tab-separated tables here.

One of the first things I did with my download was check the 'taxa.txt' table for species name popularity*. Here they are, the top 10 species names for animals and plants, with their frequencies in the CoL list and their usual meanings:

Animals


2732 gracilis = slender
2373 elegans = elegant
2231 bicolor = two-coloured
2066 similis = similar
1995 affinis = near
1937 australis = southern
1740 minor = lesser
1718 orientalis = eastern
1708 simplex = simple
1350 unicolor = one-coloured

Plants


1871 gracilis = slender
1545 angustifolia = narrow-leaved
1475 pubescens = hairy
1336 parviflora = few-flowered
1330 elegans = elegant
1324 grandiflora = large-flowered
1277 latifolia = broad-leaved
1155 montana = (of a) mountain
1124 longifolia = long-leaved
1102 acuminata = pointed

Take the numbers cum grano salis. The first thing I did with the CoL tables was check for duplicates, and they're there, unfortunately. It's interesting, though, that gracilis tops the taxonomists' poll for both the animal and plant kingdoms.

*With the GNU/Linux commands


awk -F"\t" '($11 == "Animalia") && ($8 == "species") {print $20}' taxa.txt | sort | uniq -c | sort -nr | head
awk -F"\t" '($11 == "Plantae") && ($8 == "species") {print $20}' taxa.txt | sort | uniq -c | sort -nr | head

Thursday, May 02, 2013

GBIF data quality: visualising Mesibov's millipedes


Bob Mesibov (who has been a guest author on this blog) recently published a paper on data quality in in ZooKeys:

Mesibov, R. (2013). A specialist’s audit of aggregated occurrence records. ZooKeys, 293(0), 1–18. doi:10.3897/zookeys.293.5111

In this paper Bob documents some significant discrepancies between data in his
Millipedes of Australia (MoA) database and the equivalent data in the Atlas of Living Australia and GBIF (disclosure, I was a reviewer of the paper, and also sit on GBIF's science committee). This paper spawned a thread on TAXACOM, and also came up at the GBIF meeting I was at earlier this week.

One thing lacking from the discussion is a clear sense of just how big are the discrepancies between GBIF and MoA data, so I grabbed the data provided by Bob (http://dx.doi.org/10.3897/zookeys.293.5111.app and extracted the records where GBIF and MoA disagreed. I converted these to GeoJSON and threw them on Google Maps:

Mesibov2

You can see a live version here http://bl.ocks.org/rdmpage/raw/5501293/ (it can take a little while for the map to appear). I've connected the MoA and GBIF localities for the same occurrence by a straight line, and the the MoA records are encircled by an estimate of their uncertainty (for many records the circle is invisible at this scale).

There are some fairly spectacular discrepancies, and a lot of relatively small scale displacements of records. Does this matter? The answer to this question will depend on what people want to do with the data. You may regard the discrepancies as serious (certainly it's interesting that there are so many differences between the two data sets), or minor given the geographic scale. But visualising them at least makes it possible to form a judgement.

Thursday, July 12, 2012

Dimly lit taxa - guest post by Bob Mesibov

The following is a first for iPhylo, a guest post by Bob Mesibov. Bob

Rod Page introduced 'dark taxa' here on iPhylo in April 2011. He wrote:

The bulk of newly added taxa in GenBank are what we might term "dark taxa", that is, taxa that aren't identified to a known species. This doesn't necessarily mean that they are species new to science, we may already have encountered these species before, they may be sitting in museum collections, and have descriptions already published. We simply don't know. As the output from DNA barcoding grows, the number of dark taxa will only increase, and macroscopic biology starts to look a lot like microbiology.

Rod suggested that 'quite a lot' of biology can be done without taxonomic names. For the dark taxa in GenBank, that might well mean doing biology without organisms – a surprising thought if you're a whole-organism biologist.

Non-taxonomists may be surprised to learn that a lot of taxonomy is also done, in fact, without taxonomic names. Not only is there a 'dark taxa' gap between putative species identified genetically and Linnaean species described by specialists, there's a 'dimly lit taxa' gap between the diversity taxonomists have already discovered, and the diversity they've named.

Dimly lit taxa range from genera and species given code names by a specialist or a group of collaborators, and listed by those codes in publications and databases, to potential type specimens once seen and long remembered by a specialist who plans to work them up in future, time and workload permitting.

In that phrase 'time and workload permitting' is a large part of the explanation for dimly lit taxa. Over the past month I created 71 species of this kind myself. Each has been code-named, diagnostically imaged, databased and placed in code-labelled bottles on museum shelves. The relevant museums have been given digital copies of the images and data.

The 71 are 'species-in-waiting'. They aren't formally named and described, but specialists like myself can refer to the images and data for identifying new specimens, building morphological and biogeographical hypotheses, and widening awareness of diversity in the group to which the 71 belong.

'Time and workload permitting'. Many of the 71 are poor-quality or fragmented museum specimens from which important morphological data, let alone sequences, cannot be obtained. Fresh specimens are needed, and fieldwork is neither quick nor easy. In my special corner of zoology, as in most such corners in zoology and botany, the widespread and abundant species are all, or nearly all, named. The unnamed rump consists of a huge diversity of geographically restricted and uncommon species. There are more than 71 in that group of mine; those are just the rare species I know about, so far.

'Time and workload permitting'. A non-taxonomist might ask, 'Why don't you just name and describe the 71 briefly, so that the names are at least available, and the gap between what's known and what's named is narrowed?' The answer is simple: inadequate descriptions are the bane of taxonomy. There are hundreds of species in my special group that were named and inadequately described long ago, and which wind up on checklists of names as 'nomen dubium' and 'incertae sedis'. Clearing up the mysteries means locating the types (which hopefully still exist) and studying them. That slow and tedious study would better have been done by the first describer.

Cybertaxonomic tools can help bring dimly lit taxa into full light, but not much. The rate-limiting steps in lighting up taxa are in the minds and lives of human taxonomists coping with the huge and bewilderingly complex diversity of life. It's not the tools used after the observing and thinking is done, it's the observing and thinking.

In their article 'Ramping up biodiversity discovery via online quantum contributions' (http://dx.doi.org/10.1016/j.tree.2011.10.010), Maddison et al. argue that the pace of naming and description can be increased if information about what I've called dimly lit taxa is publicly posted, piece by piece, 'publish as you go', on the Internet. In my case, I would upload images and data for my 71 'species-in-waiting' to suitable sites and make them freely available.

Excited by these discoveries, amateurs and professionals would rush to search for fresh specimens. Specialists would drop whatever else they were doing, borrow the existing specimens of the 71 from their repositories and do careful inventories of the morphological features I haven't documented. Aroused from their humdrum phylogenetic analyses of other organisms, molecular phylogeny labs would apply for extra funding to work on my 71 dimly lit taxa. In no time at all, a proud team of amateurs and specialists would be publishing the results of their collaboration, with 71 names and descriptions.

Shortly afterwards, flocks of pigs would slowly circle the 71 type localities, flapping their wings in unison.

Memo to Maddison et al. and other would-be reformers: the rate of taxonomic discovery and documentation is very largely constrained by the supply of taxonomists. You want more names, find more namers.